
Yandex search
Yandex search results, images, and SERP data via the Apify Yandex Search Scraper, hosted MCP.
One address for any MCP client. Your key stays in your Odel vault.
What it does
- Reads
- Writes
- High impact
At most: only reads or looks up information.
What it costs
FreeOdel charges nothing per call. The publisher may charge for its own service.
What it asks for at sign-in
| Access to | Read | Change |
|---|---|---|
| Full api access | Not stated: full_api_access | |
From the sign-in at console-backend.apify.com, as the endpoint publishes it. You approve it there.
Tools
None listed · checked 11 Oct 2026Odel could not list its tools without signing in.
English | Русский
🔎 Yandex API: Structured Yandex Search Results in Clean JSON
The most efficient, reliable, and developer-friendly way to use the Yandex API.
Actor page: apify.com/johnvc/Scrape-Yandex Input schema: apify.com/johnvc/Scrape-Yandex/input-schema
The Yandex API runs a Yandex search for any query and returns clean, structured JSON. Choose the result types you want a la carte (organic listings, paid ads, knowledge graph entity cards, inline image panels, inline video panels); each selected type comes back as its own item tagged with item_type, plus per-page metadata. It supports 6 Yandex domains, 19 languages, and region targeting across 123,000+ locations, with sort/recency filters and fast parallel pagination.
Video Walkthrough
Quick Start
Prerequisites
- Python 3.11 or higher
- An Apify account and API key (get a free key here)
-
Clone the repository
bashgit clone https://github.com/johnisanerd/Apify-Yandex-Search-Scraper.git cd Apify-Yandex-Search-Scraper -
Install dependencies with UV
bash# Install UV if you do not have it: curl -LsSf https://astral.sh/uv/install.sh | sh # Install project dependencies: uv sync -
Configure your API key
bashcp .env.example .env # Edit .env and add your Apify API key # Get your free API key at: https://apify.com?fpr=9n7kx3 -
Run the example
bashuv run python yandex-scraper.py
Alternative: set the API key directly
export APIFY_API_TOKEN="your_api_key_here"
uv run python yandex-scraper.py
Why Use This Yandex API?
Full results-page coverage. One call returns the whole Yandex results page as structured data: organic listings, paid ads, knowledge graph entity cards, inline image panels, and inline video panels. You get the entire page, not just the organic links.
Built for Russian-speaking and CIS markets. Target 6 Yandex domains (yandex.com, yandex.ru, yandex.by, yandex.kz, yandex.uz, yandex.com.tr), 19 languages, and any of 123,000+ region IDs. That makes it practical for SEO, competitive intelligence, and brand monitoring across Russia, Eastern Europe, Central Asia, and beyond.
Predictable, pay-per-use pricing. Billing is per run plus per page processed, with no monthly rental. You pay for the searches you actually make, and you control cost directly with the page limit.
Clean, consistent JSON. Every page is a structured dataset item with the same shape, so you parse results once and reuse the code across queries, domains, and languages.
Easy to automate. Call it from Python in a few lines, or load it as an MCP tool so assistants like Claude and Cursor can run Yandex searches for you on demand.
Features
Core Capabilities
- Keyword search across Yandex with full results-page extraction
- A la carte result types: toggle organic results, ads, knowledge graph, inline images, and inline videos independently; each selected type is returned as its own item tagged with
item_type - Domain localization across 6 Yandex domains
- Language targeting with 19 supported languages
- Region targeting with 123,000+ location IDs (the
lrparameter) - Sort and recency filters:
sort_mode(relevance or date) andperiod(all, day, last_two_weeks, month) - Safe search and typo correction controls, plus fast parallel multi-page pagination
Data Quality
- Structured organic results with title, link, snippet, position, displayed link, date, and sitelinks
- Rich result blocks: ads, knowledge graph, inline images, inline videos, each with a
result_count - Per-page metadata with domain, language, location, and pagination details
- Consistent JSON shape across every query
- Per-page billing so larger searches stay transparent
Usage Examples
Basic Example
A single-page search for one keyword. This is the cheapest way to try the API.
{
  "text": "machine learning",
  "yandex_domain": "yandex.com",
  "max_pages": 1
}
Advanced Example
A Russian-domain search with Russian language, a region ID, more results per page, and two pages.
{
  "text": "машинное обучение",
  "yandex_domain": "yandex.ru",
  "lang": "ru",
  "lr": 225,
  "groups_on_page": 20,
  "family_mode": 1,
  "max_pages": 2
}
A la carte: collect ads and the knowledge graph
Enable just the result types you want. Here organic is off and only ads plus the knowledge graph are returned, each as its own item.
{
  "text": "best running shoes",
  "include_organic_results": false,
  "include_ads": true,
  "include_knowledge_graph": true,
  "max_pages": 1
}
Fresh results: sort by date, last two weeks
Use sort_mode and period to focus on recent content. They apply to every selected result type.
{
  "text": "ai news",
  "yandex_domain": "yandex.ru",
  "lang": "ru",
  "sort_mode": "date",
  "period": "last_two_weeks",
  "max_pages": 1
}
Input Parameters
| Parameter | Type | Required | Default | Description |
|---|---|---|---|---|
text | string | Yes | - | The search query. Supports Yandex operators such as site:wikipedia.org python. |
include_organic_results | boolean | No | true | Return organic results (item_type organic). |
include_ads | boolean | No | false | Return paid ads when present (item_type ads). |
include_knowledge_graph | boolean | No | false | Return the knowledge graph card when present (item_type knowledge_graph). |
include_inline_images | boolean | No | false | Return the inline image strip (item_type inline_images). |
include_inline_videos | boolean | No | false | Return the inline video carousel (item_type inline_videos). |
yandex_domain | string | No | yandex.com | Yandex domain, e.g. yandex.ru, yandex.com.tr, yandex.kz (6 supported). |
lang | string | No | en | Language code, e.g. ru, en, tr, de (19 supported); null for unspecified. |
lr | integer | No | (domain default) | Region ID, e.g. 225 = Russia, 84 = United States, 149 = Belarus. 123,000+ IDs; see the Actor page for the full table. |
max_pages | integer | No | 2 | Maximum pages to fetch (0 = no limit). Applies to every selected result type. |
sort_mode | string | No | relevance | Result ordering: relevance or date (newest first). |
period | string | No | all | Recency window: all, day, last_two_weeks, month. |
groups_on_page | integer | No | 10 | Results per page (1 to 20). |
family_mode | integer | No | 1 | Safe search: 0 = off, 1 = moderate, 2 = strict. |
fix_typo | boolean | No | true | Auto-correct spelling errors in the query. |
output_file | string | No | (none) | Optional filename to save results; auto-generated if omitted. |
Output Format
Each selected result type present on a page is returned as its own dataset item, tagged with item_type (organic, ads, knowledge_graph, inline_images, or inline_videos) and a result_count. A representative organic item for the query Apple is shown below; arrays and some fields are trimmed here for readability.
{
  "item_type": "organic",
  "result_count": 10,
  "text": "Apple",
  "yandex_domain": "yandex.com",
  "lang": "en",
  "lr": "84",
  "page_number": 1,
  "search_domain": "yandex.com",
  "search_domain_description": "United States",
  "search_language": "en",
  "search_language_description": "English",
  "search_location": "84",
  "total_results_found": 10,
  "pages_processed": 1,
  "total_pages": 1,
  "max_pages_set": 1,
  "results_per_page": 10,
  "pagination_limit_reached": true,
  "pagination_stopped_by_limit": true,
  "organic_results": [
    {
      "position": 1,
      "title": "Apple",
      "link": "https://www.apple.com/",
      "displayed_link": "apple.com",
      "snippet": "Apple Payments Services LLC, a subsidiary of Apple Inc., is a service provider of Goldman Sachs Bank USA for Apple Card and Savings accounts."
    },
    {
      "position": 3,
      "title": "Apple Inc. - Wikipedia",
      "link": "https://en.m.wikipedia.org/wiki/Apple_Inc.",
      "displayed_link": "en.m.wikipedia.org",
      "snippet": "Apple Inc. is an American multinational corporation and technology company headquartered in Cupertino, California, in Silicon Valley."
    }
  ],
  "ads_results": [],
  "knowledge_graph": [
    {
      "title": "Apple Inc.",
      "description": "American multinational technology company headquartered in Cupertino, California.",
      "source": { "name": "en.wikipedia.org" }
    }
  ],
  "inline_images": [],
  "inline_videos": []
}
Use as an MCP tool
You can load the Yandex API as an MCP tool so assistants call it for you. The MCP server URL preloads just this one Actor:
https://mcp.apify.com/?tools=actors,docs,johnvc/Scrape-Yandex
Authenticate with OAuth in the browser when offered, or with your Apify API token (the same APIFY_API_TOKEN used by the Python example). Get a token at https://console.apify.com/settings/integrations and a free Apify account at https://apify.com?fpr=9n7kx3 .
Install in Claude Cowork Desktop
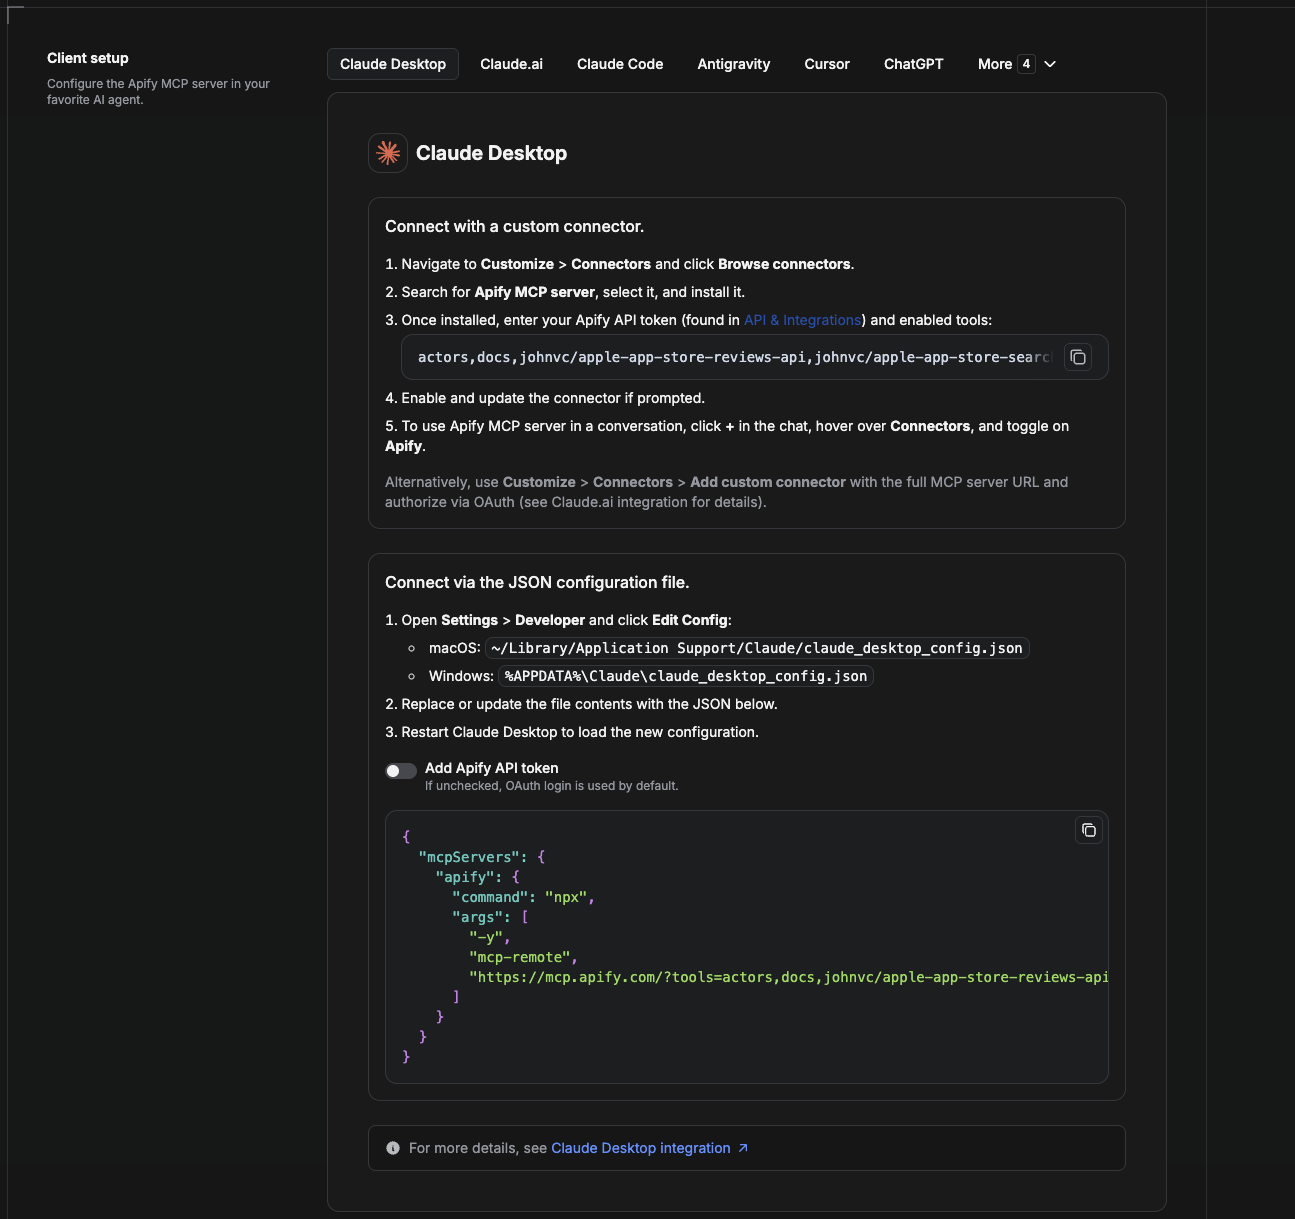
Cowork is the desktop app's automation mode. To give it the Yandex API as a tool, add the Apify MCP server as a connector.
- Open the Claude desktop app and go to Settings → Connectors (or Settings → Developer → Edit Config to edit
claude_desktop_config.jsondirectly).- macOS:
~/Library/Application Support/Claude/claude_desktop_config.json - Windows:
%APPDATA%\Claude\claude_desktop_config.json
- macOS:
- Add the Apify MCP server, preloaded with only this Actor:
{
  "mcpServers": {
    "apify": {
      "command": "npx",
      "args": [
        "-y",
        "mcp-remote",
        "https://mcp.apify.com/?tools=actors,docs,johnvc/Scrape-Yandex"
      ]
    }
  }
}
- Restart the app. When Cowork first calls the tool, complete the OAuth prompt in your browser, or add your Apify API token in the connector settings to skip OAuth.
- In a Cowork chat, confirm the tool is available and ask it to run the Yandex API.
Download the desktop app and start a free trial: https://claude.ai/referral/uIlpa7nPLg More help: https://docs.apify.com/platform/integrations/claude-desktop
Install in Claude Code
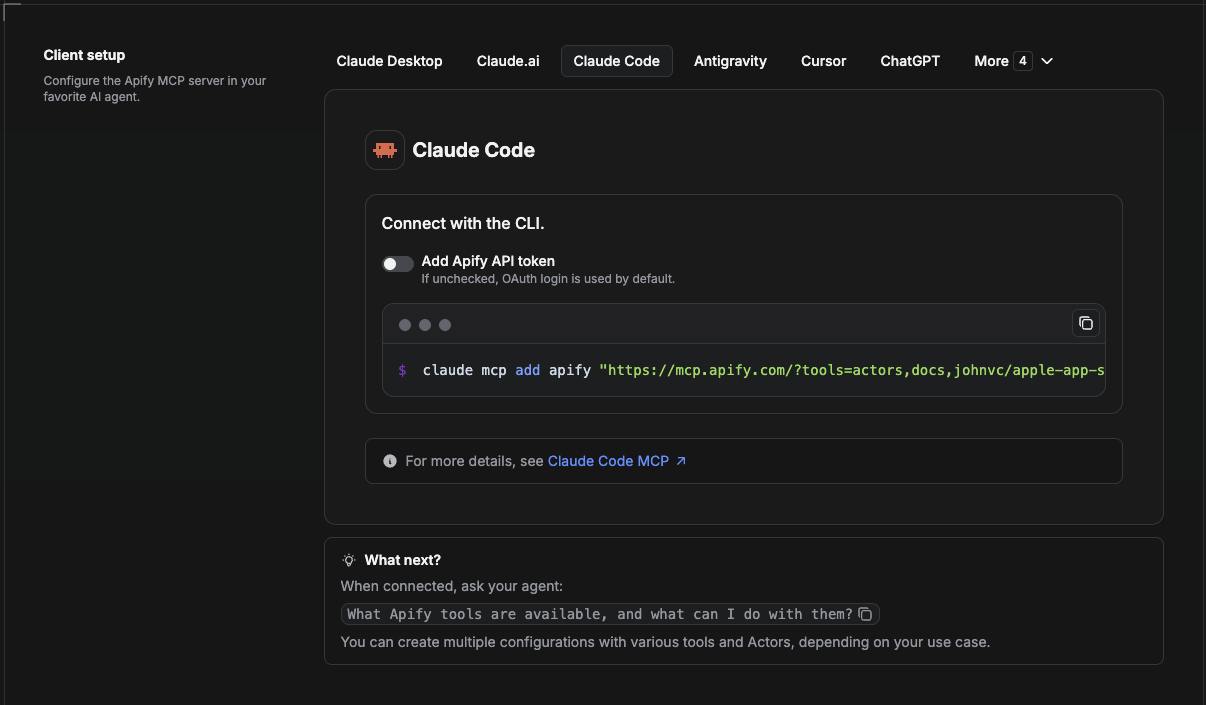
Claude Code is the command-line tool. Add the Actor's MCP server with one command:
claude mcp add --transport http apify \
  "https://mcp.apify.com/?tools=actors,docs,johnvc/Scrape-Yandex"
To use a token instead of browser OAuth:
claude mcp add --transport http apify \
  "https://mcp.apify.com/?tools=actors,docs,johnvc/Scrape-Yandex" \
  --header "Authorization: Bearer YOUR_APIFY_TOKEN"
Then verify with claude mcp list, or run /mcp inside a session. Ask Claude Code to call the Yandex API.
Try Claude Code free: https://claude.ai/referral/uIlpa7nPLg Claude Code MCP docs: https://code.claude.com/docs/en/mcp
Install in Claude (website)
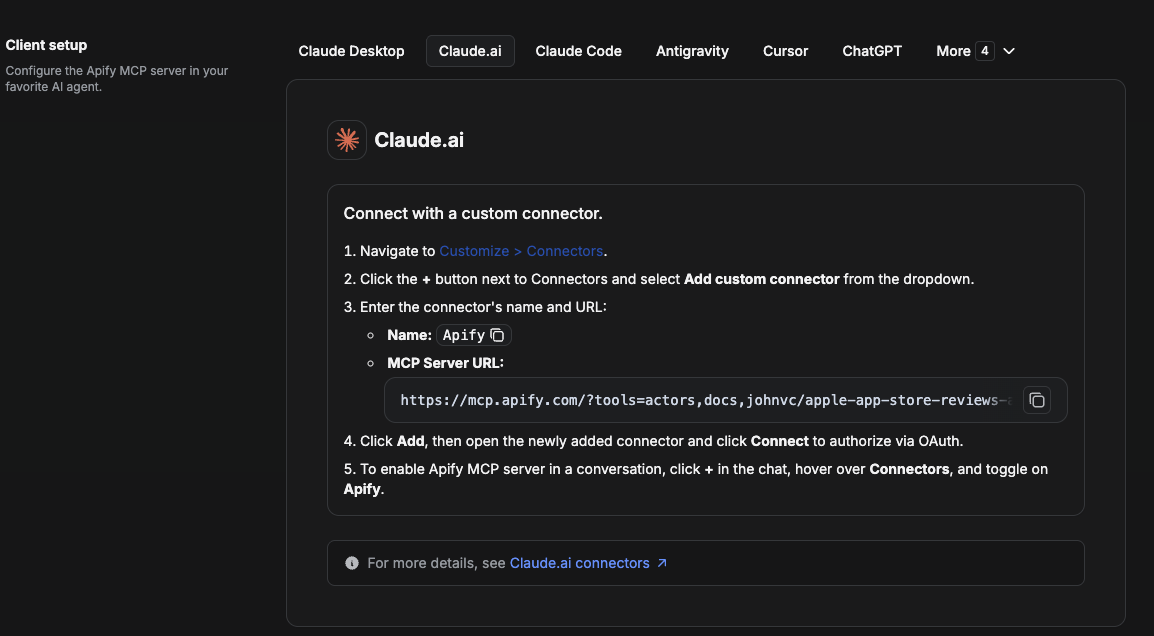
On claude.ai you add Apify as a connector, then enable just this Actor's tool.
- Go to Settings → Connectors → Browse connectors and search for Apify MCP server. Install it (enable or update if prompted).
- When connecting, authenticate with your Apify API token, and enable the tool
johnvc/Scrape-Yandex. - In any chat, open + → Connectors and turn on Apify.
- Alternatively, choose Add custom connector and paste the full MCP URL
https://mcp.apify.com/?tools=actors,docs,johnvc/Scrape-Yandex, using OAuth when prompted. - Ask Claude to run the Yandex API.
Open Claude on the web: https://claude.ai/referral/uIlpa7nPLg
Install in Cursor
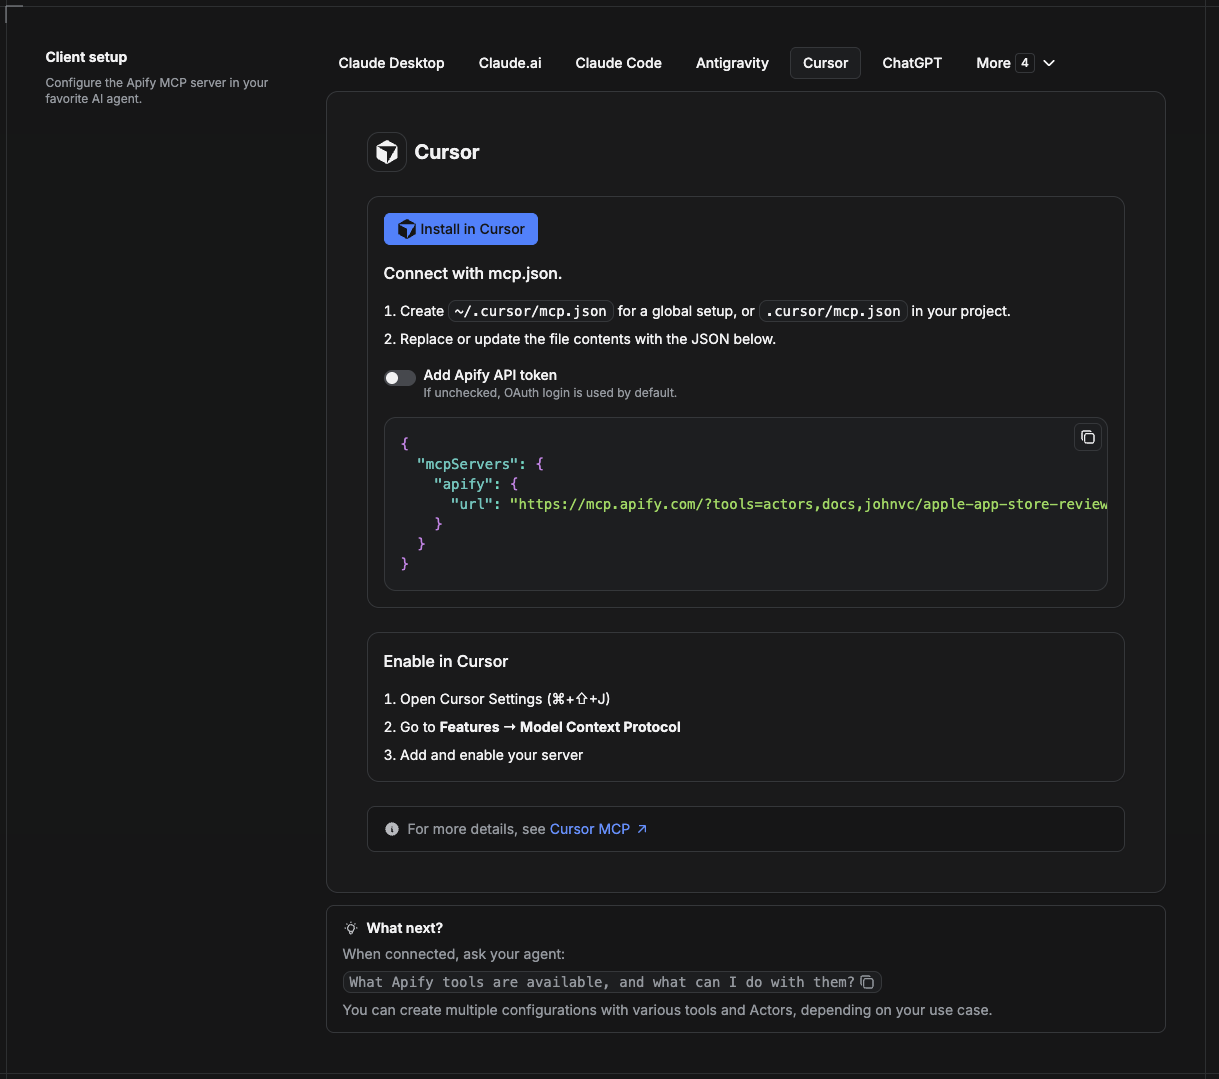
Cursor reads MCP servers from a project file at .cursor/mcp.json.
- In your project, create
.cursor/mcp.json:
{
  "mcpServers": {
    "apify": {
      "url": "https://mcp.apify.com/?tools=actors,docs,johnvc/Scrape-Yandex"
    }
  }
}
- If you prefer token auth over browser OAuth, add a header:
{
  "mcpServers": {
    "apify": {
      "url": "https://mcp.apify.com/?tools=actors,docs,johnvc/Scrape-Yandex",
      "headers": { "Authorization": "Bearer YOUR_APIFY_TOKEN" }
    }
  }
}
- Open Cursor → Settings → MCP and confirm the apify server is connected (green dot).
- In Composer or Chat, ask Cursor to call the Yandex API.
New to Cursor? Get it here: https://cursor.com/referral?code=XQP4VBLI3NNX
Install in ChatGPT
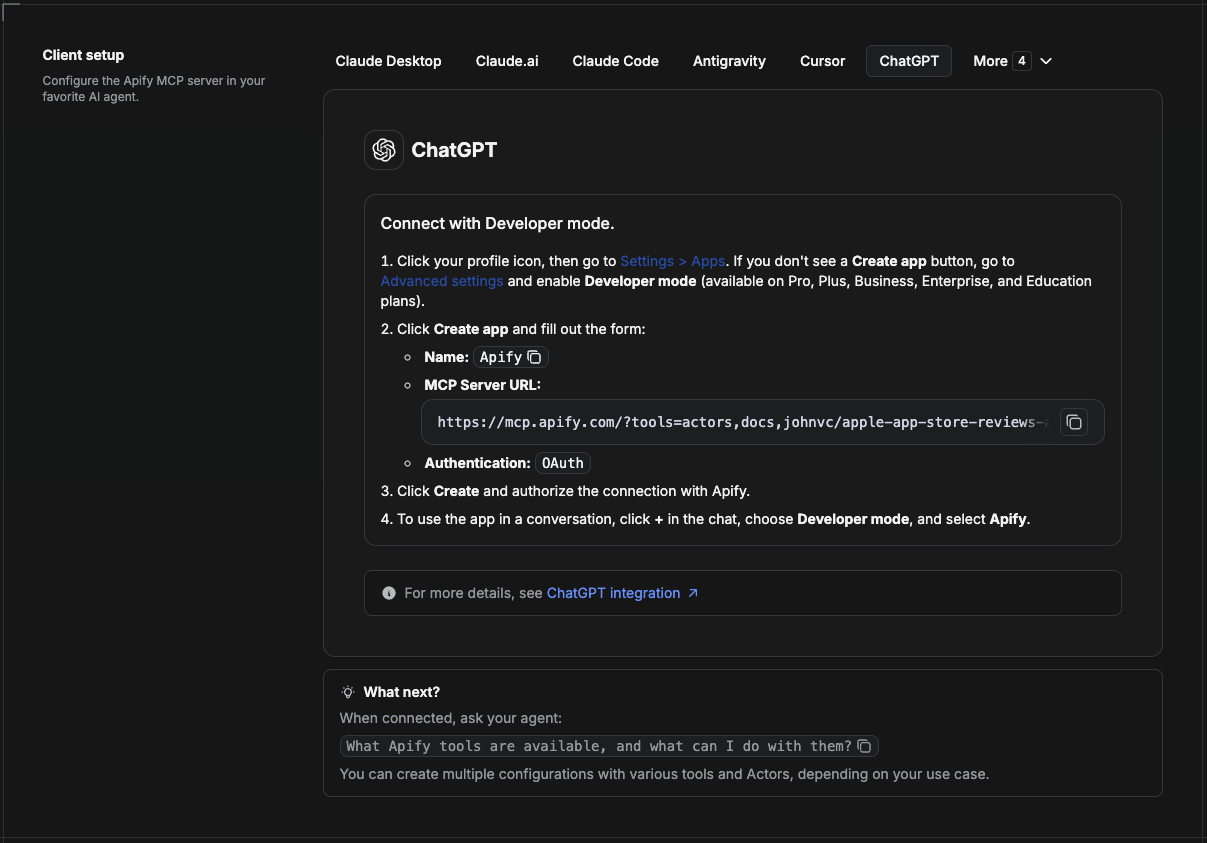
ChatGPT connects to the Apify MCP server through Developer mode (available on ChatGPT Pro, Plus, Business, Enterprise, and Education plans).
- Click your profile icon, then go to Settings > Apps. If you do not see a Create app button, open Advanced settings and enable Developer mode.
- Click Create app and fill out the form:
- Name: Apify
- MCP Server URL:
https://mcp.apify.com/?tools=actors,docs,johnvc/Scrape-Yandex - Authentication: OAuth
- Click Create and authorize the connection with Apify.
- To use the app in a conversation, click + in the chat, choose Developer mode, and select Apify.
More help: https://docs.apify.com/platform/integrations/mcp
Use the Yandex API to power your search and SEO workflows with reliable, structured results.
🤖 Ask an AI assistant about this Actor
Open a ready-to-send prompt about the Yandex Search API in the AI of your choice:
- 💬 ChatGPT
- 🧠 Claude
- 🔍 Perplexity
- 🅒 Copilot
Last Updated: 2026.09.22


