Context Guardian
Compacting proxy for OpenAI-compatible backends, with MCP tools to search the archived history.
Runs on your machine from its package; the steps are below.
What it does
- Reads
- Writes
- High impact
At most: only reads or looks up information.
What it costs
FreeOdel charges nothing per call. The publisher may charge for its own service.
Runs locally over stdio
This server isn't hosted — your MCP client launches it from a package registry. Use one of the commands below, or drop the config into your client (e.g. Claude Desktop).
Run
uvx context-guardian
MCP client config
{
  "mcpServers": {
    "context-guardian": {
      "command": "uvx",
      "args": [
        "context-guardian"
      ]
    }
  }
}Your local-model session hits the context limit and dies. This stops that.





mcp-name: io.github.LuminariSoftwares/context-guardian
Quick start · Works with · Client settings · Examples · Install both · Why · Two ways to run it · Install the proxy · Install in DSH · See it work · Compatibility · Changelog
Compaction for local models that actually fires, and never takes the conversation down with it. Two front doors, one idea: a proxy that sits in front of any OpenAI-compatible backend (Ollama, LiteLLM, Headroom, vLLM, LM Studio) for any CLI or agent, and a native engine for DeepSeek Harness. Both keep the full original on disk, and both fail open.
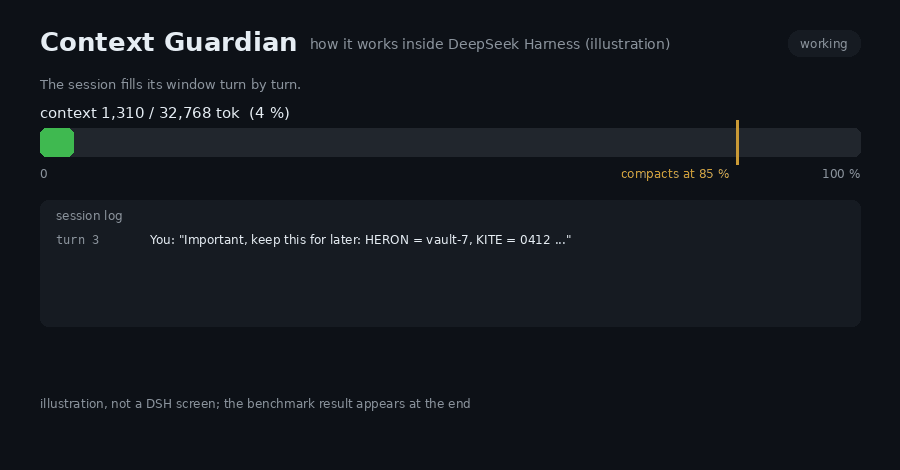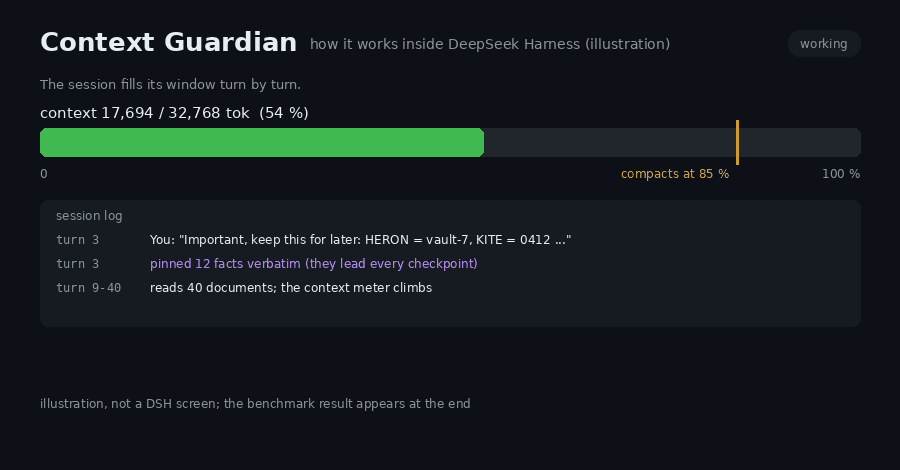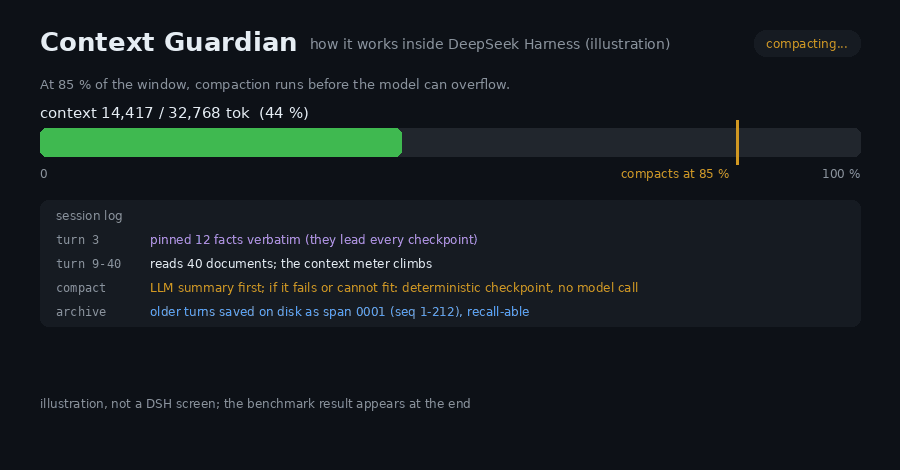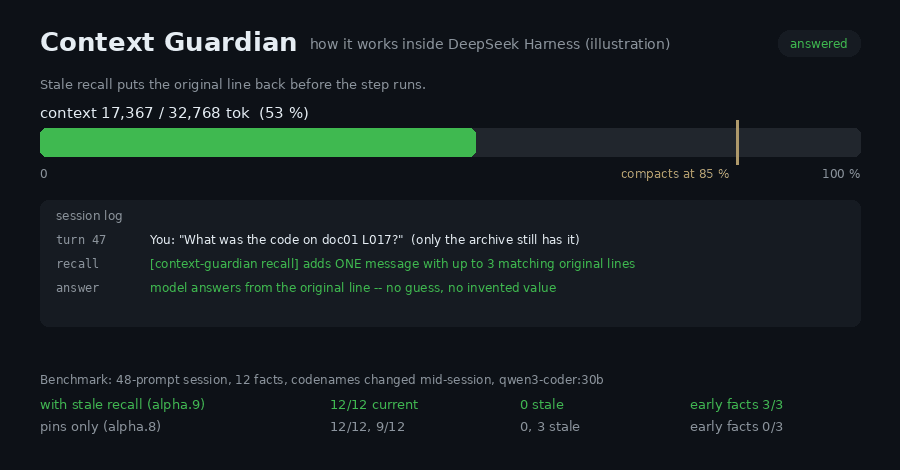
Measured: in a 48-prompt DeepSeek Harness session on qwen3-coder:30b (Ollama, 64K window) with codenames changed mid-session, 0.1.0-alpha.9 kept 12/12 facts current with 0 stale answers and brought back 3/3 early details in every run (n = 3), where pins alone brought back 0/3 (n = 2). Details: Measured.
Works with
| how it hooks in | status | example | |
|---|---|---|---|
| Ollama | proxy: GUARDIAN_UPSTREAM_URL=http://localhost:11434/v1 | tested (daily use, Windows 11) | examples/ollama-proxy |
| LM Studio | proxy: GUARDIAN_UPSTREAM_URL=http://localhost:1234/v1 | expected to work, not tested against LM Studio itself | examples/lmstudio-proxy |
| vLLM | proxy: GUARDIAN_UPSTREAM_URL=http://localhost:8000/v1 | expected to work, untested | copy the Ollama example, change the URL |
| LiteLLM | proxy: GUARDIAN_UPSTREAM_URL=<your LiteLLM proxy>/v1 | expected to work, untested | copy the Ollama example, change the URL |
| DeepSeek Harness | native engine: one row in your agent preset | tested on DSH 0.1.2-alpha.2 | examples/dsh-preset |
The proxy needs only an OpenAI-compatible /v1/chat/completions; your CLI points OPENAI_BASE_URL at it. "Expected" means not yet tested; please open an issue with what you saw. Full matrix: Compatibility.
Quick start
pip install context-guardian && context-guardian   # proxy on :8786 in front of Ollama on :11434; set OPENAI_BASE_URL=http://localhost:8786/v1
context-guardian-doctor                            # second terminal: checks the install and the running proxy, prints a fix: line for anything wrong
Another backend or window: see examples/ or Configure. Your client's settings: Point your client at the proxy. DeepSeek Harness users: install the native engine below.
After a compaction, context-guardian-recall "<term>" searches the archived originals (the summary the model receives names the exact command).
Point your client at the proxy
The proxy compacts OpenAI-style POST /v1/chat/completions requests. Every client below is configured from its own documented settings; none of these four has been tested against the proxy yet, so please open an issue with what you see.
| client | where | what to set |
|---|---|---|
| Claude Code | environment | Claude Code speaks the Anthropic Messages API (/v1/messages). The proxy compacts it too when GUARDIAN_UPSTREAM_URL serves that API (the summary call goes to the same upstream's /messages with your key and goes into system): ANTHROPIC_BASE_URL=http://localhost:8786. Or use an OpenAI-compatible build such as OpenClaude: CLAUDE_CODE_USE_OPENAI=1 OPENAI_BASE_URL=http://localhost:8786/v1 OPENAI_API_KEY=local OPENAI_MODEL=<model> |
| Cline | Settings → API Provider: OpenAI Compatible | Base URL http://localhost:8786/v1 · API Key any non-empty text · Model ID <model> |
| Continue | ~/.continue/config.yaml | under models: add - {name: Context Guardian, provider: openai, model: <model>, apiBase: "http://localhost:8786/v1", apiKey: local} |
| OpenCode | opencode.json | "provider": {"guardian": {"npm": "@ai-sdk/openai-compatible", "name": "Context Guardian", "options": {"baseURL": "http://localhost:8786/v1"}, "models": {"<model>": {}}}} |
<model> is the name your backend serves (for Ollama, what ollama list shows). The proxy forwards the API key unchanged; a local backend ignores it. Then set GUARDIAN_NUM_CTX to that model's real window (Configure).
An illustration of what the DSH engine (0.1.0-alpha.9) does, not a DSH screen. Inside DSH you see it as DSH's own "Context compacted" row and context meter, /context and /guardian for pressure and the last compaction, and the [context-guardian recall] message in the conversation. What happens: at 85 % of the window it compacts, the facts you asked it to keep lead every checkpoint, the old turns stay on disk, and when a later question needs a detail that was compacted away, stale recall puts the original line back before the model answers. The results line is the benchmark in Measured. The proxy has its own monitor: see See it work.
| Without Context Guardian | With it | |
|---|---|---|
| Claude-Code-style CLI on a local model | auto-compact never fires; the backend hard-rejects the request and the session is over | the proxy compacts before the window fills; the session keeps going |
| DSH on a 32K local model (measured: 314 compaction attempts) | 48 succeeded; the rest failed on an empty summary or overflowed the window while summarising | every failed or impossible summary falls back to a deterministic checkpoint: ~14,012 → ~584 tokens in 23 ms, no model call |
| The part that was compacted away | gone | archived on disk; in DSH every checkpoint line carries a seq pointer that recall reads back |
Install both (DeepSeek Harness, about 5 minutes)
Context Guardian and Tool Guardian are two halves of one problem: Tool Guardian keeps tool schemas and tool results from filling the window, and Context Guardian compacts the conversation before it fills and keeps what matters. They share no files and install separately. You need DSH 0.1.2-alpha.2 or later, Node.js ^22.19 or >=24, and Python 3.9+ on PATH for Tool Guardian's router.
# 1. Add both bundles to the DSH profile you use (`web` is the one `dsh web` uses)
dsh plugin --profile web add dsh-tool-guardian
dsh plugin --profile web add dsh-context-guardian

# 2. Tool Guardian: copy in the MCP servers you already use (Claude Desktop / Cursor / Windsurf / .mcp.json), then check them
cd ~/.dsh/profiles/web/node_modules/dsh-tool-guardian          # Windows: cd %USERPROFILE%\.dsh\profiles\web\node_modules\dsh-tool-guardian
npm run setup                  # asks before it writes ~/.tool-guardian/mcp.json, then prints a doctor report

# 3. Context Guardian: add its compaction row to your agent preset (a dry run until --apply)
cd ~/.dsh/profiles/web/node_modules/dsh-context-guardian       # Windows: cd %USERPROFILE%\.dsh\profiles\web\node_modules\dsh-context-guardian
npm run setup
npm run setup -- --apply

# 4. Start DSH and open a NEW session with the preset setup named
dsh web
In that session, type /guardian. It shows Context Guardian's engine revision and your model's window. Then type /toolguardian. It shows each MCP server Tool Guardian started, the tokens the router saves on every request, and whether an update is out.
Not on DSH? Context Guardian's proxy (python context_guardian.py, see its README) works with any OpenAI-compatible CLI. Tool Guardian runs as a plain MCP server for Claude Code, Cursor or any MCP client (see its README).
Two ways to run it
Proxy (context_guardian.py) | DSH engine (engine.js) | |
|---|---|---|
| Works with | anything that talks to an OpenAI-compatible /v1/chat/completions: OpenClaude, Cline, Continue, OpenCode (settings); stock Claude Code passes through uncompacted | DeepSeek Harness 0.1.2+ |
| How it hooks in | you point OPENAI_BASE_URL at it | one row in your agent preset's compaction group |
| Who writes the summary | the same backend model, asked by the proxy | DSH's own summariser first; a deterministic compiler when that fails, returns nothing, or cannot fit |
| Reads originals back | span archive on disk (plain JSON, one file per compaction) | recall / search tools for the model, /recall and /context for you |
| Live view | /guardian/health dashboard with the compaction monitor, /guardian/events | DSH's own "Context compacted" row and context meter, plus one JSON line per decision in guardian_dsh.jsonl |
| Compacts while idle | — | off by default since 0.1.0-alpha.8; set idleCompactRatio (e.g. 0.45) to turn it on |
| Archive format | logs/guardian_spans/<run>/NNNN.json | the same format, so the same tools read both |
| Setup guide | this README | docs/dsh-integration.md |
Hand-off files (DSH engine). At every compaction the engine writes handoff_<session>.json and .md, plus handoff_latest.json, beside memory.json: the session's goal, its current pins and its decisions, so a new session or another agent can pick the work up from them alone.
GUARDIAN_HANDOFF=0 (or handoff: false on the engine row) turns them off; see docs/dsh-integration.md.
flowchart LR
    subgraph P["Proxy: any OpenAI-compatible harness"]
      A1["CLI / agent"] --> G1["Context Guardian<br/>proxy :8786"] --> B1["Ollama / LiteLLM / vLLM"]
      G1 -. "over budget" .-> S1["summarise older turns<br/>keep recent verbatim"]
    end
    subgraph D["Engine: inside DeepSeek Harness"]
      A2["DSH agent"] --> C2["compaction-basic"] --> E2{"LLM summary<br/>fits and works?"}
      E2 -->|yes| K2["LLM checkpoint"]
      E2 -->|no| X2["deterministic checkpoint<br/>with seq pointers"]
    end
    S1 --> Z[("span archive on disk")]
    X2 --> Z
    K2 --> Z
The rest of this page is the proxy. The DSH engine has its own five-minute guide: docs/dsh-integration.md.
Compatibility
| tested on | expected to work | notes | |
|---|---|---|---|
| DeepSeek Harness (engine) | 0.1.2-alpha.2 on Windows 11 | 0.1.2-alpha.2 and later 0.1.x | needs compaction-basic (the standard preset has it); npm run setup needs a user agent preset or DSH's shipped standard |
| Node.js (engine, setup) | 22.23 on Windows 11; 22.x on Linux (test container) | ^22.19.0 or >=24 | the engines field in package.json |
Python (proxy, bridge, cg_doctor.py) | 3.11 | 3.10 or later | the DSH engine itself needs no Python |
| Operating system | Windows 11 (daily use); Ubuntu, Windows and macOS (CI: pytest + node smoke tests on every push) | — | macOS runs the test suites in CI only; no daily use on a Mac yet |
| Backend (proxy) | Ollama /v1 | any OpenAI-compatible /v1/chat/completions: LiteLLM, vLLM, LM Studio, the llama.cpp server | the proxy estimates tokens itself, so it does not need the backend's usage numbers |
| Backend (DSH engine) | Ollama models driven by DSH | any model DSH drives | the window is the one DSH reports for the model; set numCtx only to force a smaller one |
| Client (proxy) | OpenClaude | Claude Code and other OpenAI-compatible CLIs | Cursor is untested |
| Companion | dsh-tool-guardian 0.3.0-alpha.x, side by side in the same DSH profile | 0.3.0 and later | the two share no files and install separately |
"Tested on" means the repo's test suites plus daily use on the machine this was built on. "Expected to work" is not tested; please open an issue if it does not work for you.
Measured: does it keep what matters? (2026-10-01)
A 48-prompt session on qwen3-coder:30b (Ollama, 64K window) under the DeepSeek Harness: 12 project codenames are given in the first 6 prompts, 40 filler reading tasks force 3-7 compactions, then the model is asked for all 12 (null allowed, guessing counted as wrong). Fresh random codenames every run.
| how the facts were given | guardian off | 0.1.0-alpha.7 | 0.1.0-alpha.8 |
|---|---|---|---|
| "Important, keep this for later: ..." | 2 of 3 runs 12/12 (one run invented all 12) | 0 of 3 runs right (one invented all 12, two never finished) | 3 of 3 runs 12/12, 0 invented |
| "Please remember these for later: ..." | -- | -- | 12/12, 0 invented |
| "For reference: ..." (no request to keep) | 0/12 in 2 of 2 runs (one answered null, one invented all 12) | -- | 12/12 in 2 of 2 runs, 0 invented |
What changed: facts the user asks to keep are pinned verbatim; the summary call is also asked for a ## Must Keep
section whose bullets are pinned for the rest of the session; every checkpoint is checked for its pins; the idle trigger
is off by default.
0.1.0-alpha.9 (2026-10-04): early details come back too. Same session, but codenames change mid-session and the
last questions ask for details from the first documents that nobody flagged. Stale recall (on by default) adds one
[context-guardian recall] message with up to 3 matching original lines when your message names something only the
compacted turns still hold.
| variant | runs | facts current | stale answers | early facts |
|---|---|---|---|---|
| pins only (alpha.8) | 2 | 12/12, 9/12 | 0, 3 | 0/3, 0/3 |
| pins + stale recall (alpha.9) | 3 | 12/12 each | 0 each | 3/3 each |
Why this exists
Claude-Code-style coding CLIs (Claude Code itself, and OpenAI-compatible-backend tools like OpenClaude) ship with a built-in auto-compact feature. That feature depends on accurate, real-time token-usage accounting coming back from the API in the exact shape the CLI expects. Point one of these tools at a local model through an OpenAI-compatible bridge — Ollama's /v1 endpoint, a LiteLLM proxy, a Headroom proxy — and that accounting is frequently missing, wrong, or shaped differently, so auto-compact silently never fires.
The visible symptom: the session just runs until the backend hard-rejects the request ("token limit reached"), you're forced to close and reopen, and there's no partial-compaction attempt in between — you just lose your place.
Context Guardian is a small, deliberately simple fallback for that specific gap. It estimates the running token count itself, and once a conversation crosses a configurable threshold, it asks the same backend to condense the older portion of the conversation into one summary message before forwarding the request onward. Recent messages are always kept verbatim. If the summarization call itself fails, Guardian fails open — it forwards the original, uncompacted request rather than risk silently dropping history.
Where it sits in your stack
This is a new link in an existing chain, not a replacement for anything you already have:
Your CLI / agent (Claude Code, OpenClaude, etc.)
    -> Context Guardian        (this project)
    -> your existing OpenAI-compatible backend
       (Ollama directly, a LiteLLM proxy, Headroom, vLLM, ...)
Point your CLI's OPENAI_BASE_URL at Context Guardian instead of directly at your backend, and set GUARDIAN_UPSTREAM_URL to wherever your backend actually lives. Guardian is a pure passthrough for everything except POST /v1/chat/completions, which gets the compaction check — every other route, including streaming responses, is forwarded byte-for-byte, untouched.
If you use MCP servers or an agentic CLI, read this
Guardian counts your tools array against the context budget. It did not
before 0.2.0, and that was a real bug — see the changelog.
Tool definitions are usually invisible in a way message history is not. You do not type them, they do not scroll past, and your CLI's context display often does not break them out. But they are in every single request. On the setup this was developed against, seven MCP servers came to 28,689 tokens — 87.6% of a 32,768-token window — before the first user message.
Guardian cannot compact them. It summarizes conversation history; tool definitions are a fixed floor underneath it. So there are two different problems and only one of them is Guardian's:
| Problem | What fixes it |
|---|---|
| Conversation history grows until the window fills | Guardian |
| Two thirds of the window is gone before you type | Loading fewer tools, or Tool Guardian |
Guardian will now tell you which one you have. It logs a tool_budget event the
first time it sees a given tool payload, and warns outright when the tool
definitions alone meet or exceed the whole window:
[ContextGuardian] TOOL DEFINITIONS ALONE (2671) EXCEED THE ENTIRE CONTEXT
WINDOW (1000). Nothing this proxy does can fix that -- send fewer tools.
If you see that, no proxy setting will help you. Most MCP-capable CLIs let you
scope which servers load per session — Claude Code and OpenClaude both accept
--mcp-config <file> together with --strict-mcp-config, which makes that file
the only source of MCP servers for the session.
Companion project — Tool Guardian
(dsh-tool-guardian on npm, or tool-guardian as a plain MCP server; see its README) does the other half of this. It fronts your MCP servers behind three
generic tools and reveals the rest on demand, so the tool definitions stop being re-sent on every
request in the first place. Context Guardian can't compact that fixed tool floor — Tool Guardian
removes it. Use them together: one trims the conversation, the other trims the tools.
One consequence worth expecting: after upgrading, Guardian compacts sooner and more often. It is measuring the whole request now instead of a fraction of it. If that feels aggressive, the honest reading is that your window was already this full and you could not see it.
What this does not do
- It doesn't replace or duplicate compression your backend already does (e.g. Headroom, prompt caching). It forwards to your backend as-is once it's decided whether to compact first — the two are complementary, not competing.
- It doesn't fix your CLI's own context-usage display. Your CLI doesn't know this proxy exists, so its own token counter will drift from reality after a compaction happens. What matters is that the session keeps working instead of hard-stopping — a slightly-wrong displayed number afterward is an accepted tradeoff of doing this invisibly at the proxy layer, since the CLI itself usually isn't something you can modify.
- It is not a tokenizer-accurate counter. Token count is estimated from character length (~3.5 chars/token by default), not a real tokenizer, so it triggers a little early rather than late. Treat it as a safety-margin trigger, not a precise measurement.
Install
git clone https://github.com/LuminariSoftwares/context-guardian.git
cd context-guardian
python -m venv .venv
source .venv/bin/activate   # Windows: .venv\Scripts\activate
pip install -r requirements.txt
Then run python configure.py (see Configure below) before starting Guardian for the first time.
Configure
Run the interactive setup script instead of hand-editing a config file — it asks you a handful of questions about your specific hardware/backend (most importantly, your model's real context window) and writes the answers to .env for you:
python configure.py
Every question has a sensible default shown in [brackets] — press Enter to accept it. You can re-run configure.py any time to change your answers, or just edit .env directly afterward.
The one setting that actually matters per-person is GUARDIAN_NUM_CTX. This project was originally built and tested on a 16GB card (RTX 4070 Ti Super) running a model configured for a 32K context window — that number is specific to that hardware, not a universal default. Your correct value depends entirely on your own GPU/VRAM budget and which model you're running, so configure.py asks for it explicitly rather than silently assuming everyone's setup looks the same. If you're not sure what your real number is:
- Ollama: run
ollama pswhile your model is loaded — theCONTEXTcolumn shows the live value actually in use (not necessarily the model's theoretical max). - LM Studio / vLLM / other servers: check whatever context-length setting you configured when loading the model — Guardian has no way to auto-discover this, so it needs to match what you actually set.
- If you're unsure or haven't set one explicitly: start conservative (the
configure.pydefault of 32768 is a reasonable, widely-safe starting point on a single consumer GPU) and raise it later once you've confirmed your backend can actually sustain it without running out of VRAM.
Setting this too high means Guardian won't compact soon enough and your backend can still hard-error before Guardian steps in. Setting it too low just means Guardian compacts a bit more often than strictly necessary — safe, just not optimal.
If you'd rather skip the wizard, copy .env.example to .env and edit it by hand:
cp .env.example .env
| Variable | Default | What it does |
|---|---|---|
GUARDIAN_PORT | 8786 | Port Guardian itself listens on |
GUARDIAN_UPSTREAM_URL | http://localhost:11434/v1 | The OpenAI-compatible backend Guardian forwards to |
GUARDIAN_NUM_CTX | 32768 | Your model's real context window, in tokens — keep this in sync with your actual backend/model config. On Ollama the proxy can read it per model instead: see GUARDIAN_OLLAMA_CONTEXT |
GUARDIAN_OLLAMA_CONTEXT | auto | When the upstream is Ollama (auto: the upstream URL is on port 11434; 1 always, 0 never), ask /api/show once per model and budget against the num_ctx it reports. A model that reports only its trained context_length can lower GUARDIAN_NUM_CTX but never raise it, since Ollama may run it at less. Any error falls back to GUARDIAN_NUM_CTX for that model for the rest of the run |
GUARDIAN_COMPACT_THRESHOLD | 0.85 | Fraction of GUARDIAN_NUM_CTX at which compaction triggers |
GUARDIAN_KEEP_RECENT_MESSAGES | unset | Unset (the default): keep the newest messages that fit in GUARDIAN_KEEP_RECENT_FRACTION of the usable window (GUARDIAN_NUM_CTX − GUARDIAN_RESERVE_OUTPUT), never fewer than 4 — a 40 KB tool result counts as what it is, not as one message. Set a number to keep exactly that many messages instead (the old fixed-count behaviour; 0 keeps none) |
GUARDIAN_KEEP_RECENT_FRACTION | 0.20 | Share of the usable window kept verbatim when GUARDIAN_KEEP_RECENT_MESSAGES is unset |
GUARDIAN_CHARS_PER_TOKEN | 3.5 | Characters-per-token used for the estimate |
GUARDIAN_COUNT_TOOLS | 1 | Count the tools array against the budget. Set 0 for pre-0.2.0 messages-only behaviour |
GUARDIAN_CALIBRATE | 1 | Learn each model's real tokens-per-character from the usage figures the backend returns, and correct the estimate with it. Read per request; set 0 to use the raw estimate |
GUARDIAN_UPSTREAM_TIMEOUT | 600 | Seconds to wait for the upstream backend to respond |
GUARDIAN_UPSTREAM_CONNECT_TIMEOUT | 10 | Seconds to wait for the upstream connection itself |
GUARDIAN_LOG_PATH | <repo>/logs/context_guardian_log.json | Where compaction events are logged (JSON lines) |
GUARDIAN_HOST | 127.0.0.1 | Interface Guardian binds. Leave this alone unless you know what you are doing — Guardian fronts your backend with no authentication |
GUARDIAN_RESERVE_OUTPUT | 8192 | Tokens held back for the model's output. The window has to hold the reply and (for reasoning models) the thinking too, so compaction triggers against what is LEFT. If this is ever ≥ GUARDIAN_NUM_CTX it is clamped to half the window and logged — fix the config |
GUARDIAN_SPAN_DIR | <repo>/logs/guardian_spans | Where evicted messages are archived before folding. This is what makes compaction lossless on disk |
GUARDIAN_KEEP_SPANS | 500 | How many span files to keep. 0 keeps none |
GUARDIAN_KEEP_SUMMARIES | 1 | How many of Guardian's own previous summaries stay in the window. Retired ones are folded into the next span, not discarded |
GUARDIAN_MIN_SUMMARY_CHARS | 40 | A summary shorter than this is treated as a FAILED summarisation and nothing is evicted. See 0.4.0 in the changelog for why this exists |
GUARDIAN_MIN_TRANSCRIPT_CHARS | 80 | If the messages being evicted render to less than this, Guardian refuses to summarise rather than summarising nothing |
GUARDIAN_TOOL_ARG_CHARS | 300 | How much of a tool call's arguments reaches the summariser. The full text is in the span |
GUARDIAN_SUMMARY_REASONING_EFFORT | unset | Passed as reasoning_effort on the summarisation call only. Non-standard, so off by default; low roughly halved summarisation latency on gpt-oss |
GUARDIAN_VERBOSE | 1 | Print a visible multi-line banner on every compaction (what it cut, tokens before/after, tokens saved). Set 0 for the old single-line log entry |
GUARDIAN_COST_PER_1M_INPUT_USD | 0 | Price of 1M input tokens on the hosted API you're avoiding by running locally. When set, Guardian reports the running dollar value of the tokens compaction has kept you from re-sending. 0 (default) omits the cost line — you're on a local model, there's no real bill |
GUARDIAN_VERSION_CHECK | 1 | On startup, ask PyPI once (2s timeout, cached 24h, fully fail-open) whether a newer context-guardian exists and print one line if so. Set 0 to disable — airgapped/privacy setups never touch the network |
GUARDIAN_VERSION_CACHE | <repo>/logs/.version_check_cache.json | Where the update check caches PyPI's answer so frequent restarts don't re-hit the network (24h TTL) |
GUARDIAN_DRY_RUN | 0 | 1: compute every compaction (the summariser is still called) and log it as a dry_run event with the same fields as a real one, but forward the client's request byte-for-byte. Counted on the health dashboard. For watching what the proxy would do before letting it |
GUARDIAN_INJECT_STREAM_OPTIONS | 0 | 1: add stream_options: {"include_usage": true} to streaming chat requests that do not already carry stream_options, so the usage frame reaches the calibrator. Off by default because the client then receives one extra final frame with empty choices, which some clients do not expect |
A note on timeouts: local "thinking"/reasoning models can go silent for a long time before their first output token. If you see 500 errors appear only on real (non-trivial) requests after a long pause, raise GUARDIAN_UPSTREAM_TIMEOUT before assuming something is broken — the default 5-second timeout most HTTP clients ship with is sized for ordinary REST APIs, not local LLM inference, which is exactly the bug this project's own commit history caught during development.
Run
python context_guardian.py
Then point your CLI's OPENAI_BASE_URL at http://localhost:8786/v1 (or whatever port you configured).
Check your setup: cg_doctor.py
One command says what is configured, what is wrong, and how to fix each problem:
python cg_doctor.py                          # from the repo, or the installed npm package folder
context-guardian-doctor                      # after `pip install context-guardian` (0.7.0+)
python cg_doctor.py --preset path/to/agent.cordis.yml   # also check the DSH preset that mounts engine.js
python cg_doctor.py --json                   # the same findings as JSON
It prints one OK / WARN / FAIL line per check, a fix: line under every problem, and a count line
(doctor: 5 ok, 1 warnings, 0 errors); it exits 1 if anything FAILed. It checks:
- the package version (
package.json) and the proxy's own version (context_guardian.py); - your
.env— found or not, and every numericGUARDIAN_*value actually parses (a32kor aGUARDIAN_RESERVE_OUTPUTthat is not belowGUARDIAN_NUM_CTXis a FAIL with the fix); - the context window in use —
GUARDIAN_NUM_CTXif you set it, else anumCtxpinned in the preset you pass with--preset(a WARN: since 0.1.0-alpha.5 the engine reads your model's real window from DSH, so a copiednumCtx: 32768usually just shrinks it), else the window DSH reports for the session; - whether the proxy answers on
GUARDIAN_HOST:GUARDIAN_PORT(a WARN, not a FAIL — the DSH bundle works without it), and whether a running proxy was started with a different window than you now have set; - whether the Python bridge works — it starts
modules/cg_bridge.pywith the same interpreter the plugin would pick (GUARDIAN_PYTHON, then a.venvbeside the package, thenpython/python3on PATH) and requires Python 3.10+.
Standard library only; it never changes a file.
Testing before you trust it with a real session
- Start your real backend (Ollama, LiteLLM, Headroom, whatever you use) the way you normally would.
- Start Guardian:
python context_guardian.py - Send one manual request at it instead of your real CLI, to confirm plain passthrough works before testing compaction specifically:
bash
curl http://localhost:8786/v1/chat/completions \ -H "Content-Type: application/json" \ -d '{"model":"<your-model>","messages":[{"role":"user","content":"say hi"}]}' - Check
GET http://localhost:8786/guardian/statsfor the running token estimate and compaction count — or openhttp://localhost:8786/guardian/healthin a browser for the live dashboard (window usage, compactions, tokens/cost saved, and any update notice), which just renders that same JSON on a 3-second refresh. - Force a compaction test: temporarily set
GUARDIAN_NUM_CTXandGUARDIAN_COMPACT_THRESHOLDlow (e.g.NUM_CTX=2000,THRESHOLD=0.5), then send a conversation with several long messages. Confirm a compaction log entry appears atGUARDIAN_LOG_PATHand the request that actually reaches your backend is smaller than what was sent in. - Only after that, point your CLI's
OPENAI_BASE_URLat Guardian and test with a real session.
Running multiple models with different context windows
On Ollama, Guardian asks /api/show for each model's num_ctx (see GUARDIAN_OLLAMA_CONTEXT), so a model whose Modelfile sets num_ctx is budgeted against its own window. Otherwise GUARDIAN_NUM_CTX is fixed for the lifetime of one running instance. If you switch between models with meaningfully different context windows, either:
- run a second Guardian instance on a different
GUARDIAN_PORTwith its ownGUARDIAN_NUM_CTX, or - keep one instance and accept that its threshold is tuned to whichever model has the smaller/more-constrained window (safer than the alternative, since it just means Guardian compacts a bit earlier than strictly necessary for the larger-window model).
MCP server
context-guardian-mcp (installed with the PyPI package) is a stdio MCP server, so an MCP client can see what the proxy is doing without a terminal. It has three tools, and all three only read:
| Tool | What it does |
|---|---|
guardian_status | The running proxy's /guardian/stats over loopback (GUARDIAN_HOST:GUARDIAN_PORT) |
search_spans | Find text in the spans compaction archived (same search as context-guardian-recall) |
read_span | One archived span by run id and index: its summary and original messages, cut at 20,000 characters |
Claude Desktop (claude_desktop_config.json) or any client that takes the same shape:
{ "mcpServers": { "context-guardian": { "command": "context-guardian-mcp" } } }
Claude Code: claude mcp add context-guardian -- context-guardian-mcp
Benchmark
scripts/bench_proxy.py drives a scripted agent conversation (user turns, tool calls with large results, assistant replies; the client resends its whole history every turn) through the real proxy app against an in-process stub upstream, and prints one line. Same --turns and --seed give the same token figures; latency depends on the machine. Nothing touches the network or the repository.
python scripts/bench_proxy.py --turns 40 --seed 1
Measured against a stub upstream (not a real model; the stub summarises instantly, so added_ms is the proxy's own overhead, not summarisation time), 2026-10-14, Python 3.11, Linux container:
turns=40 tokens_before=1130722 tokens_after=160310 compactions=27 p50_added_ms=5.07 p95_added_ms=7.20
Development / running tests
pip install -r requirements-dev.txt
pytest
npm install --no-package-lock --legacy-peer-deps
npm run check && npm run test:node
CI runs both suites on Ubuntu, Windows and macOS (tests, node).
See it work
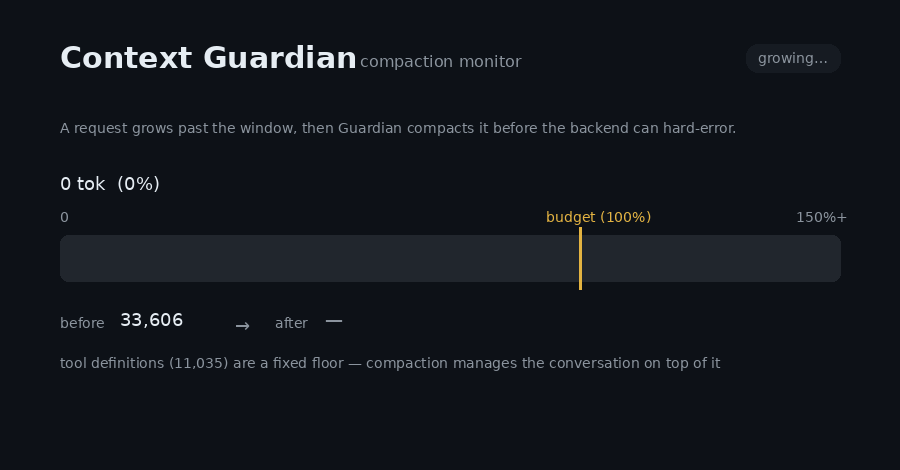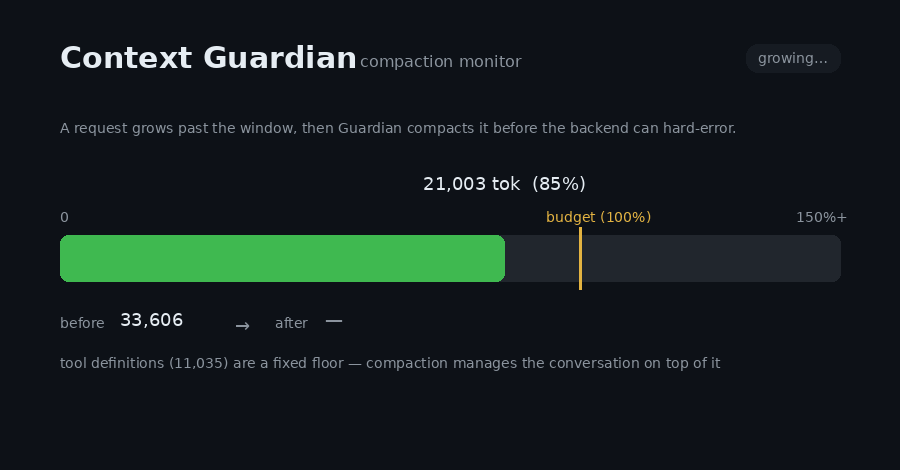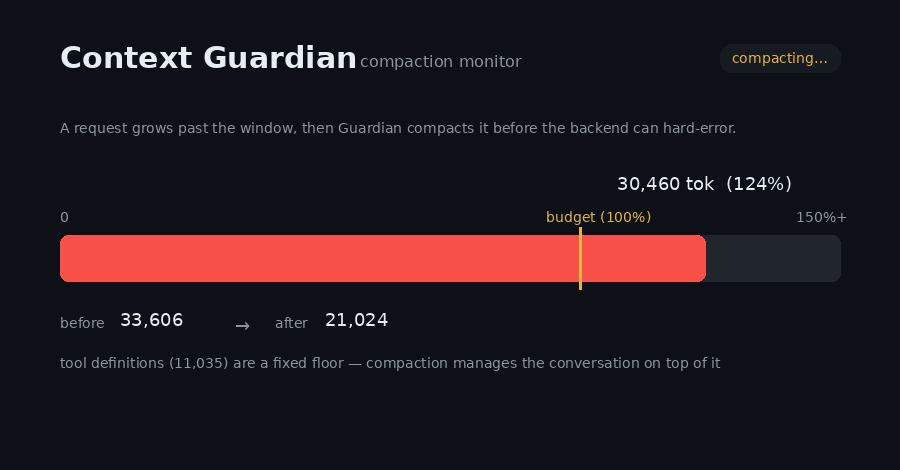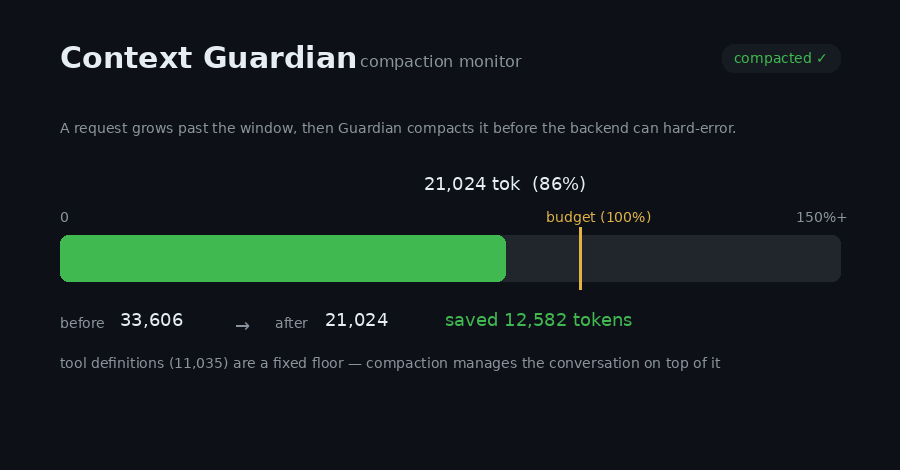
The proxy's /guardian/health compaction monitor: a request that arrives above the compaction threshold (GUARDIAN_COMPACT_THRESHOLD, 85 % of the window) is compacted before it is forwarded, so the backend never sees an over-long request.
- Proxy: open
http://localhost:8786/guardian/healthwhile a session runs. The compaction monitor replays every compaction as a before → after bar, with a per-compaction dropdown and an advice box when your fixed floor (tools + system prompt) is the real problem.GET /guardian/eventsreturns the same records as JSON. - DSH: type
/contextin a session for pressure, cache hits and what compacting now would save;/recall 3-7,/recall result 42or/recall find <text>to read originals;logs/guardian_dsh.jsonlfor the decision trail (idle-check→compaction/start→deterministicorllm→compaction/end).
Acknowledgements
Context Guardian stands on other people's ideas, and says so:
- dsh-compaction-instant (TsFreddie, MIT) —
vendor/compiler.jsandvendor/region.jsare vendored unmodified from 0.1.4, with their original headers and the MIT licence text invendor/LICENSE.dsh-compaction-instant. Therecall/searchcontract follows theirs. - VCC (lllyasviel) — the conversation-compiler principle that compiler ports: compile the log into a compact view made only of original tokens, with a pointer back to every elided part.
- dsh-openwolf (MIT) — the idea of snapshotting session state right before a compaction. The engine's
precompact-<seq>.jsonand theFILES WRITTENlist are an independent implementation of that idea; no openwolf code is included. - DeepSeek Harness —
summarize()is the hook its compaction engine documents for exactly this.
Full third-party notices: THIRD_PARTY_NOTICES.md.
License
MIT — see LICENSE.