Runs on your machine from its package; the steps are below.
What it does
- Reads
- Writes
- High impact
At most: creates or changes data: records, files, settings.
What it costs
FreeOdel charges nothing per call. The publisher may charge for its own service.
Runs locally over stdio
This server isn't hosted — your MCP client launches it from a package registry. Use one of the commands below, or drop the config into your client (e.g. Claude Desktop).
Run
uvx cogvault
MCP client config
{
  "mcpServers": {
    "cogvault": {
      "command": "uvx",
      "args": [
        "cogvault"
      ]
    }
  }
}




Get started in 30 seconds
Claude Code plugin — MCP server plus a skill that tells the agent when to recall and when to record:
/plugin install cogvault --marketplace NBibikov/cogvault
Claude Code before 2.1.275: /plugin marketplace add NBibikov/cogvault, then
/plugin install cogvault@cogvault.
Memory lives in ~/.cogvault/memory (set COGVAULT_TENANT to change it). The plugin
adds /cogvault:remember.
Any MCP client, one line (needs uv):
claude mcp add cogvault -- uvx cogvault mcp --tenant ~/agent/memory
Claude Desktop, Cursor, Windsurf, Cline — JSON config
Add to claude_desktop_config.json, ~/.cursor/mcp.json, or your client's MCP config:
{
  "mcpServers": {
    "cogvault": {
      "command": "uvx",
      "args": ["cogvault", "mcp", "--tenant", "~/agent/memory"]
    }
  }
}
Already have Markdown memory? Point the tenant at it — nothing to import. Claude
Code's auto-memory works as-is (frontmatter type, [[links]] and all):
M=~/.claude/projects/<project>/memory
uvx cogvault index  --tenant $M --ignore MEMORY.md   # first pass embeds, later passes are incremental
uvx cogvault search --tenant $M "how do we deploy"
The MCP server indexes on start by itself; the CLI search reads the existing index.
--ignore MEMORY.md keeps the index file from competing with the cards it points to.
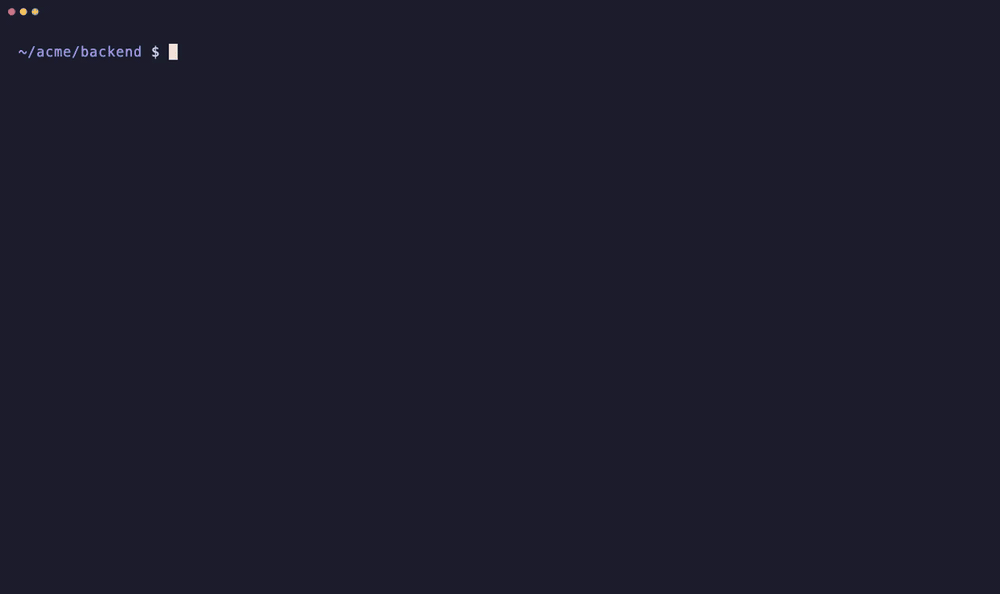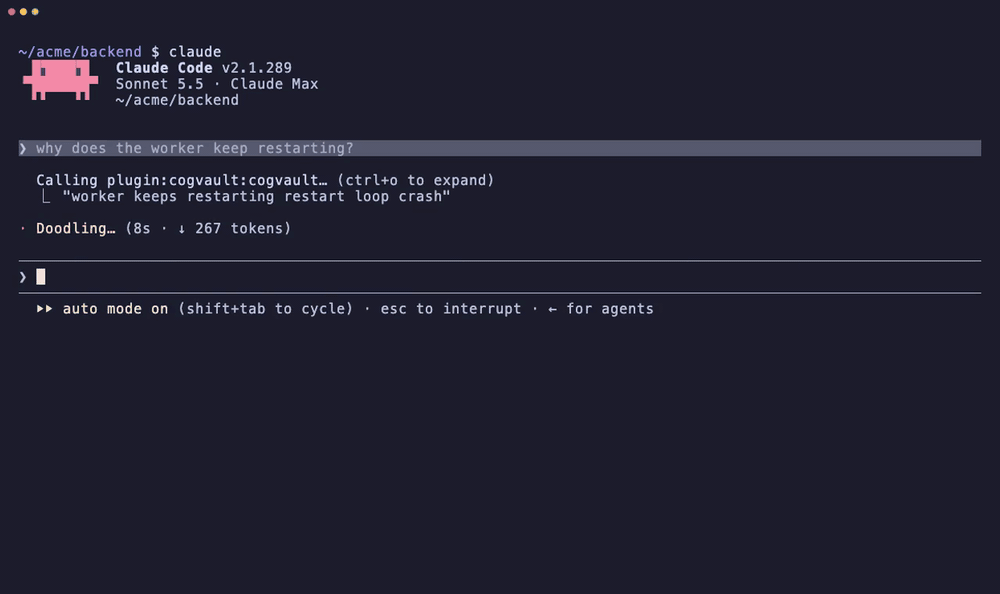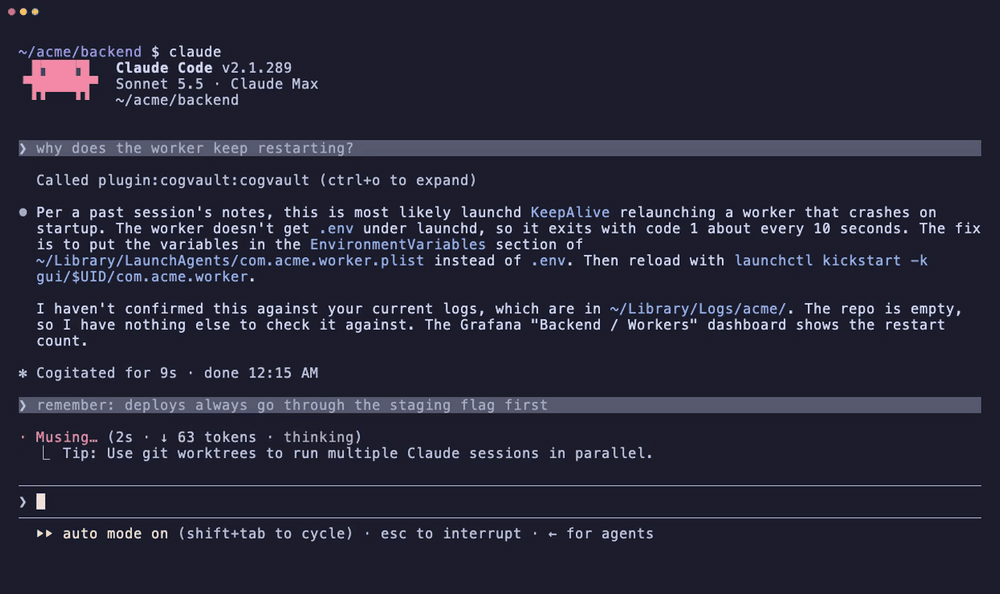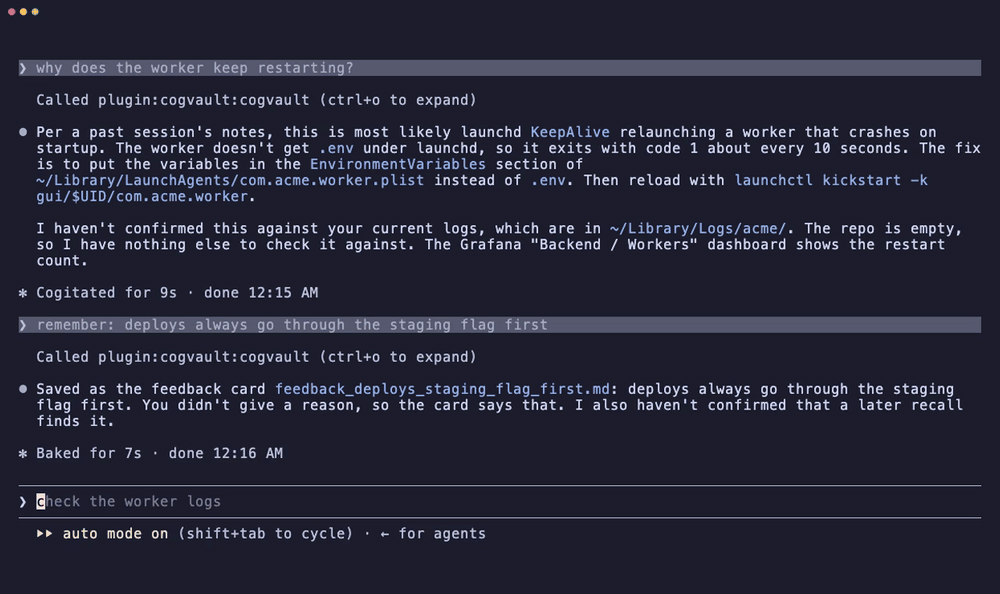
Unedited answers from a real session (Sonnet, plugin installed, a demo memory of six cards); only the waiting time is cut.
Why
Most "AI agent memory" tools want to be an autonomous LLM daemon that summarizes your work into an opaque database or a graph you can't read. For a fleet of coding agents that just need to reliably recall a decision, a bug fix, or an infra detail, that's the wrong trade.
cogvault makes the opposite bet:
- Your Markdown files are the source of truth. Open them, edit them,
git diffthem. The SQLite index is a derived cache — delete it and it rebuilds from the files. - One library, many tenants. Each agent gets an isolated memory namespace via its own directory. A process loads each embedding model once and shares it across every tenant it touches; with the stdio MCP server that means one small process per agent session, not a central daemon.
- No LLM in the loop. Ingest and retrieval are deterministic. Your agent is the LLM — it doesn't need a second one to remember.
- Local, private, offline. FastEmbed runs on-device. Nothing leaves your machine.
Compared to
Checked against each project's README and docs on 2026-10-05.
| cogvault | basic-memory | mem0 | Graphiti | Letta Code | |
|---|---|---|---|---|---|
| Source of truth | Markdown files | Markdown files | Vector DB (Qdrant / pgvector) | Graph DB (Neo4j, FalkorDB, …) | Markdown in a git repo per agent |
| LLM needed to store or recall | No | No (optional reranker) | Yes by default (add() extracts facts) | Yes to ingest | Yes — the agent edits its memory |
| Retrieval | Vector + BM25, RRF, decay, MMR | Full-text + vector, optional rerank | Semantic + BM25 + entities | Semantic + BM25 + graph | File search; hybrid optional |
| Infra | One process, SQLite file | One process, SQLite (Postgres optional) | Library, or Docker + Postgres server | A graph database | Letta backend |
Pick something else when: you want an LLM to distil and merge facts for you (mem0), relationships between entities are the point (Graphiti), you want the agent to manage its own memory (Letta), or you want a richer notes app around the same Markdown idea, with Obsidian sync and a hosted option (basic-memory — the closest to cogvault).
Pick cogvault when: you run several agents and want each one's memory isolated in its
own directory behind one process; you want recall to be deterministic and offline; and you
want to measure it — cogvault eval scores recall on your agents' real queries and
cogvault analyze lists what they tried to recall and couldn't.
How it works

Anatomy of a recall

Hybrid retrieval fuses semantic (vector) and keyword (BM25/FTS5) ranking with Reciprocal Rank Fusion, then applies optional temporal decay (recent memory outranks stale) and MMR (diverse top results, not five near-duplicates). Each card contributes only its best chunk, so one long file can't fill the whole result list.
Benchmark

Measured on real recall traffic, not synthetic questions: 66 queries sampled from the
query logs of 6 live agent tenants (58% Ukrainian, the rest English), each judged against
the actual cards — including answers that no configuration returned. One query has no
answer in memory and counts as a gap, so 65 are scored. Every configuration was re-indexed
from scratch on copies of the same tenants with cogvault 0.11.0.
| Configuration | hit@1 | hit@5 | MRR@10 |
|---|---|---|---|
multilingual-e5-small, chunk_chars = 700, summary chunk | 0.57 | 0.91 | 0.70 |
multilingual-e5-small, chunk_chars = 700, no summary chunk | 0.55 | 0.86 | 0.69 |
paraphrase-multilingual-MiniLM-L12-v2 (built-in default) | 0.54 | 0.80 | 0.66 |
bge-small-en-v1.5 (English-only) | 0.57 | 0.77 | 0.65 |
What the numbers do and don't say:
- hit@1 is a tie. All four land within 0.54–0.57, and the 95% bootstrap intervals overlap almost completely. Real agent queries read like card titles, so the right card usually wins on its name alone.
- The gap is in the top 5. e5-small with the summary chunk puts the answer in the top 5 for 91% of queries vs. 80% for the default MiniLM and 77% for English-only bge on this mixed-language memory. That's what an agent reading 5 results actually feels.
- 65 queries is still a small sample. Treat differences under ~0.1 as noise. The
aggregate numbers are in
assets/benchmark.json; the queries are private and stay in each tenant.
Run the same check on your own memory: put judged queries in
<tenant>/.cogvault-golden.jsonl ({"query": "...", "relevant": ["file.md"]}, empty
relevant = a known gap) and run cogvault eval --tenant DIR.
Choosing an embedding model
Agent memory is often not English-only. The default is multilingual so nothing
is broken out of the box — but pick the model that matches your fleet's language mix
(set COGVAULT_MODEL, or Config(model=...)). Switching models auto-rebuilds the index.
Model (COGVAULT_MODEL) | Dim | Size | Real-query hit@5* | Cyrillic / multilingual | When |
|---|---|---|---|---|---|
paraphrase-multilingual-MiniLM-L12-v2 (default) | 384 | 0.22 GB | 0.80 | ✅ works | Mixed-language fleets; safe default |
BAAI/bge-small-en-v1.5 | 384 | 0.13 GB | 0.77 | ❌ Cyrillic vectors break | English-only memory |
intfloat/multilingual-e5-small | 384 | 0.47 GB | 0.91 | ✅ best per GB (512-token window) | Mixed-language fleets; use chunk_chars = 700 |
intfloat/multilingual-e5-large | 1024 | 2.24 GB | not measured | ✅ best | Max quality, RAM to spare |
*From the benchmark above: 65 real queries over mixed EN/UK memory,
cogvault 0.11.0. On English-only memory bge-small-en is a fine choice; on Ukrainian
content it returns a negative relevance margin (a distractor outranks the answer),
so it is unsafe for non-English memory. Run cogvault eval on your own vault to decide.
COGVAULT_MODEL=BAAI/bge-small-en-v1.5 cogvault index --tenant ~/agent/memory
Pin the model per tenant so it travels with the data instead of relying on every
command exporting COGVAULT_MODEL (forget it once and a model mismatch silently
re-embeds the whole index). Drop a .cogvault.toml at the tenant root:
# ~/agent/memory/.cogvault.toml
model = "BAAI/bge-small-en-v1.5"
# optional: recursive = true, strip_frontmatter = true, ignore_globs = ["Templates/*"]
Now cogvault search --tenant ~/agent/memory "…" uses the right model with no env var.
Precedence: explicit --model / $COGVAULT_MODEL > .cogvault.toml > built-in default.
Install
uv tool install cogvault        # CLI on PATH
# or
pip install cogvault
Or skip installing and run it on demand with uvx cogvault …. The first run downloads
the embedding model (~0.2–0.5 GB, once per machine).
Add it to Claude Code as an MCP server in one line:
claude mcp add cogvault -- uvx cogvault mcp --tenant ~/agent/memory
Also listed in the official MCP Registry
as io.github.NBibikov/cogvault. Wheels are attached to each
GitHub release.
Quickstart
# index a tenant's markdown memory
cogvault index --tenant ~/agent/memory

# search (hybrid semantic + keyword)
cogvault search --tenant ~/agent/memory "how do I restart the worker service"

# enable temporal decay (recent wins) and tune diversity
cogvault search --tenant ~/agent/memory "deployment steps" --half-life 30 --mmr 0.5

# only cards of one frontmatter type (user / feedback / project / reference / …)
cogvault search --tenant ~/agent/memory "hard rules for deploys" --type feedback
Memory cards
cogvault understands two lightweight Markdown conventions (both optional — plain files index fine):
- Frontmatter
type— either flat (type: reference) or nested (metadata:→type: reference). Parsed at index time and filterable at search time (--type, MCPtypeparam,search(card_type=...)). Every hit carries atypefield; cards without frontmatter getnull. [[wiki-links]]— link targets are indexed, and the top search result includes arelatedlist of linked cards that exist in the index (ghost links are dropped; matching is by exact filename stem).
As an MCP server (Claude Code, Cursor, any MCP client)
claude mcp add cogvault -- uvx cogvault mcp --tenant ~/agent/memory
Exposes two tools:
cogvault_recall— natural-language hybrid search over this agent's memory. Optionaltypeparam filters to one frontmatter card type; the top result includes aRelated:line built from its[[wiki-links]].cogvault_record— save a fact; it's written as a Markdown card and indexed
Indexing a folder tree (Obsidian vaults, knowledge bases)
By default a tenant is one flat directory of .md files. For a nested vault
(e.g. Obsidian, with 01-Projects/…, frontmatter, and folders to skip), opt in:
cogvault index --tenant ~/vault \
  --recursive \
  --strip-frontmatter \
  --ignore ".obsidian/*" --ignore ".trash/*" --ignore "Templates/*"
--recursivewalks subdirectories; files keep their path relative to the tenant, so two notes namedTasks.mdin different folders never collide.--strip-frontmatterdrops a leading YAML--- … ---block so its keys don't pollute the embedding.--ignore GLOB(repeatable) skips paths relative to the tenant root.
Same flags exist on search and mcp, and as Config(recursive=True, strip_frontmatter=True, ignore_globs=(...)) for the library. Indexing is
incremental: the first pass embeds everything, later passes only re-embed changed
files. (Reference: a ~3,500-note vault → ~9,500 chunks, first index ≈ 3–4 min,
then warm recall in single-digit milliseconds.)
As a library
from cogvault import Vault, Config

vault = Vault("~/agent/memory", Config(half_life_days=30))
vault.reindex()
for hit in vault.search("where are credentials stored"):
    print(hit["score"], hit["file"], hit["snippet"])
Keeping a tenant healthy
cogvault doctor --tenant DIR reports what silently degrades recall: cards with
no frontmatter or type, legacy timestamp filenames, frontmatter wrapped inside
frontmatter, duplicate name: slugs, and [[links]] that resolve to nothing.
Links resolve by frontmatter name:, filename stem, either separator style, and
with or without the card-type prefix; links inside code and paths to files outside
the tenant are not counted.
cogvault repair --tenant DIR fixes the mechanical half (dry run by default,
--apply to write): unwraps nested frontmatter, infers a missing type, renames
card-<timestamp>-….md to <type>_<slug>.md and rewrites every reference to it
(MEMORY.md included), and adds minimal frontmatter to <type>_*.md cards that
lack it. Healthy cards are left alone, and repaired cards keep their mtime so
temporal decay is not reset.
Effectiveness logging
Every recall is logged (one JSONL line) so you can measure whether the memory is
actually helping. cogvault analyze turns the log into a report:
cogvault analyze            # recalls, latency, per-tenant hit distance, weakest hits, card writes
cogvault analyze --json     # machine-readable
cogvault analyze --since 7  # only the last 7 days (or --since 2026-10-05)
The section that matters is weakest hits: each tenant's worst decile by vector
distance — queries where recall returned something (hybrid search almost always does)
but probably not the answer. That list is what your agents tried to recall and couldn't,
i.e. the memory gaps to fill. Set COGVAULT_LOG=off to disable, or
COGVAULT_LOG=/path.jsonl to relocate.
Multi-tenant fleets
Point one process at many tenants — each directory is an isolated namespace, proven by
the test suite (test_multi_tenant_isolation). Agent B can never recall Agent A's
memory unless you point B at A's directory.

Design notes
| Decision | Why |
|---|---|
| Markdown = source of truth | Human-readable, git-versionable, editable, never locked in a DB |
SQLite + sqlite-vec + FTS5 | Zero-infra hybrid search; one portable .db file; rebuildable |
| FastEmbed (multilingual MiniLM default, 384-d) | In-process ONNX, no server, no API key, ~220 MB |
| Content-hash cache | Re-indexing only embeds changed chunks |
| RRF + decay + MMR | Precision, recency, and diversity without a graph DB |
| One process, many tenants | Fleet infra, not a single-user desktop sidecar |
| WAL + incremental reindex | Concurrent agents read while one writes; only changed files re-embed |
Roadmap
- Importers (migrate existing memory from other stores)
- Pluggable embedders (Ollama, OpenAI-compatible endpoint)
-
valid_untilper-card temporal validity - Optional FastMCP transport
License
MIT — your memory, your files, your infrastructure. Forever.
Figures are hand-built SVG from assets/make_graphics.py — python assets/make_graphics.py --png regenerates them.