Sparkforensics
MCP server for diagnosing Apache Spark event-log performance issues and comparing runs.
Runs on your machine from its package; the steps are below.
What it does
- Reads
- Writes
- High impact
At most: only reads or looks up information.
What it costs
FreeOdel charges nothing per call. The publisher may charge for its own service.
Runs locally over stdio
This server isn't hosted — your MCP client launches it from a package registry. Use one of the commands below, or drop the config into your client (e.g. Claude Desktop).
Run
npx -y sparkforensics-mcp
MCP client config
{
  "mcpServers": {
    "sparkforensics": {
      "command": "npx",
      "args": [
        "-y",
        "sparkforensics-mcp"
      ]
    }
  }
}


Your Spark job is slow. SparkForensics tells you why, and what to do about it.
Drop a Spark event log in and get an evidence-backed breakdown of which stages are slow, why, and how to fix them. Nothing installs on your cluster and nothing leaves your machine.
Try it now → with your own event log. No install, no account, no upload. Read the documentation for a guided tour.
Spark's own History Server gives you raw metrics. It won't tell you that stage 14 spilled 40GB because of a skewed join key, or that cold start is eating a third of the job. SparkForensics reads the same event logs and turns them into findings.
Why SparkForensics
- Your data stays on your machine. Drop a log file and read the dashboard; nothing is uploaded anywhere. Local-server mode adds a small Node companion that can also pull runs from a Spark History Server.
- Event logs are streamed and parsed off the main thread in a Web Worker, so a 240MB+ (or multi-GB) NDJSON log doesn't freeze the tab.
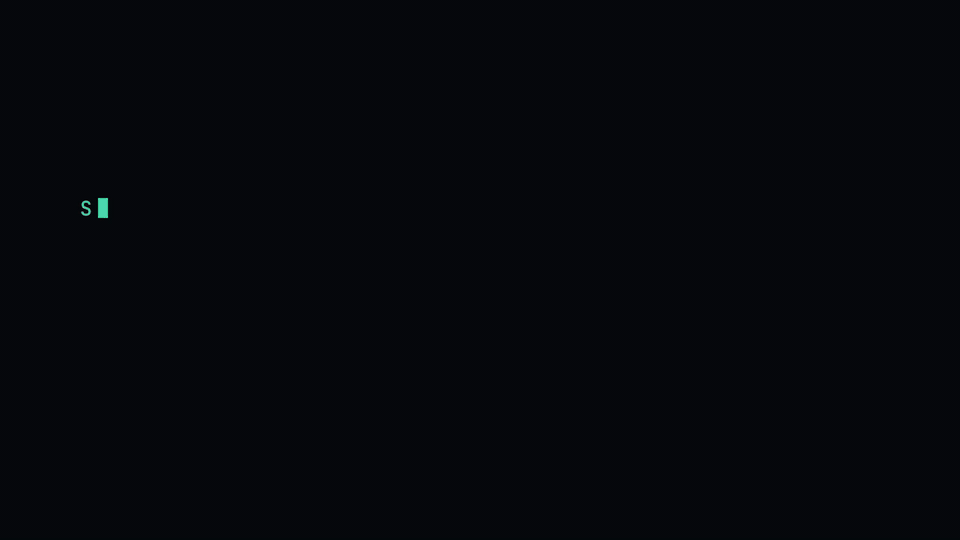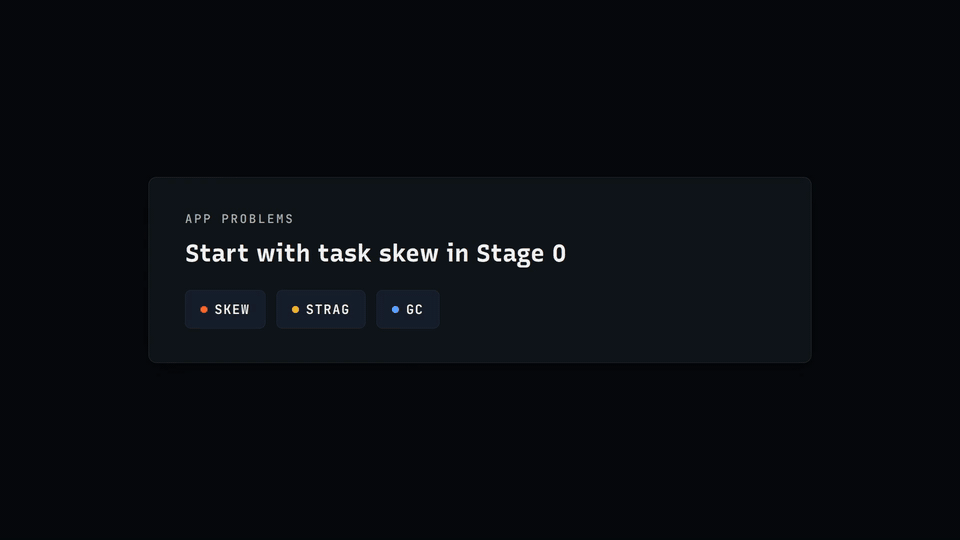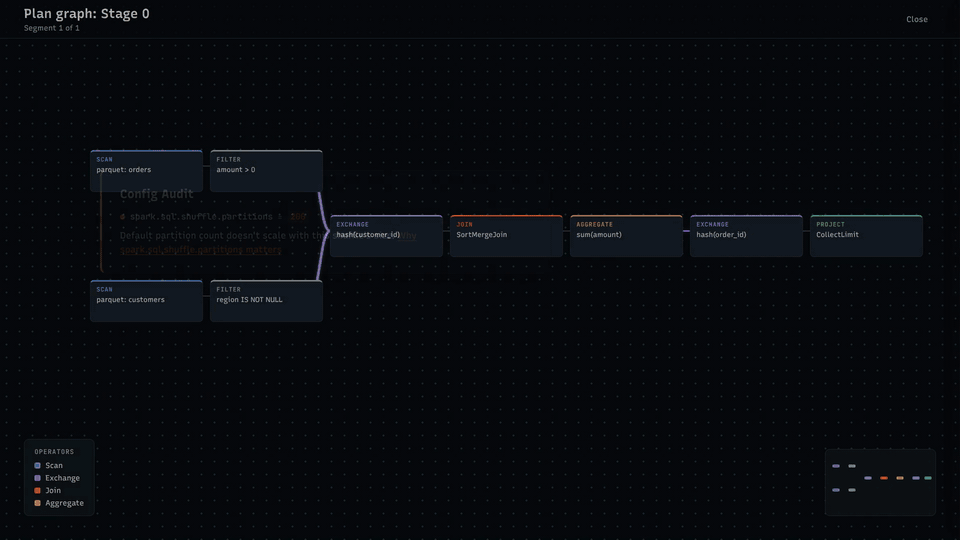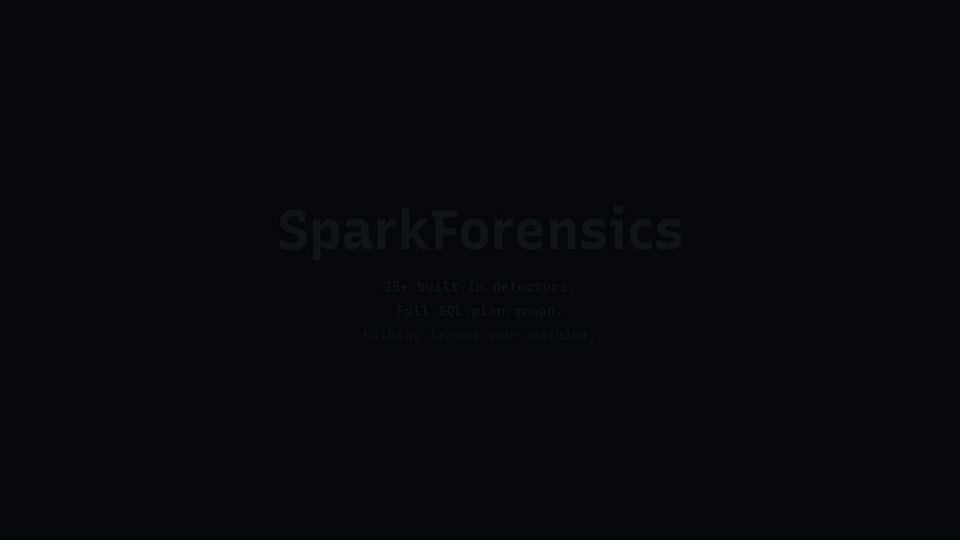
- About 25 built-in detectors cover skew, shuffle, spill, GC pressure, stragglers, cold start, cache/memory utilization, autoscaling churn, job/stage failures and partition sizing, plus a SQL Plan Advisor (duplicate subtrees, small files, broadcast sizing) and a config audit. Full roster in the detector contract.
- Fix These First orders every finding by its estimated wall-clock impact, not severity alone, so the top row is the fix worth doing first.
- Run comparison (A/B) mode structurally matches stages across two runs of the same job and shows which stages regressed, rather than every difference.
- Every finding tracks what it could and couldn't confirm from the log, so you know when to trust a flag and when it's a hint worth checking manually.
- A headless CLI (
sparkforensics-analyze) evaluates a run against budget thresholds (max runtime, skew, spill, failure rate...) and exits non-zero on violation, so a regression can fail a build. The run can come from a local event-log file/directory or, with--shs-base-url, fetched directly from a Spark History Server. - An MCP server (
sparkforensics-mcp) exposes tools for diagnosing, summarizing and comparing runs, so an LLM agent can investigate a run directly. The full tool list is in MCP tools. - For running the analyze CLI automatically after every Spark job instead of by hand, see sparkforensics-operator, an Airflow operator that runs SparkForensics on a job's event log and acts on the result.
Unlike tools that need a cluster-side plugin or a running server plus an LLM agent (Spark History Server MCP tools), SparkForensics needs nothing installed anywhere else: the event log and a browser tab are enough.
Get started
Run the dashboard locally:
npx sparkforensics-server
The Getting started guide covers what it serves, the live demo alternative, and loading a run. To work on SparkForensics itself, see Development.
For a one-shot check with no browser, the kind a CI pipeline can gate on:
npx -p sparkforensics-cli sparkforensics-analyze path/to/eventlog --max-runtime 3600000 --max-skew 3
The command ships in the sparkforensics-cli package. To install it once
instead: npm i -g sparkforensics-cli, then run sparkforensics-analyze
directly. The sparkforensics-analyze alias package also works:
npx sparkforensics-analyze.
That's a headless run against budget thresholds. See Command-line reference below for HTML export, Spark History Server fetching, baseline comparisons, and redaction.
Development
Install and run
From a checkout:
git clone git@github.com:shuffle-works/sparkforensics.git
cd sparkforensics
npm install
npm run dev
Open the URL Vite prints. For a production bundle: npm run build, then serve dist/ with
any static file server. Asset URLs are relative, so the bundle also works
under a URL subpath.
Note: The app must be served over HTTP:
file://URLs block Web Worker module imports in Chrome.
Deploy modes
This app runs in two modes:
- Static mode (e.g. GitHub Pages, or any plain file server): Choose file
is the normal browser-local path for a single event log. Choose
rolling-log folder is available only for an
eventlog_v2_*directory. Deploy the output ofnpm run buildfromdist/. Fetching directly from a Spark History Server is not available: the browser's CORS policy blocks it and a static host can't proxy the request. If a History Server load cannot be used, choose a local event-log file instead. - Local-server mode is a small Node companion that serves this app and fetches from a Spark History Server on your behalf (server-to-server, so no browser CORS restriction). Useful when the SHS is behind a VPN or isn't CORS-configured.
Run local-server mode with:
npx sparkforensics-server
It listens on http://127.0.0.1:4173 by default (override with --port or
the PORT env var) and binds to localhost only. Open the URL in Chrome and
use the Fetch from Spark History Server disclosure on the intake
screen. The same server serves the MCP tools over streamable HTTP at /mcp,
for clients on the same machine; see
Connecting over HTTP.
History Server fetching requires local-server mode, a History Server reachable from the machine running that server, and a supported base application ID (see Getting started for the full list of accepted forms). Enter an optional attempt separately from the base application ID. The local server sends no credentials and follows no upstream redirects. Its recoverable errors intentionally omit upstream response details; edit the fields or choose a local event-log file to recover.
During development from a checkout, npm run local-server does the same
thing without publishing or installing the package.
Server configuration
All settings have working defaults; override them with environment variables:
| Variable | Default | Effect |
|---|---|---|
PORT | 4173 | Listen port (the --port flag takes precedence) |
SPARKFORENSICS_SHS_TIMEOUT_MS | 30000 | Spark History Server fetch timeout: response headers must arrive within this window, and a streaming body that goes idle this long is cut off. Applies to both the /shs-proxy route and the MCP archive download. Progressing downloads of any size are unaffected. |
SPARKFORENSICS_MCP_CACHE_CAP | 8 | Max parsed runs kept in the MCP tool cache |
SPARKFORENSICS_MCP_CACHE_TTL_MS | 900000 | Idle eviction time for cached MCP runs (15 min) |
SPARKFORENSICS_MAX_ARCHIVE_BYTES | 1073741824 | Largest SHS event-log archive the MCP tools or the --shs-base-url CLI mode will buffer (1 GiB); larger responses fail with archive-too-large |
SHS-proxy route test fixture
The /shs-proxy route (packages/core/src/proxy.js) is covered by
packages/server/test/shs-proxy-fixture.test.js, part of the normal npm run test:server suite. It loads a real event log from the
spark-event-corpus-data git submodule at dev/log-corpus/ and asserts
the route streams it back as a valid ZIP. No Docker, no live Spark
process, and no live History Server are needed for this.
To verify the full Fetch-from-SHS UI flow by hand, including its
unreachable-upstream and application-not-found recovery states, point
npm run local-server at a real Spark History Server you have access to
and use its Fetch from Spark History Server disclosure. Automated
coverage of /shs-proxy uses the spark-event-corpus-data logs, so no
Docker image or live Spark process is needed.
Running tests
npm test              # single run
npm run test:watch    # watch mode
npm test -- tests/finding-filter.test.js  # single file
npm run test:core     # packages/core: detectors, analyzer, parser, MCP tools
npm run test:cli      # packages/cli
npm run test:mcp      # packages/mcp
npm run test:server   # packages/server
Command-line reference
Beyond the plain budget check in Get started, the same
sparkforensics-analyze CLI covers a few other jobs.
Write a self-contained HTML dashboard for the run instead of a JSON/Markdown
report, viewable offline over file:// with no server:
npx -p sparkforensics-cli sparkforensics-analyze path/to/eventlog --export-html path/to/output-dir
Fetch the run straight from a Spark History Server instead of a local file (mutually exclusive with the positional path):
npx -p sparkforensics-cli sparkforensics-analyze --shs-base-url http://history-server:18080 --app-id application_1234_0001 --max-skew 3
Compare a candidate run against a baseline (A/B) and fail the build on a regression or a newly introduced critical finding:
npx -p sparkforensics-cli sparkforensics-analyze path/to/candidate --baseline path/to/baseline --max-regression-pct 10 --fail-on-introduced critical
Several regression budgets in one call, and several candidates against one baseline (NDJSON, one line per candidate; the baseline is parsed once):
npx -p sparkforensics-cli sparkforensics-analyze cand-1 cand-2 cand-3 --baseline base --regression-budget wallClock:10 --regression-budget gcTime:25
See Several budgets and several candidates
for the --budgets file, the NDJSON line fields and the exit code rules.
Redact the app id, the app name and any host/IP tokens before sharing the output outside the environment that produced it:
npx -p sparkforensics-cli sparkforensics-analyze path/to/eventlog --redact
Narrow the output's findings array to certain impact bands, types, or a
stage (recommendations/cleanChecks/notRunChecks and the summary counts stay on the
full, unfiltered set):
npx -p sparkforensics-cli sparkforensics-analyze path/to/eventlog --impact critical,warning --type stageSlowness --stage 12
Other budget flags round out the checks: --max-spill <gb>,
--max-failed-task-rate <pct>, and --min-efficiency <pct> (busy core time:
the share of executor core time that ran tasks, 100 minus the dashboard's
Unused core time, not its Efficiency tile). --attempt-id
pairs with --shs-base-url/--app-id for a non-default attempt;
--regression-metric picks which metric --max-regression-pct checks
(default wallClock); --conf-keys and --conf-redact-regex shape the JSON
output's effectiveConf block, next to its metrics block (both in
Getting started);
--format md switches output to Markdown (default
json); --out <path> writes it to a file instead of stdout. Exit codes:
0 pass, 1 a budget was violated, 2 usage error (bad flags, arguments or
a --thresholds/--budgets file), 3 a budget was inconclusive (e.g. missing
evidence for a regression check), 4 the candidate log can't be read or
parsed, 5 the baseline log can't be read or parsed, 6 internal error. When
several apply, the worst wins in the order 6, 5, 4, 1, 3, 0; with
several candidates that means the worst line, and a candidate that can't be
read or parsed gives its own line 4.
Node version: the published
sparkforensics-cli,sparkforensics-mcp, andsparkforensics-serverpackages all pre-strip their vendored TypeScript to plain JS at publish time, sonpx-installed use only needs Node>=18(see each package'senginesfield). A checkout running any of the three straight offpackages/*/bin/againstpackages/core/src/*.ts(the monorepo dev-mode fallback) needs a Node version with native (unflagged) TypeScript type-stripping instead:>=22.18.0on the Node 22 LTS line, or>=23.6.0on Node 23+.
Learn more
The full documentation is published at shuffle-works.github.io/sparkforensics/docs.
- Getting started guide: reading the dashboard, run comparison, CI and automation
- Understanding findings
- MCP tools
- Detector roster
- Worker protocol
- Streaming/parsing design
- Widget layout
Contributing
See CONTRIBUTING.md.