Sugra API
Gateway between LLM agents and world data through eight tools and a bundled endpoint catalog.
One address for any MCP client. No sign-in needed on this server.
What it does
9 read2 other
Grouped by tool name. At most: only reads or looks up information.
What it costs
FreeOdel charges nothing per call. The publisher may charge for its own service.
Tools
11 · grouped by tool name · checked 9 Oct 2026Read · 9Look things up
- sugra_entity_lookup
- search_endpoints
- describe_endpoint
- list_toolsets
- fetch_data
- list_sources
- resolve_entity
- get_snapshot
- get_timeseries
Other · 2Neither hinted nor named
- sugra_entity_screen
- call_endpoint
sugra-api-mcp



Published in Anthropic's Connectors Directory. Available in Claude on the web, desktop and mobile, Claude Code and Cowork.
Published in the official OpenAI Plugins Directory. Available for ChatGPT and Codex.
Give any AI agent access to 1,600+ data endpoints across markets, economics, companies, government, news, climate, maritime and entity screening - through one MCP server.
Works with ChatGPT, Claude, Gemini, xAI, Cursor, VS Code and any MCP client.
Official Model Context Protocol server for the Sugra API: one connector, a bundled endpoint catalog, and structured tool results with source attribution on every answer.
See it in action
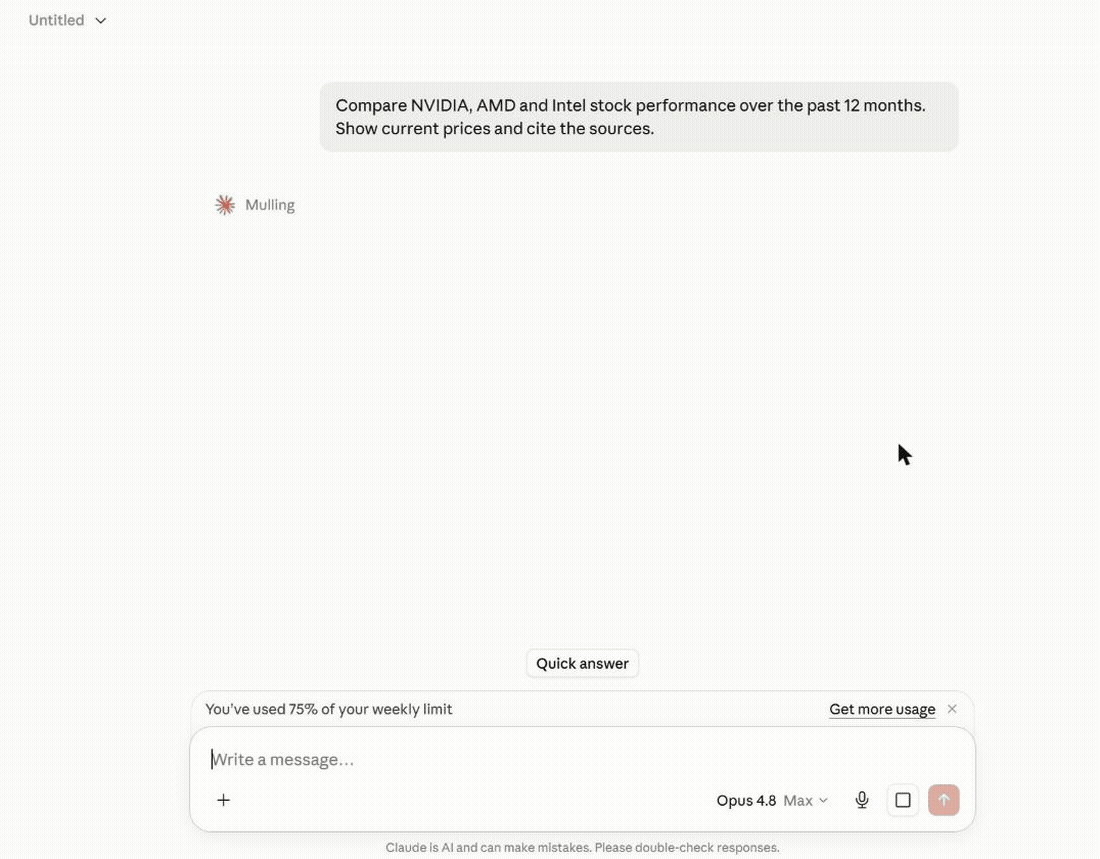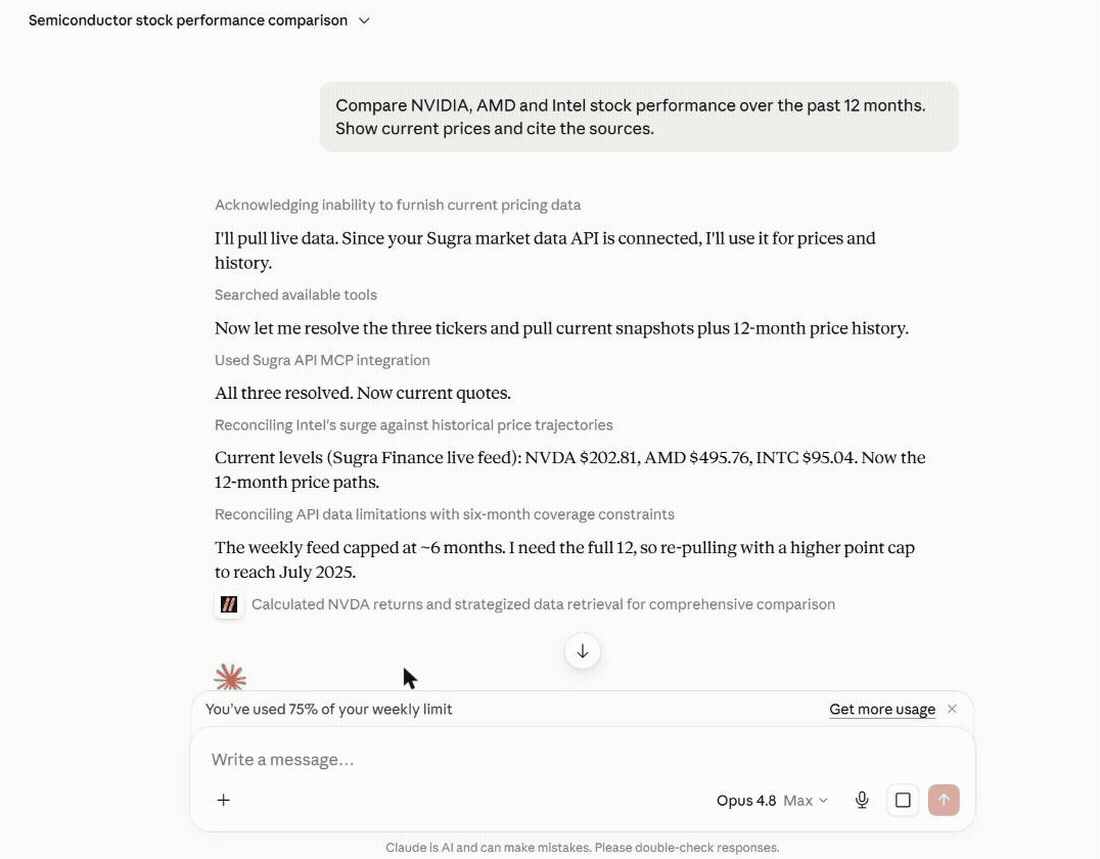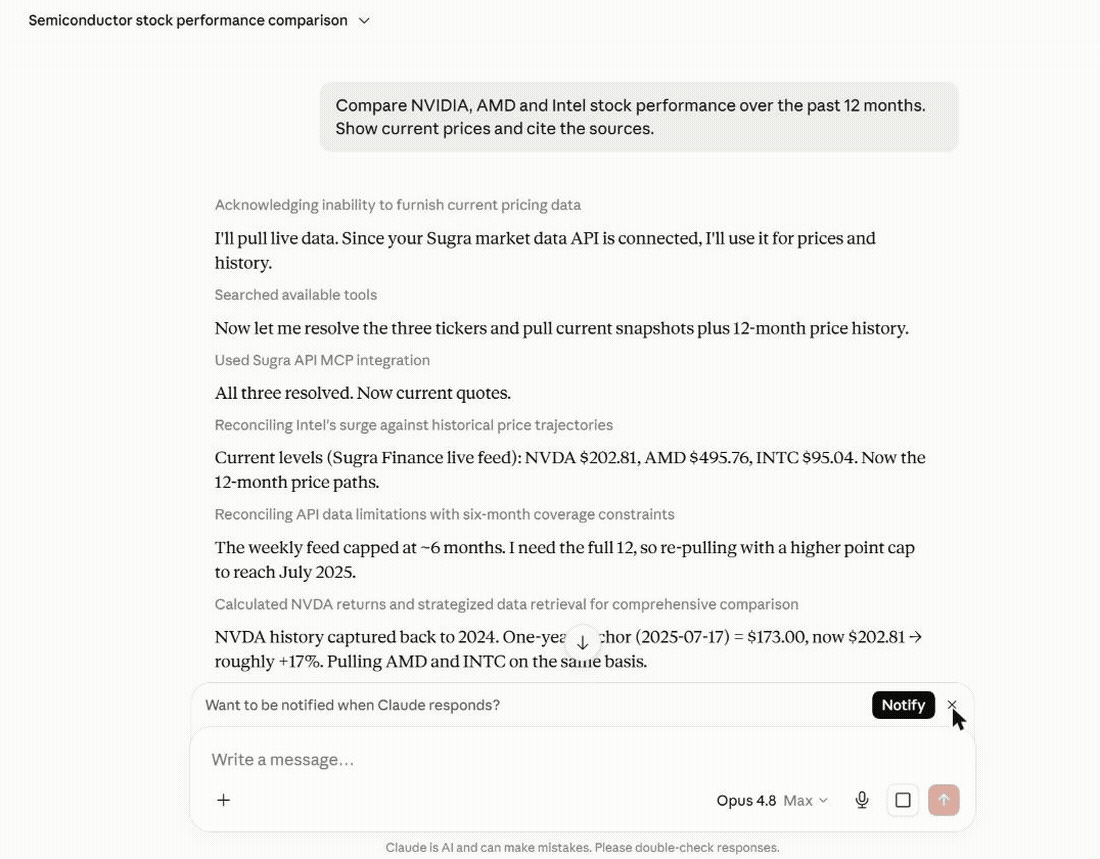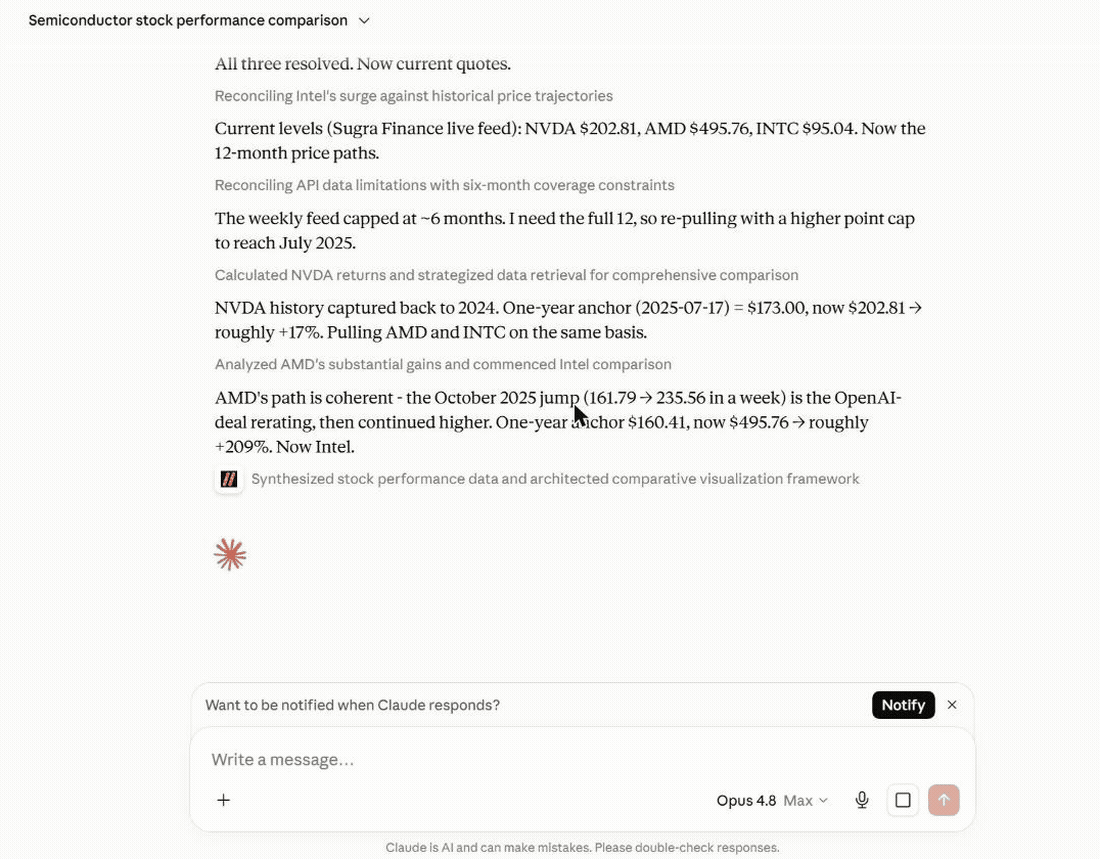
An agent answering a real question end to end - resolving entities, pulling live snapshots and history, and citing the source and freshness on every number:
More examples:
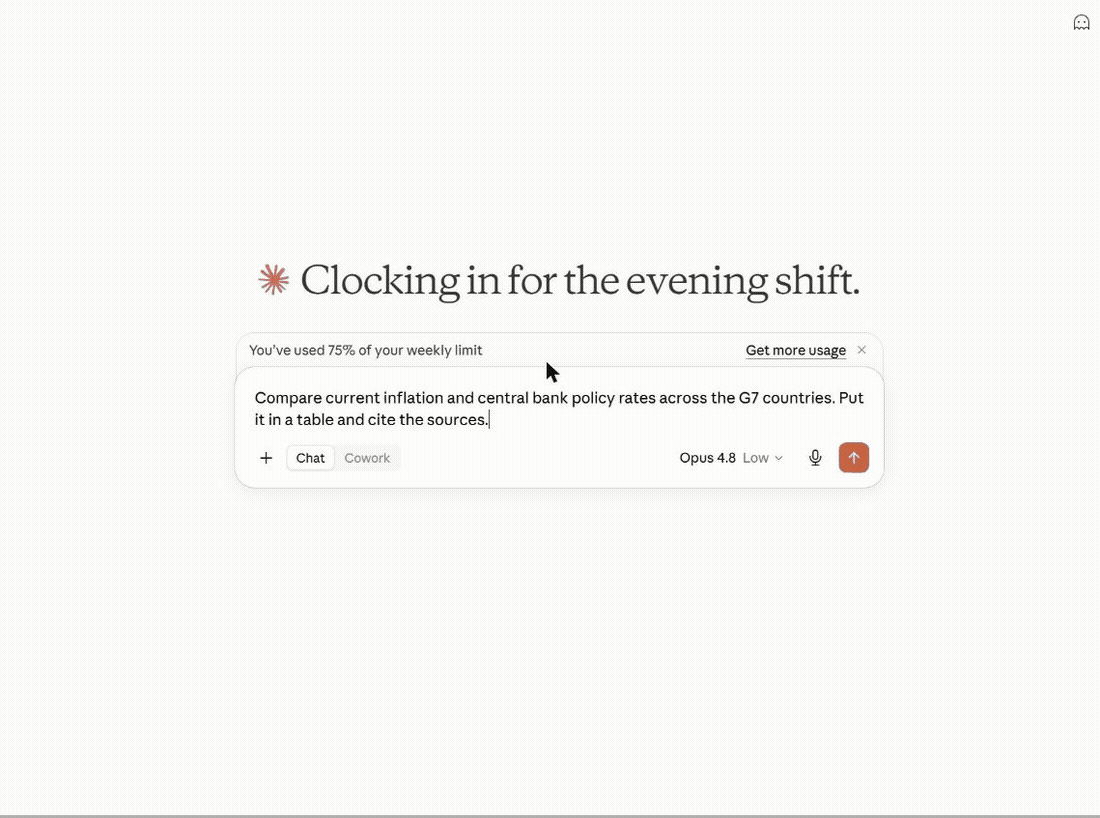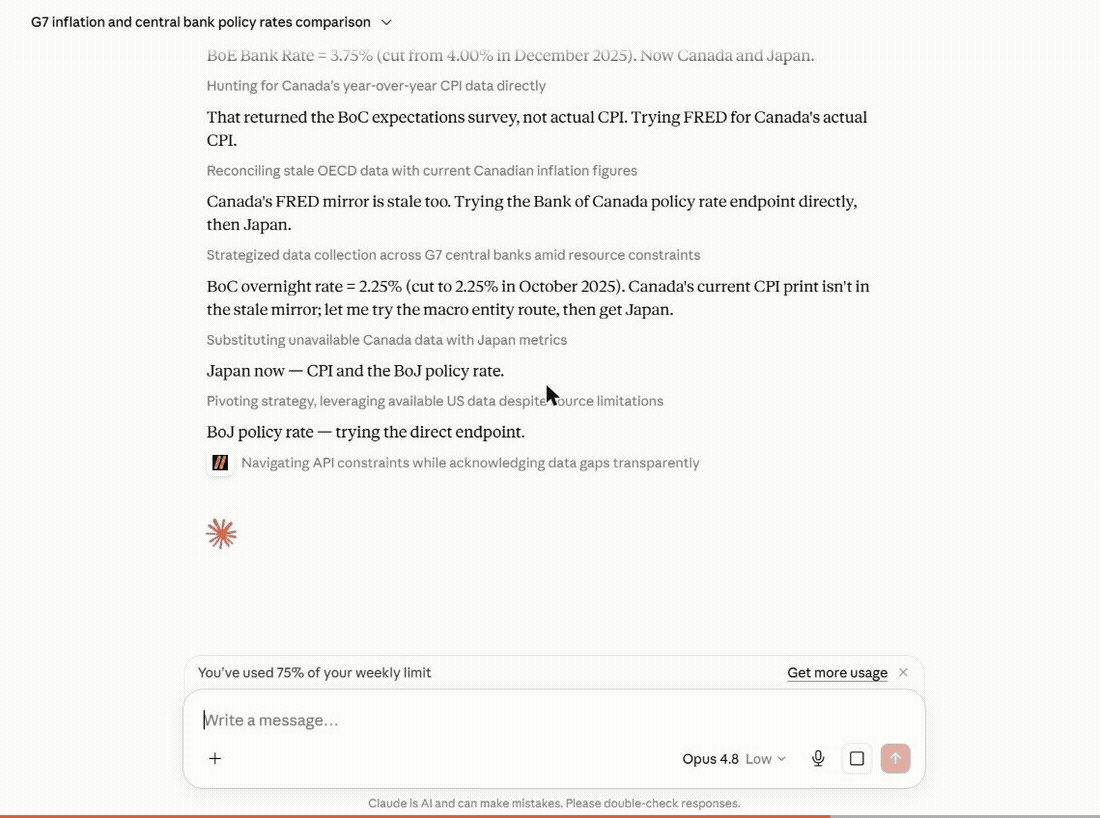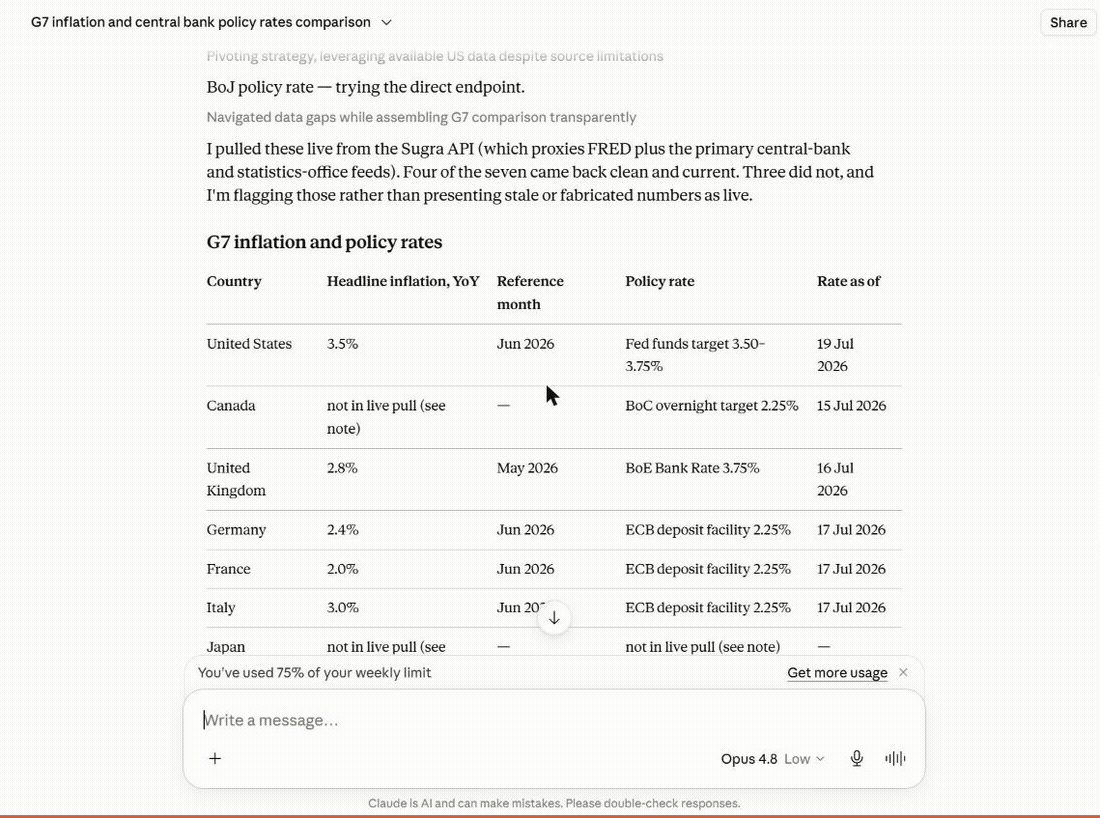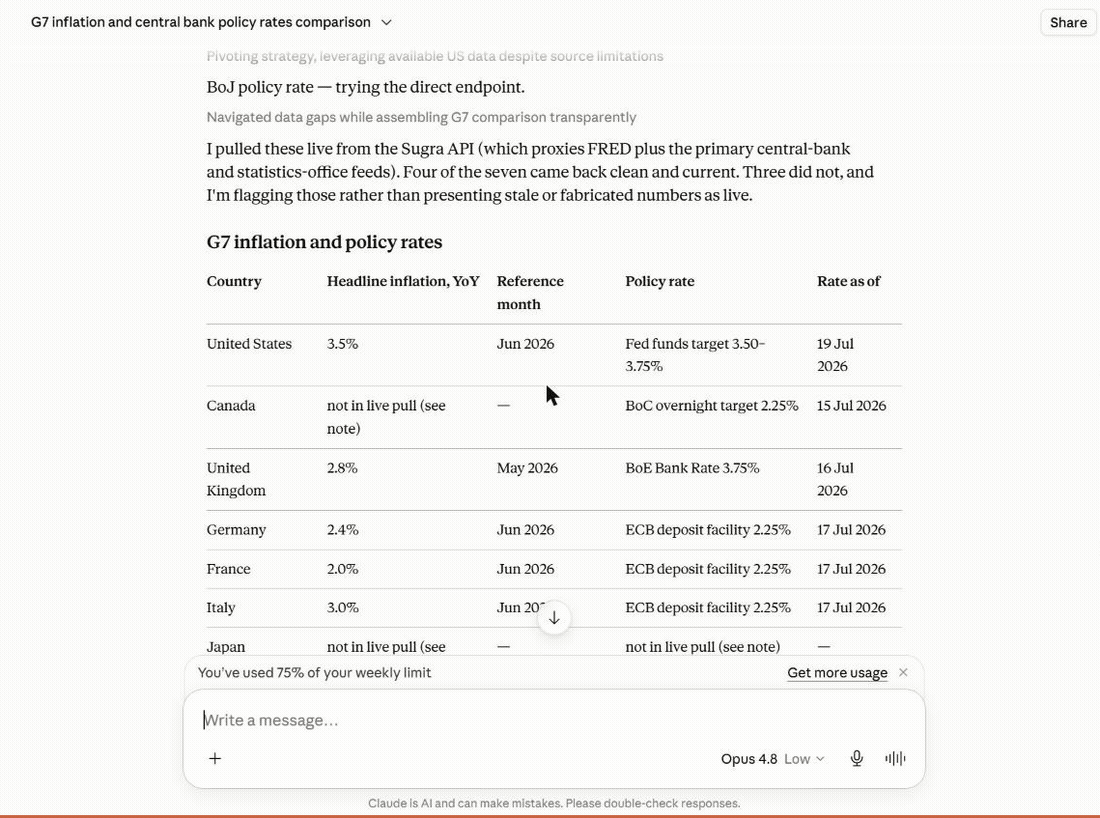
Macro research - one prompt builds a full G7 inflation and policy-rate table, each cell dated and sourced, with the unavailable ones flagged rather than faked:
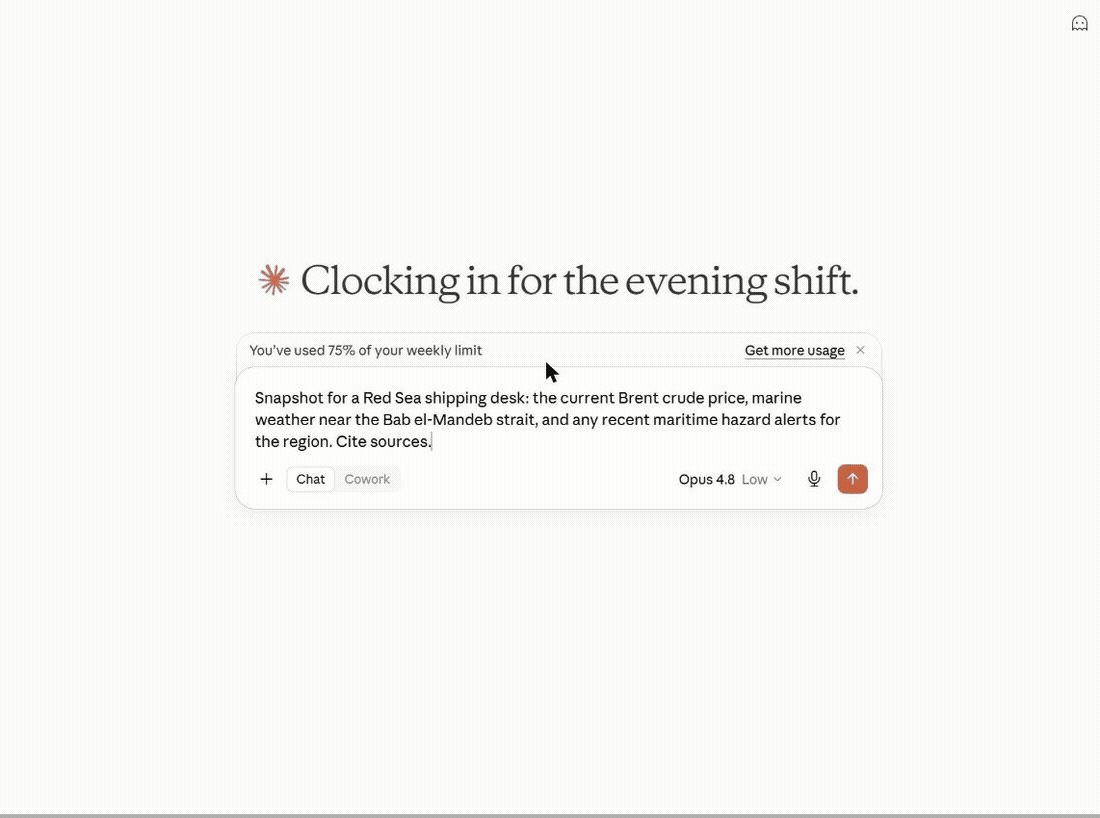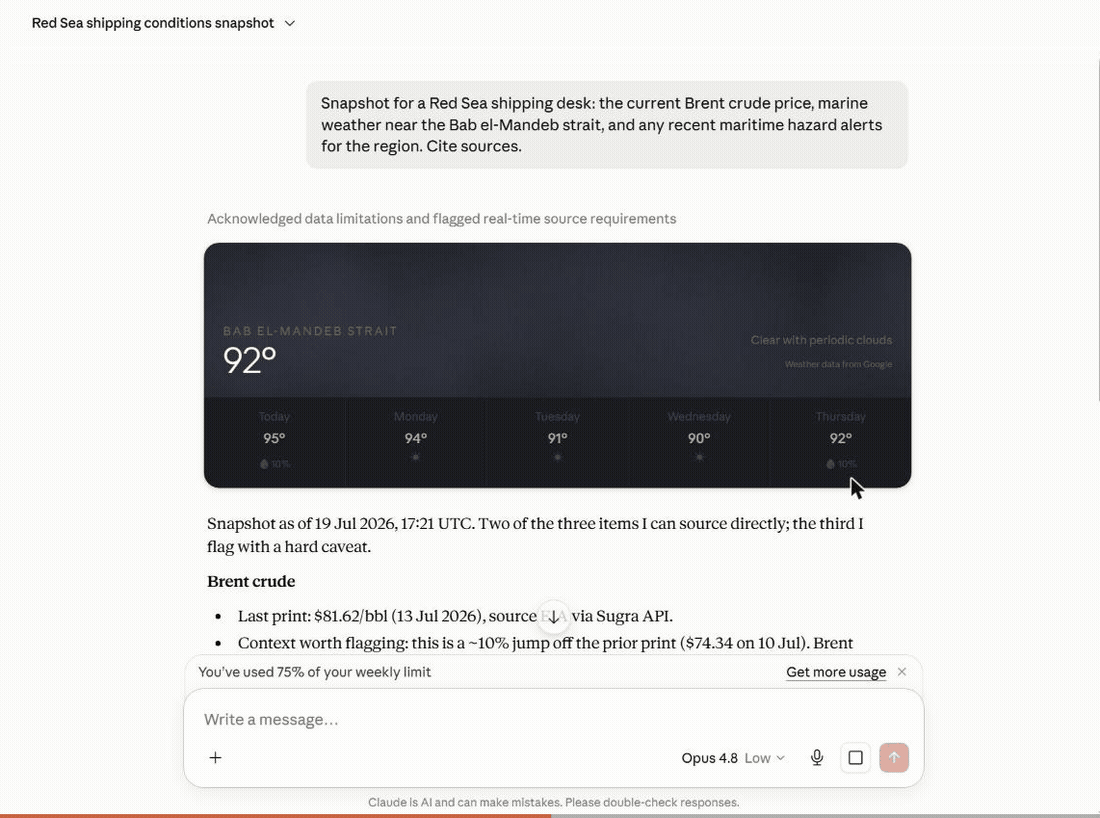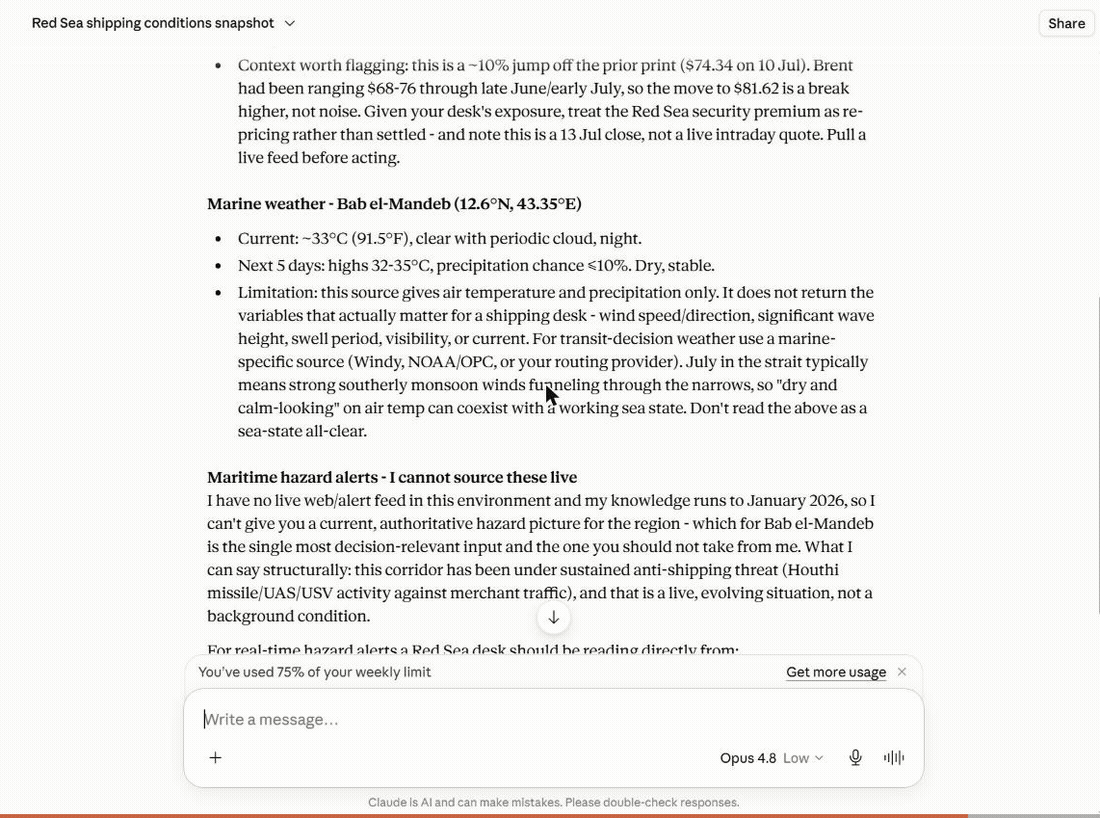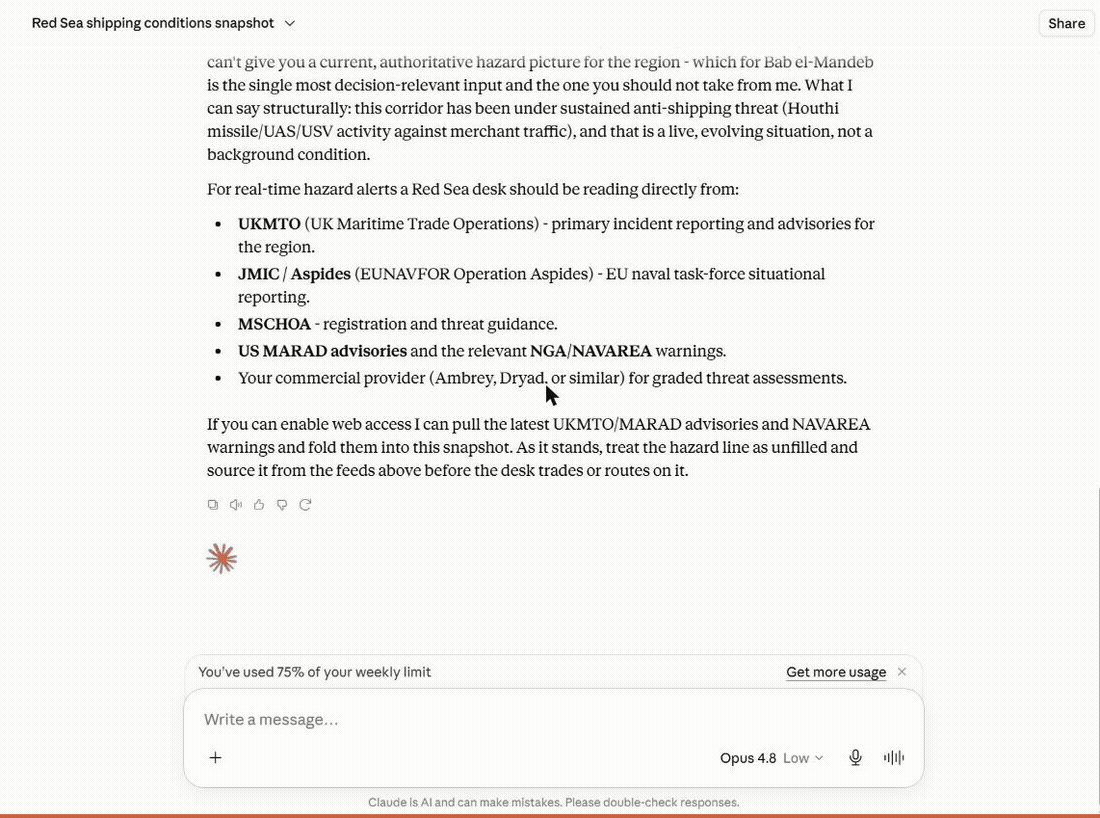
Cross-domain snapshot - Brent crude, marine weather and regional risk pulled together for a shipping desk, each with its source and timestamp:
What a session looks like
Hosted MCP transcript (the three composed tools shown here run on the hosted endpoint). Captured example - wording and figures vary by run and as new BLS data is published:
User: Where does US inflation stand, and how has it trended over the past year?

resolve_entity("US inflation")
  -> macro indicator cpi_us (U.S. Bureau of Labor Statistics)
get_snapshot("cpi_us")
  -> latest reading with freshness, provenance and quota cost
get_timeseries("cpi_us", metric="macro_series", range="1y")
  -> 12 monthly points with an explicit downsampling flag

Agent: US CPI printed 2.9% year over year in the latest release, down from
3.5% twelve months earlier - a steady decline since spring.
Source: U.S. Bureau of Labor Statistics via the Sugra API.
Every tool result carries structured metadata - source attribution, freshness, and rate-limit cost - so agents can cite sources and budget requests instead of guessing.
How it works
flowchart LR
    A["AI agent<br/>(ChatGPT, Claude, Gemini, xAI, IDEs)"] --> B["Sugra MCP<br/>gateway tools, plus agent tools when hosted"]
    B --> C["Sugra API<br/>1,600+ endpoints, 36 data domains"]
    C --> D["160+ primary sources<br/>markets, economics, government,<br/>news, climate, maritime"]
Behind the gateway sits the Sugra API: 160+ primary sources - sovereign statistics agencies, central banks, intergovernmental bodies and more - feeding 1,600+ endpoints across 36 data domains. The server ships a bundled catalog of the full endpoint surface, so discovery (search, describe, toolsets) runs locally without network calls; only actual data requests hit the API.
What agents build with it
The Sugra API skills live in Sugra-Systems/sugra-api-skills. The server serves five of them as MCP resources (sugra://skills/...) from a pinned commit of that repository: resources/read the URI after connect.
Agent skills
These skills teach the catalog loop. They do not add MCP tools. Connect the Sugra MCP server separately (hosted or local). The plugin package for each agent lives in Sugra-Systems/sugra-api-plugins.
Claude Code
/plugin marketplace add Sugra-Systems/sugra-api-plugins
/plugin install sugra-api@sugra-api-plugins
Skills appear as /sugra-api:<skill>, for example /sugra-api:discover-and-call.
Codex
codex plugin marketplace add Sugra-Systems/sugra-api-plugins
codex plugin add sugra-api@sugra-api-plugins
Grok
grok plugin install Sugra-Systems/sugra-api-plugins#xai
Cursor, Gemini CLI and other agents
npx skills add https://mcp.sugra.ai
Or copy the skill folders of sugra-api-skills into the agent's skills directory.
ChatGPT
The skills install from OpenAI's Plugins Directory. The MCP server attaches as a hosted connector at https://mcp.sugra.ai/mcp (permanent alias https://app.sugra.ai/mcp).
Six workflow prompts ship with the server and turn these into one-click flows in clients that surface MCP prompts:
- Market and macro research - "Compare inflation and central bank policy rates across the G7." (
macro_briefing) - Equity snapshots with sources - "Where does NVIDIA stand today - price, profile, and market backdrop?" (
market_snapshot) - Sanctions and compliance screening - "Screen this supplier and resolve its LEI identity." (
sanctions_screening) - Sector comparison - "Energy versus technology: valuations and flows side by side." (
sector_compare) - Climate, maritime and trade intelligence - "Red Sea shipping this week: chokepoint transits, crude price, and weather on the route." (
earth_conditionsplus the transport and commodities catalog) - Source discovery - "What does the catalog offer for fixed income, and from which institutions?" (
source_overview)
Every answer carries source attribution and freshness metadata, so agents cite instead of guessing.
Hosted MCP (recommended)
No install. In Claude, ChatGPT and Codex, add the Sugra API MCP server from a directory:
- Claude (web, desktop, mobile, Claude Code and Cowork): Add to Claude opens the Sugra API MCP server in Anthropic's Connectors Directory; connect it and sign in with your Sugra account. In claude.ai the directory is under Customize > Connectors. Claude Code signed in with a claude.ai account picks the connector up automatically;
/mcplists it. - ChatGPT and Codex: Add to ChatGPT opens the Sugra API MCP server in the OpenAI Plugins Directory.
Any other MCP client, or a manual setup, points at the hosted Streamable HTTP endpoint:
https://mcp.sugra.ai/mcp
- The gateway tools plus the composed agent tools
resolve_entity,get_snapshotandget_timeseries - OAuth sign-in through the Claude and ChatGPT connector flows, or
Authorization: Bearer sugra_xxx_...with an API key - As a custom connector in claude.ai: Customize -> Connectors -> Add custom connector
- In ChatGPT: Settings -> Connectors -> Add MCP server
Already added Sugra to Claude as a custom connector? That connection keeps working and shows under "Custom". Connecting the Sugra API MCP server from the directory as well gives you two connections, so remove the custom one first, then connect from the directory.
Local package
Runs on your machine over stdio (or self-hosted HTTP) with an API key:
pip install sugra-api-mcp
- Eight gateway tools
- stdio for desktop clients and IDEs, Streamable HTTP for self-hosting
- Authenticates with
SUGRA_API_KEY
Get a free API key at app.sugra.ai/register (Free tier: 50 req/day).
Quick start
pip install sugra-api-mcp
export SUGRA_API_KEY=sugra_xxx_...   # free key: app.sugra.ai/register
sugra-api-mcp call quotes_symbol_price --params '{"symbol":"AAPL"}'
The same call through an agent: connect the server to your client (next section) and ask "What is AAPL trading at? Use Sugra." The agent finds quotes_symbol_price in the catalog and calls it with the symbol.
Connect your client
Supported clients:
- Anthropic Claude: Claude Desktop, Claude Code (CLI), claude.ai (web)
- OpenAI GPT: ChatGPT (via MCP connector)
- Google Gemini: Gemini CLI, Gemini Code Assist (VS Code + JetBrains)
- xAI: Remote MCP Tools in xAI SDK and Responses API
- IDEs: VS Code (native), Cursor, Zed, Cline, Continue.dev, Windsurf
- Custom agents: anything built on the Python or TypeScript MCP SDK
Claude Desktop (stdio)
Add to claude_desktop_config.json:
- macOS:
~/Library/Application Support/Claude/claude_desktop_config.json - Windows:
%APPDATA%\Claude\claude_desktop_config.json - Linux: Claude Desktop has no Linux build. On Linux,
pip install sugra-api-mcpand use Claude Code (CLI), an IDE client, or the hosted HTTP endpoint below.
{
  "mcpServers": {
    "sugra": {
      "command": "sugra-api-mcp",
      "env": {
        "SUGRA_API_KEY": "sugra_xxx_yourkey..."
      }
    }
  }
}
Restart Claude Desktop. Sugra tools appear in the tools menu.
Claude Code (Anthropic CLI)
Signed in to Claude Code with a claude.ai account? Add to Claude connects the Sugra API MCP server from the Connectors Directory in claude.ai, and it appears in /mcp without any local install. To run the local package instead:
claude mcp add sugra -- sugra-api-mcp
# then set the env var that sugra-api-mcp reads
export SUGRA_API_KEY=sugra_xxx_...
Or edit ~/.claude/config.json manually with the same shape as Claude Desktop above.
To install the skills as a plugin (separate from the MCP server):
/plugin marketplace add Sugra-Systems/sugra-api-plugins
/plugin install sugra-api@sugra-api-plugins
Usage with Gemini CLI
Gemini CLI reads MCP servers from ~/.gemini/settings.json (user scope) or
.gemini/settings.json in the project. For a local stdio install, add:
{
  "mcpServers": {
    "sugra": {
      "command": "sugra-api-mcp",
      "env": {
        "SUGRA_API_KEY": "sugra_xxx_yourkey..."
      }
    }
  }
}
If the console script is not on PATH, use "command": "python" with
"args": ["-m", "sugra_api_mcp"] instead. The equivalent Gemini CLI command
is:
gemini mcp add --scope user -e SUGRA_API_KEY=sugra_xxx_yourkey... sugra sugra-api-mcp
Or connect to the hosted endpoint without installing the package:
gemini mcp add --scope user --transport http \
  --header "Authorization: Bearer sugra_xxx_yourkey..." \
  sugra https://app.sugra.ai/mcp
Run gemini mcp list to check the connection, then enter /mcp in an
interactive session to inspect the available tools. A local stdio connection
shows the eight gateway tools in Tool reference; the hosted
endpoint also shows the three hosted-only agent tools.
If a local server does not connect from a new directory, review and trust that
workspace with gemini trust before retrying.
These examples were checked against the Gemini CLI MCP documentation and Gemini CLI v0.51.0.
Cursor, Zed, Cline, Continue.dev, Windsurf
Each of these has an MCP settings file (typically mcp.json or equivalent) with the same stdio config shape as Claude Desktop.
ChatGPT
Add to ChatGPT installs the Sugra API MCP server from the OpenAI Plugins Directory. Or add the hosted HTTP endpoint (below) as an MCP connector, since ChatGPT does not launch local stdio processes.
HTTP (claude.ai, ChatGPT, remote agents)
In claude.ai, Add to Claude connects the Sugra API MCP server from Anthropic's Connectors Directory; in ChatGPT, Add to ChatGPT installs it from the OpenAI Plugins Directory. For a manual setup or any other Streamable HTTP MCP client, use the hosted endpoint:
https://mcp.sugra.ai/mcp
Authenticate with OAuth in the connector flow or with Authorization: Bearer sugra_xxx_....
As a custom connector in claude.ai: Customize -> Connectors -> Add custom connector. In ChatGPT: Settings -> Connectors -> Add MCP server.
Tool reference
The local package exposes eight gateway tools. The hosted endpoint adds three composed analysis tools on top (see Hosted MCP above). The package exposes exactly eight tools:
| Tool | Purpose |
|---|---|
fetch_data | One-step: find best endpoint for a natural-language query and call it. Combines search + call in one round trip. |
search_endpoints | Search the bundled endpoint catalog. Runtime search does not fetch /openapi.json. |
describe_endpoint | Inspect an endpoint by operation_id, including path, method, parameters, required inputs, agent_hints, and request_body_schema for JSON-body POST operations. |
call_endpoint | Call a Sugra API operation by operation_id. Arbitrary path calls are no longer supported. |
list_toolsets | List catalog groups with endpoint counts and descriptions. |
list_sources | Show bundled catalog source metadata. |
sugra_entity_screen | Screen a name against sanctions and watchlists (Sugra Entity). |
sugra_entity_lookup | Composed entity lookup by identifier - anchor is lei or vat, plus the identifier value; returns registry identity + screening (Sugra Entity). |
call_endpoint and fetch_data both support response shaping with limit, fields, and include_raw. Shaping works on enveloped ({"data": ...}) and envelope-less payloads alike; fields entries may use dotted paths into nested objects (geo.city), and meta.shaped reports what was actually applied (fields_applied / fields_unmatched, limit_applied, records_path, order, kept_end) rather than echoing the request. limit and fields work on the records list: the envelope data list, a bare top-level array, or the one list inside an object data when exactly one of data, entries, events, history, items, observations, points, records, results, rows, series, timeseries holds a list (for example data.items on the latest news, data.observations on a FRED series). When data has no such single list but every one of its values is an object holding exactly one list named observations, as with several named sub-series side by side, limit bounds each data.<key>.observations list on its own; fields there still names keys of data. Keys beside that list, such as total and count, stay as sent, and lists nested inside records are never truncated. A fields entry that names a key of data itself projects that object instead, and a projection that matches nothing leaves the payload whole. meta.shaped.limit_applied says whether the bound took effect, and meta.shaped.records_path names the list used (data, data.<key>, data.*.observations, or null when no records list was used). limit keeps the newest end of the records list when every record carries one date or period key (such as date, period or year) in one format and the list runs one way by it: the last N records of an oldest-first list, in their order, or the first N of a newest-first list. Otherwise it keeps the first N records. Whenever a limit bounds a records list, meta.shaped.order says asc, desc or unknown and meta.shaped.kept_end says newest or first, each as a map by sub-series name for sibling sub-series. A top-level JSON array (or scalar) is always wrapped as {"data": ...} so the MCP result stays an object; otherwise FastMCP output validation reports the successful call as an error and drops the rows.
fields takes at most 32 paths, each at most 256 characters and 16 dotted parts; past any of these the call answers projection_too_large before any request is made. With fields, one projection also visits at most 100,000 list items, runs for at most 5 seconds, and takes a response of at most 2,000,000 characters of JSON before projection. That bound sits far above the 18,000-character limit on the result, which applies after projection: a 16-day weather forecast is about 295,000 characters before fields=["daily"] cuts it to fit. None of these bounds applies without fields. Shaping runs on its own pool of two worker threads, never on the event loop: at most 8 jobs run or wait for a worker, 4 of them for one caller, and a call that finds no free slot within 2 seconds answers server_busy with scope shaping or caller_shaping.
describe_endpoint returns computed agent_hints per endpoint so agents can budget time and parallelism before calling:
duration_class-fast(under ~2s, snapshot-backed),slow(live upstream proxying, occasionally 15s+), orheavy(per-item upstream work, large batches can exceed the gateway timeout)max_concurrency- advisory ceiling for parallel calls from one sessionbulk_cost- on per-item bulk endpoints: 1 request credit per item in the request body (the API reports the total in theX-RateLimit-Costresponse header)
Hosted-only agent tools (app.sugra.ai/mcp)
The hosted MCP endpoint at https://app.sugra.ai/mcp serves the same eight tools PLUS three composed agent tools that are not available on stdio or self-hosted installs:
| Tool | Purpose |
|---|---|
resolve_entity | Free text (ticker, company, indicator, coin, currency pair) to a canonical market or macro entity. Ambiguous matches return ranked candidates, never a silent pick. |
get_snapshot | Entity plus a named recipe to one composed current view with freshness, provenance, coverage, and billing blocks. Composed calls charge a fixed recipe cost (1-2 requests) from the daily quota. |
get_timeseries | Entity plus metric (price, macro_series, etf_flows, etf_monthly_flows) to a bounded series with an explicit downsampling flag. etf_flows estimates at filing cadence; etf_monthly_flows is the fund's own NPORT-P monthly creations and redemptions. |
These three tools wrap an internal composed plane that requires an infrastructure credential available only on the hosted deployment. The tool code ships inside the package, but it is registered only by the hosted HTTP entry point and only when that credential is present - pip install sugra-api-mcp (stdio and self-hosted HTTP) always exposes the classic eight-tool gateway. Hosted-only examples in any documentation are labeled as such. For compliance entity lookups (LEI / VAT, sanctions screening) use sugra_entity_lookup and sugra_entity_screen, which work on every transport.
CLI
Server startup is unchanged:
sugra-api-mcp
sugra-api-mcp --transport streamable-http --port 8001
Catalog and gateway helpers:
sugra-api-mcp doctor
sugra-api-mcp list-toolsets
sugra-api-mcp search "NASDAQ futures"
sugra-api-mcp describe cot_financial
sugra-api-mcp call quotes_symbol_price --params '{"symbol":"AAPL"}'
Environment variables
User-facing configuration for local installs, MCP clients, Docker stdio, and directory sandboxes (for example Glama Try in Browser). Set only this:
| Variable | Required | Default | Description |
|---|---|---|---|
SUGRA_API_KEY | For API calls | - | Your Sugra API key (sugra_...). Get a free key at app.sugra.ai/register (Free tier: 50 req/day). Not needed to start the server: catalog tools (search_endpoints, describe_endpoint, list_toolsets, list_sources) work without it; API-calling tools return a structured missing_api_key error until it is set. In HTTP mode with a client Bearer token this is only a fallback. |
Optional overrides (leave unset unless you need them):
| Variable | Default | Description |
|---|---|---|
SUGRA_API_BASE | https://sugra.ai | Override the Sugra API base URL (self-hosted or beta API only). |
SUGRA_TIMEOUT | 30 | Downstream HTTP timeout in seconds for calls from this server to the Sugra API. |
Operator-only settings for self-hosted Streamable HTTP (reverse proxy CORS/hosts,
OAuth authorization-server wiring, and shared secrets) are documented in
docs/self-hosting.md. Do not put operator secrets into
public directory sandboxes. SUGRA_MCP_TRUST_PROXY_HEADERS (off by default)
makes the server read X-Real-IP and X-Forwarded-Host; set it only behind a
reverse proxy that overwrites both on every request, and never where clients
can reach the process directly (details in the same guide).
SUGRA_MCP_LIMITS (off by default) turns on request limits counted in the
server's own memory; the same guide lists its settings.
HTTP transport with OAuth
When running with --transport streamable-http the server allows unauthenticated MCP discovery requests (initialize, notifications/initialized, tools/list, resources/list, prompts/list, and ping) so ChatGPT Apps and other mixed-auth clients can discover tool metadata. Tool calls still require Authorization: Bearer .... Two token formats are accepted:
- Raw API key (
sugra_...) - passed through as the downstreamx-api-key. Compatible with earlier local API-key setups. - OAuth JWT - signature verified against the issuer's JWKS. The audience must match
https://app.sugra.ai/mcp, the token must includesugra:read, and hosted access is validated against APP before resolving the user's primary API key. Successful hosted OAuth requests update MCP connection activity in APP.
Most users should use the hosted endpoint https://app.sugra.ai/mcp instead of
self-hosting OAuth. If you run your own HTTP process, see
docs/self-hosting.md.
Timeouts and the error contract
SUGRA_TIMEOUT caps each downstream HTTP call from this server to the Sugra API (default 30 seconds). It is one link in a longer chain; when a tool call fails, elapsed_ms in the error payload tells you which link cut it:
MCP client (agent harness)         own tool timeout, often 60-180s, client-controlled
  -> hosted proxy (app.sugra.ai)   86400s, effectively unlimited
    -> this server (httpx)         SUGRA_TIMEOUT, default 30s
      -> Sugra API -> upstreams    15-60s per upstream call, server-side
Tool failures return structured JSON instead of raising, so agents can pick a retry strategy:
error value | Meaning | Retry strategy |
|---|---|---|
upstream_timeout | No response within SUGRA_TIMEOUT (elapsed_ms close to timeout_s x 1000) | Retry once: the aborted attempt usually completes server-side and warms upstream caches. Then narrow the request (smaller batch, tighter filters). |
upstream_connect_error | Could not reach the Sugra API (DNS failure, connection refused) | Retry after a short delay. |
upstream_transport_error | Connection dropped mid-request | Retry once. |
free-text string + status_code | The API answered with HTTP 4xx/5xx; retry_after included when the API sent a Retry-After header | Honor retry_after for 429/503; fix the request for 4xx. |
tool_execution_failed | Unexpected failure inside the gateway (exception_type included) | Report if persistent. |
query_too_long | A search_endpoints or fetch_data query has more than 64 terms or 1000 characters (max_terms and max_chars included). A term is a run of two or more ASCII letters or digits, and repeats count; nothing was searched | Shorten the query to the instrument, series, place or task. |
projection_too_large | A fields projection passed one of its bounds. limit_kind names it: fields (more than 32 paths), path_chars (a path over 256 characters), path_parts (a path over 16 dotted parts), rows (over 100,000 list items visited), shaping_ms (over 5 seconds) or raw_chars (a response over 2,000,000 characters before projection). limit, actual, field_index (from 0, for path_chars and path_parts) and operation_id are included, never the field text; the first three kinds are refused before any request is made | Name fewer or shorter fields, add limit, narrow the request, or omit fields. |
server_busy | A concurrency limit was reached. scope is tool_calls, search or shaping for a server-wide limit, caller_tool_calls, caller_search or caller_shaping for the limit on one caller. With shaping or caller_shaping the API request was already made and its response was dropped; with any other scope the call did no work | Retry after a few seconds. |
All error payloads carry elapsed_ms. url is present on transport and HTTP errors (not on tool_execution_failed, which can fire before a URL exists). On the three transport errors status_code is null (no HTTP status was received) - consumers comparing status_code numerically should guard for that. If a tool call instead fails with a bare client-side message and no structured JSON, the timeout fired in your agent harness above this server: raise the client's tool timeout, not SUGRA_TIMEOUT.
Examples
Ask Claude:
- "Search Sugra endpoints for NASDAQ futures."
- "Describe the
cot_financialoperation." - "Call
quotes_symbol_pricewith symbol AAPL and return only symbol and price." - "List available Sugra toolsets."
Troubleshooting
Looking for get_market_price, get_macro_indicator, or get_news? Those curated tool names appear in some older directory listings and never shipped in this package - use fetch_data for one-step natural-language calls or search_endpoints plus call_endpoint for explicit routing.
missing_api_key in tool responses
The server starts and lists its tools without a key, but API-calling tools (call_endpoint, fetch_data, the entity tools) return {"error": "missing_api_key"} until the server can find one. Depending on how you run it:
- As an MCP tool from your client (Claude, ChatGPT, Gemini, xAI, IDE, etc.): check the
envblock in your MCP config file. Value should be a full key likesugra_ao1_..., not empty and not wrapped in extra quotes. - Shell / CI:
export SUGRA_API_KEY=sugra_...before runningsugra-api-mcp. - HTTP mode: set via
.envor systemdEnvironmentFile, not the shell.
sugra-api-mcp doctor reports whether the key is visible to the process.
401 Unauthorized or 403 Forbidden in tool responses
Key accepted but rejected. Common causes:
- Key was regenerated in app.sugra.ai/developer/keys and your config still has the old one.
- Typo - key contains only lowercase letters and digits, no spaces, no trailing newlines.
- Free tier was deactivated. Sign in to verify status.
429 Too Many Requests
Hit your plan's daily limit. Response headers include X-RateLimit-Reset with the UTC timestamp when the counter resets (midnight UTC). Over MCP the tool result carries reason: daily_limit_reached, status_code: 429, retry_after, and daily_limit and plan when the API named them. Plans: sugra.systems/api/pricing.
Invalid Host header (only if self-hosting HTTP mode)
FastMCP has DNS rebinding protection for public hostnames behind a reverse proxy. See docs/self-hosting.md for the allowed-hosts setting.
Tool result truncated with meta.truncated notice
Some endpoints return very large payloads (long price histories, hourly forecasts, full catalogs). A result is capped at 18,000 characters of JSON with ASCII escapes, so a CJK or accented character counts as its six-character escape and non-ASCII text is counted generously. Clients limit what they pass to the model in their own ways: Claude Code writes a tool result over 50,000 characters to a file instead of handing it to the model, and Codex limits a tool result by tokens, with a budget the user sets, and cuts the middle out beyond it. Every shape we measured at 18,000 characters, the densest included, stayed within Codex's default budget; a denser result, or a lower budget set in the client, can still be trimmed by the client. The cap is the same for every client. A larger result is cut to fit, whatever its shape: the lists at most two levels under data (data, data.<key>, data.<key>.<key>, whatever the key is called) are measured record by record, a big list is cut before small ones beside it, and a cut list keeps at least one record. A list keeps the newest end by the same order rule as limit, else its first records; through call_endpoint, a forecast or calendar keeps its records from today onward instead, oldest-first or newest-first alike, with kept_end nearest. fetch_data keeps the newest or first records and its hints name no parameter yet. The cut runs on the shaping pool, never on the event loop, so a full pool answers server_busy; it has a 5-second clock, read between records, and past it the result is refused; the fixed tools stop waiting for a cut half a second after that clock, and call_endpoint half a second after two such clocks, as its fields projection has its own; both then answer response_too_large, and a cut that cannot start within the pool's 2-second wait answers server_busy. The fixed tools gate an error body like any other result; an error payload over the cap that call_endpoint passes on as it came is refused without being measured. meta.truncated says what was cut: reason (exceeds_response_size_cap), path of the largest list cut with its original_count, kept_count, order and kept_end, the sizes original_chars, kept_chars and cap_chars, a lists entry per path (with kept_range, the first and last date kept) when several lists were cut, and a retry_hint that names what was kept and only the parameters the operation has. A forecast of up to about two weeks keeps the hours from today and its whole daily list, and the hint offers fields=["daily"] or a smaller params.forecast_days; a 16-day forecast can lose its last days as well, and its hint then offers only a smaller params.forecast_days, although fields=["daily"] returns all 16 days within the cap; a quote history keeps its newest bars, and the hint offers params.limit or a narrower params.start to params.end. When no cut fits, the result is a response_too_large error whose message gives the size and the limit in characters and names the large part: a record that is larger than the limit by itself, a record that does not fit beside the rest of the response (with both sizes), or the part outside the lists that is too large, and when it can, the fields that leave the large part out. The refusal itself always fits the cap: when it would not, it keeps only the size line and a URL cut to 300 characters.
Python version 3.11 or higher is required
sugra-api-mcp requires Python 3.11+. Check: python --version. If you have 3.10 or older:
- Ubuntu: install Python 3.11 or newer from your distribution packages or the deadsnakes PPA.
- macOS:
brew install python@3.11 - Windows: download from python.org
Then recreate your venv.
Hosted app.sugra.ai/mcp returns 5xx
The hosted endpoint can briefly restart after deploys. Wait 60 seconds and retry. If persistent, email support@sugra.systems.
Debugging tool calls locally
Run with stdio and log JSON-RPC messages:
SUGRA_API_KEY=sugra_... sugra-api-mcp 2>&1 | tee mcp-debug.log
Send manual JSON-RPC from a second terminal using nc or an MCP inspector.
Development
git clone https://github.com/Sugra-Systems/sugra-api-mcp
cd sugra-api-mcp
pip install -e ".[dev,http]"
export SUGRA_API_KEY=sugra_...
python -m sugra_api_mcp  # stdio mode
python -m sugra_api_mcp --transport streamable-http --port 8001  # HTTP mode
python scripts/build_endpoint_catalog.py  # rebuild bundled catalog from sibling API openapi.json
python scripts/build_endpoint_catalog.py --source https://sugra.ai/openapi.json  # from the live spec
# On DRIFT, catalog-parity.yml opens or updates PR branch ci/catalog-resync.
Run tests:
pytest
Docker
Build the image from the repository root:
docker build -t sugra-api-mcp .
Run in stdio mode (the default entrypoint) for MCP clients that spawn a local process:
docker run -i --rm -e SUGRA_API_KEY=sugra_... sugra-api-mcp
Run the Streamable HTTP transport on port 8001 with Docker Compose:
export SUGRA_API_KEY=sugra_...
docker compose up -d
Then point your MCP client at http://localhost:8001/mcp. The compose service
passes SUGRA_API_KEY and the optional overrides (SUGRA_API_BASE,
SUGRA_TIMEOUT) from your shell when set, and checks container health against
http://localhost:8001/health. Reverse-proxy and OAuth operator settings are
documented in docs/self-hosting.md.
Every response the application sends, errors included, carries the header
Server: sugra-api-mcp. So does uvicorn's own 400 for a request it cannot
parse under the httptools parser, which the http extra installs and uvicorn
picks by default; under the h11 parser that 400 goes out without the header.
Set SUGRA_MCP_SERVER_VERSION=1 (or true, yes, on) in the server's
environment to add the package version to that header
(sugra-api-mcp/<version>) and to the /health response, which leaves the
version out otherwise.
A note on auth: no environment variable is baked into the image and none is
required for the container to start. In HTTP mode clients authenticate per
request with Authorization: Bearer sugra_..., so SUGRA_API_KEY on the
container is only a fallback for requests without a Bearer token.
License
MIT © 2026 Sugra Systems, Inc.