Listed from the MCP registry; nobody on Odel publishes it. Is this yours? Claim @ahmedeid1
Lumen
Self-hostable agentic-AI LMS: catalog, RAG tutor, FSRS reviews, AI authoring, ingest.
Runs on your machine from its package; the steps are below.

What it does
- Reads
- Writes
- High impact
At most: creates or changes data: records, files, settings.
What it costs
FreeOdel charges nothing per call. The publisher may charge for its own service.
Runs locally
This server runs on your machine over stdio, but its source registry didn't list a distribution package. Check the source repository for setup instructions.
Lumen
Type a one-sentence learning goal. An AI orchestrator builds you a private course (45–90 s for 10 lessons), a course-scoped RAG tutor teaches it with lesson citations, and its agent steps and LLM calls are logged.
Custom multi-agent system, no LangChain · public evals with the weak scores kept in · ran in production on AWS, May to October 2026



Walkthrough video · Screenshots · Eval results · Architecture · MCP server
Production recording from May 2026, on Groq Llama 3.3 70B (since retired). Intake sped up 6×, build 16×; the brief and the finished course play in real time.
In production a 10-lesson course built in 45–90 s after the intake on Groq gpt-oss-120b: about 45 s in three timed builds in October 2026, 75–92 s in the two builds recorded on the last live day (archive).
The hosted demo was retired on 2026-10-30. The walkthrough video and screenshots record its last live version; run it locally with the quick start below, or redeploy it.
What this is
A learner-owned, two-role e-learning platform — every signed-in user runs the whole loop themselves; admin only moderates and configures. The product is the loop; the point of the repo is the agentic system underneath it.
| Step | What happens |
|---|---|
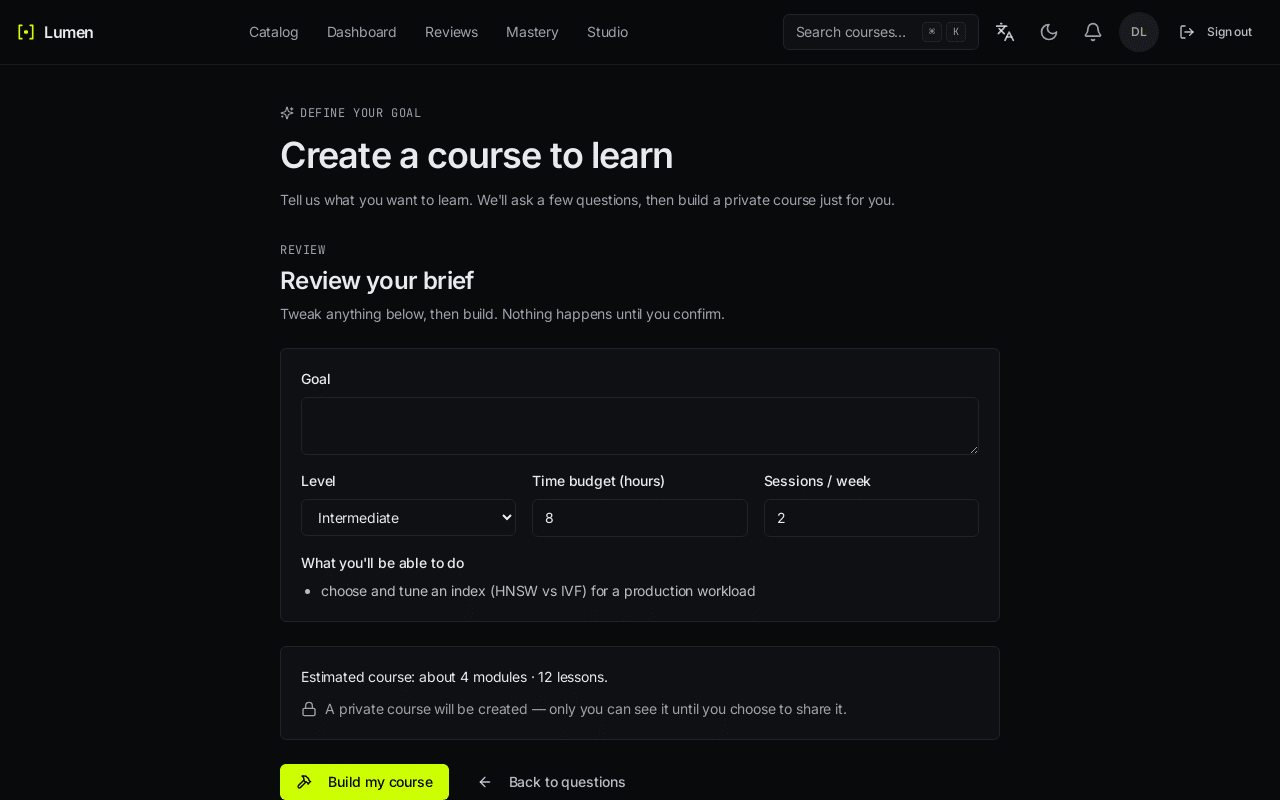
| Define | A guided AI intake (capped at six turns) turns a fuzzy goal into a structured learning brief — the source goal is field-encrypted at rest |
| Build | The authoring orchestrator builds a private course from the brief — honest status, no half-finished partials, re-runnable, cancellable (build.py, the durability/idempotency/quota shell) |
| Learn | A course-scoped RAG tutor answers with lesson citations and a visible tool-call trace |
| Share | Publishing stays private; public listing is an explicit share + admin moderation state machine with an immutable audit trail |
| Clone | Any listed course can be remixed into your own draft, with server-written "Based on …" provenance and a sanitized export (no enrollments, traces, or soft-deleted content) |
| BYOK | Bring your own model key (OpenAI / Anthropic / Groq / Mistral) — allowlisted providers, server-owned base URLs, envelope-encrypted write-only keys |
Shipped to production as 2.0.0-two-role (CHANGELOG) — built as a gated waterfall: requirements → design → 6 ADRs → seven build streams, each cleared a Codex challenge, an independent Claude review, and a live in-browser walk before merge.
The agentic layer
Everything below ran in the hosted demo, with the code one click away. One exception: the web tutor streams a simpler retrieve-then-answer path (next section).
Custom multi-agent orchestrator — no frameworks
The tutor's planner picks per turn among five sub-agents in tutor_subagents/ — retriever, web_searcher, code_runner, quiz_generator, concept_explainer — with a cap of five tool-call rounds (tutor_orchestrator.py). The planner runs behind the tutor API (POST /api/v1/tutor/conversations/{id}/messages) and the MCP ask_tutor tool. web_searcher was off in the hosted demo, because no Tavily key was set there.
The web tutor streams a shorter path (tutor_orchestrator_stream.py): one course-scoped retrieval (top 6 chunks) and one streamed answer. It shows a plan step, but no planner call runs.
The authoring side runs a six-stage pipeline — researcher → outliner → critic → reviser → lesson-drafter → final-critic — in authoring_orchestrator.py, capped at six revise/critic calls.

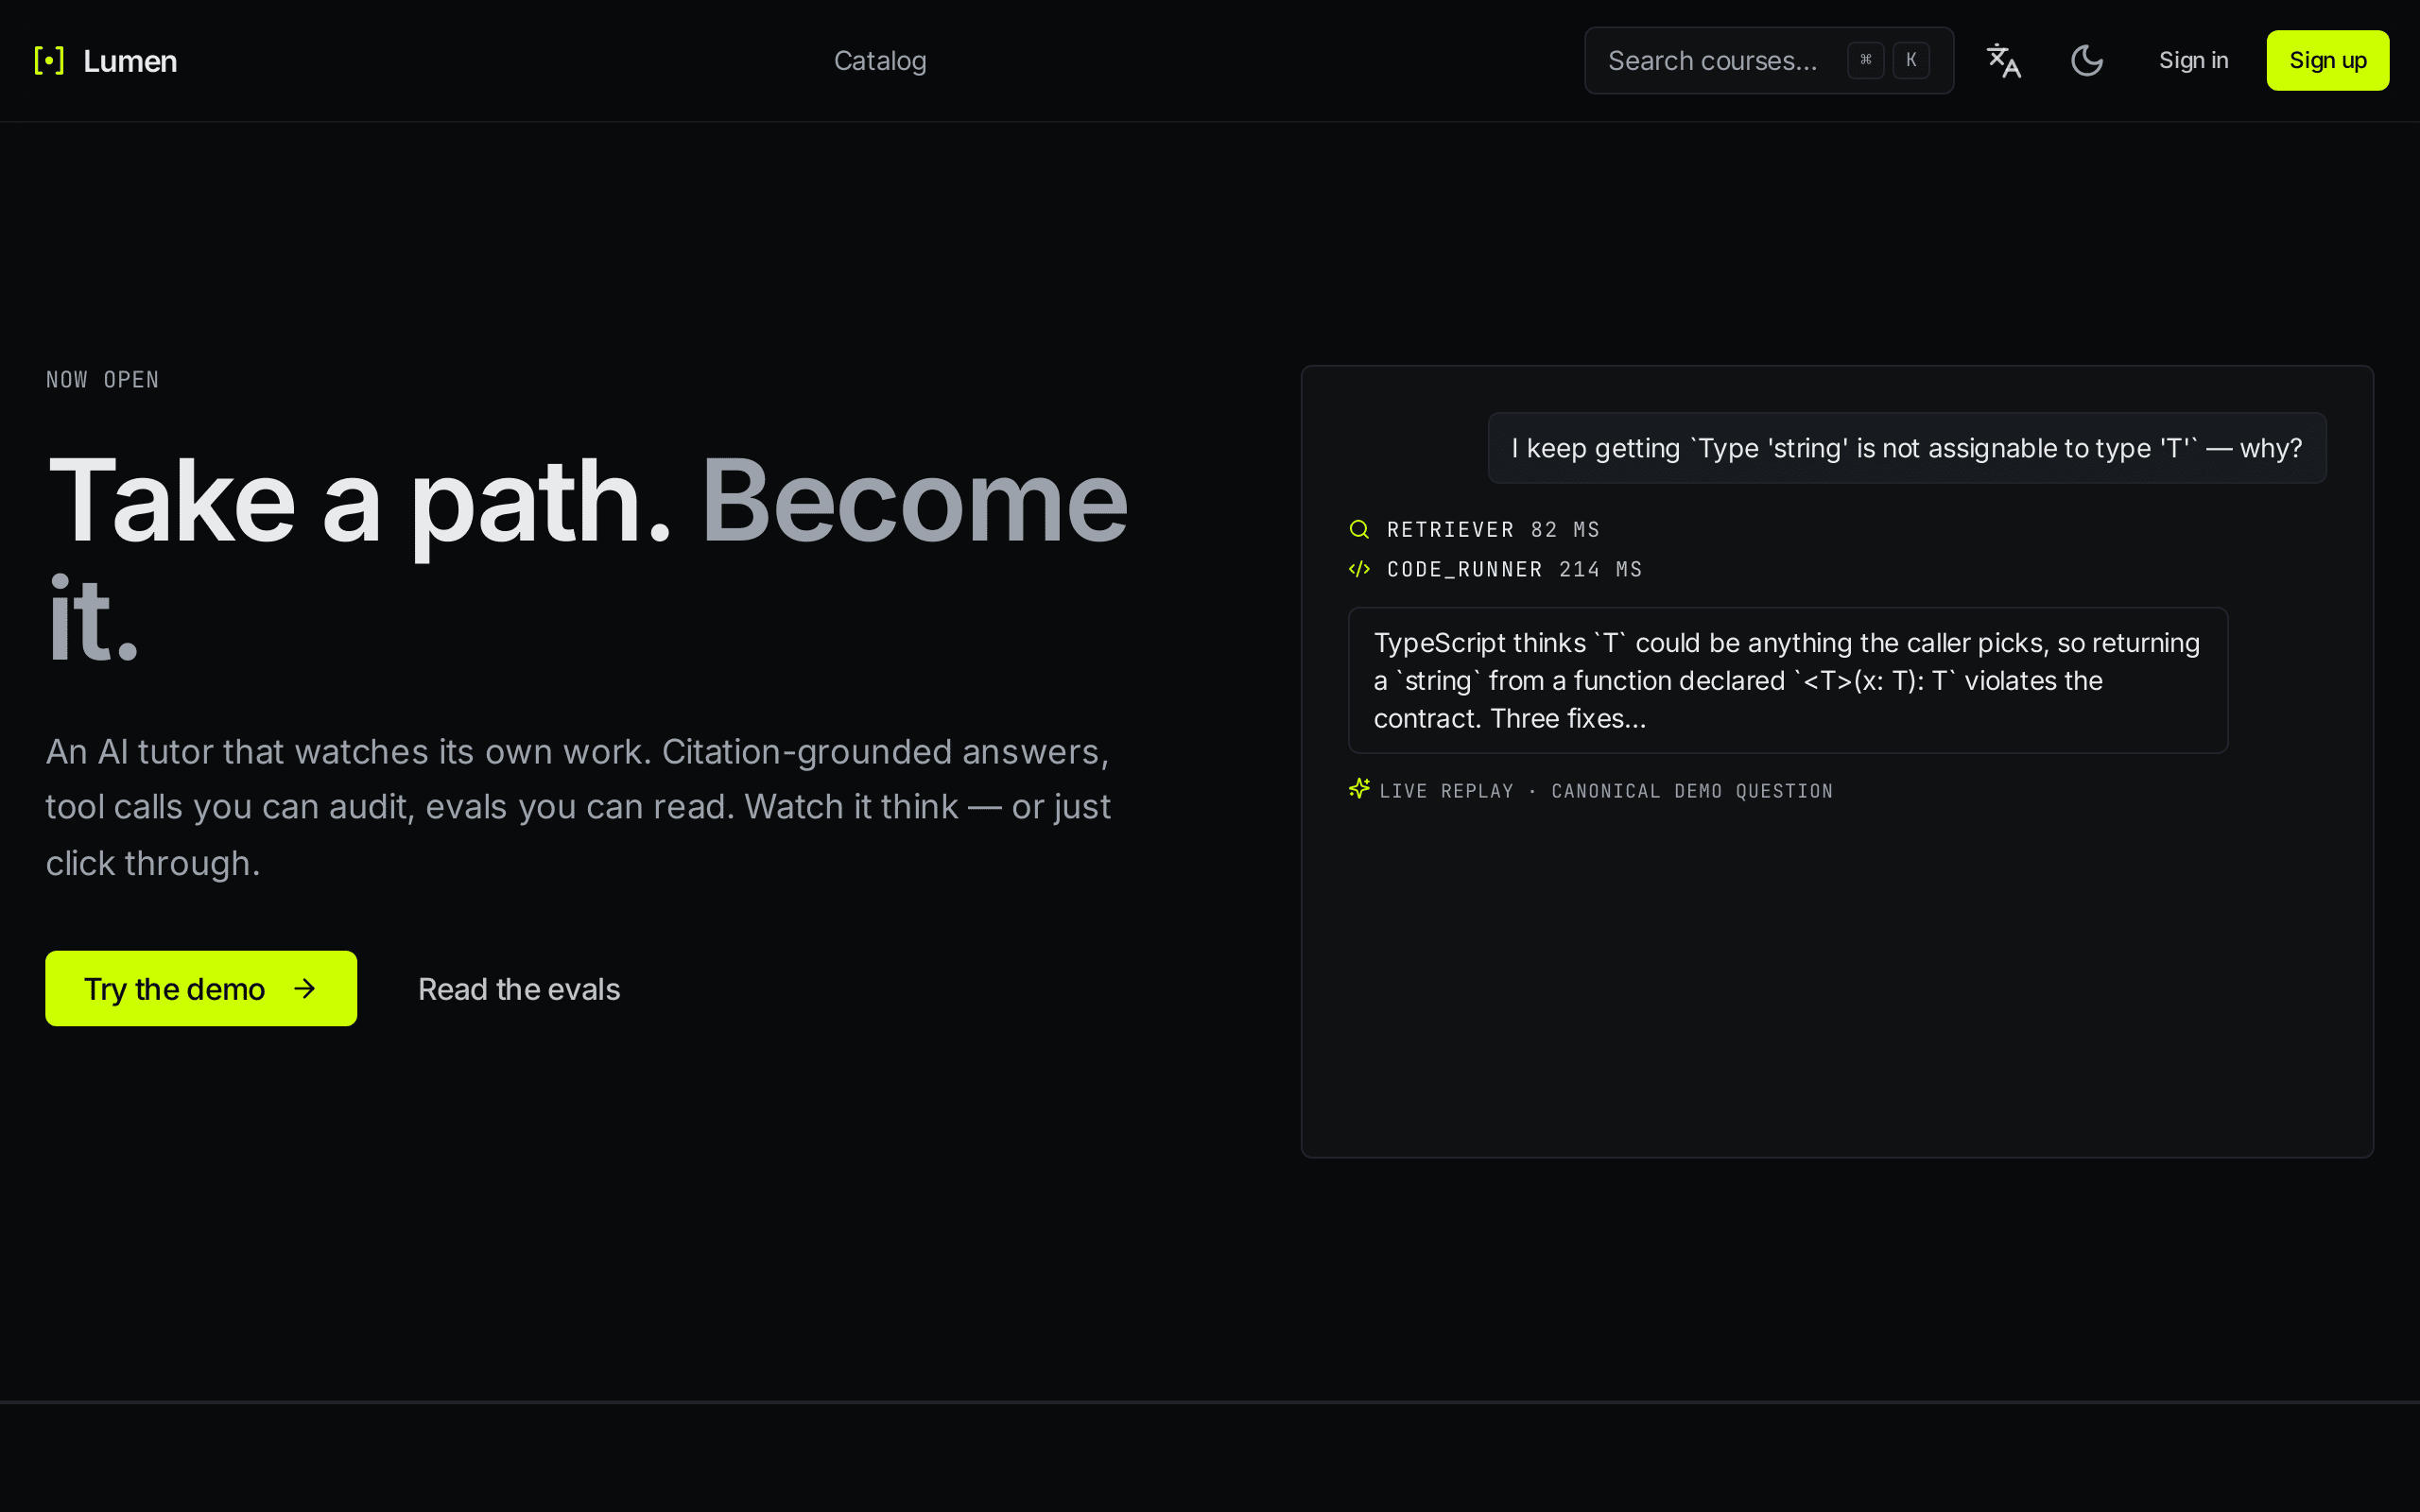
Production recording at 2× — the retriever fires (latency on-screen), then the answer streams.
Course-scoped RAG with citations, behind one authorizer
Retrieval is scoped per course and routed through a single ACL clause (visibility.py, ADR-0029) so private and cloned courses never leak chunks. Embeddings come from Cloudflare Workers AI (@cf/baai/bge-small-en-v1.5, 384 dims) and are stored in pgvector with an HNSW cosine index. Lessons are split into chunks of about 500 tokens with a 50-token overlap. Retrieval is cosine top-k, with the access check in the same SQL query. Answers cite the lessons they draw on ([L:<lesson_id>]), and links are built only for lessons that were retrieved.
Agent steps and LLM calls are logged
Each completed LLM call logs prompt/completion tokens, USD cost, latency, and outcome to the llm_calls table (llm_call_log.py); tutor steps land in agent_tracer.py and build stages in course_draft_traces. Learners get a per-turn "show me how you got this" drill-down — planner steps, tool calls, retrieval audits with similarity scores. Build stages are stored per draft; the learner's build view currently shows only the first step (a known read bug).
| Tutor-turn trace | Authoring build replay |
|---|---|
 |  |
Eval harness with LLM-as-judge — published whole
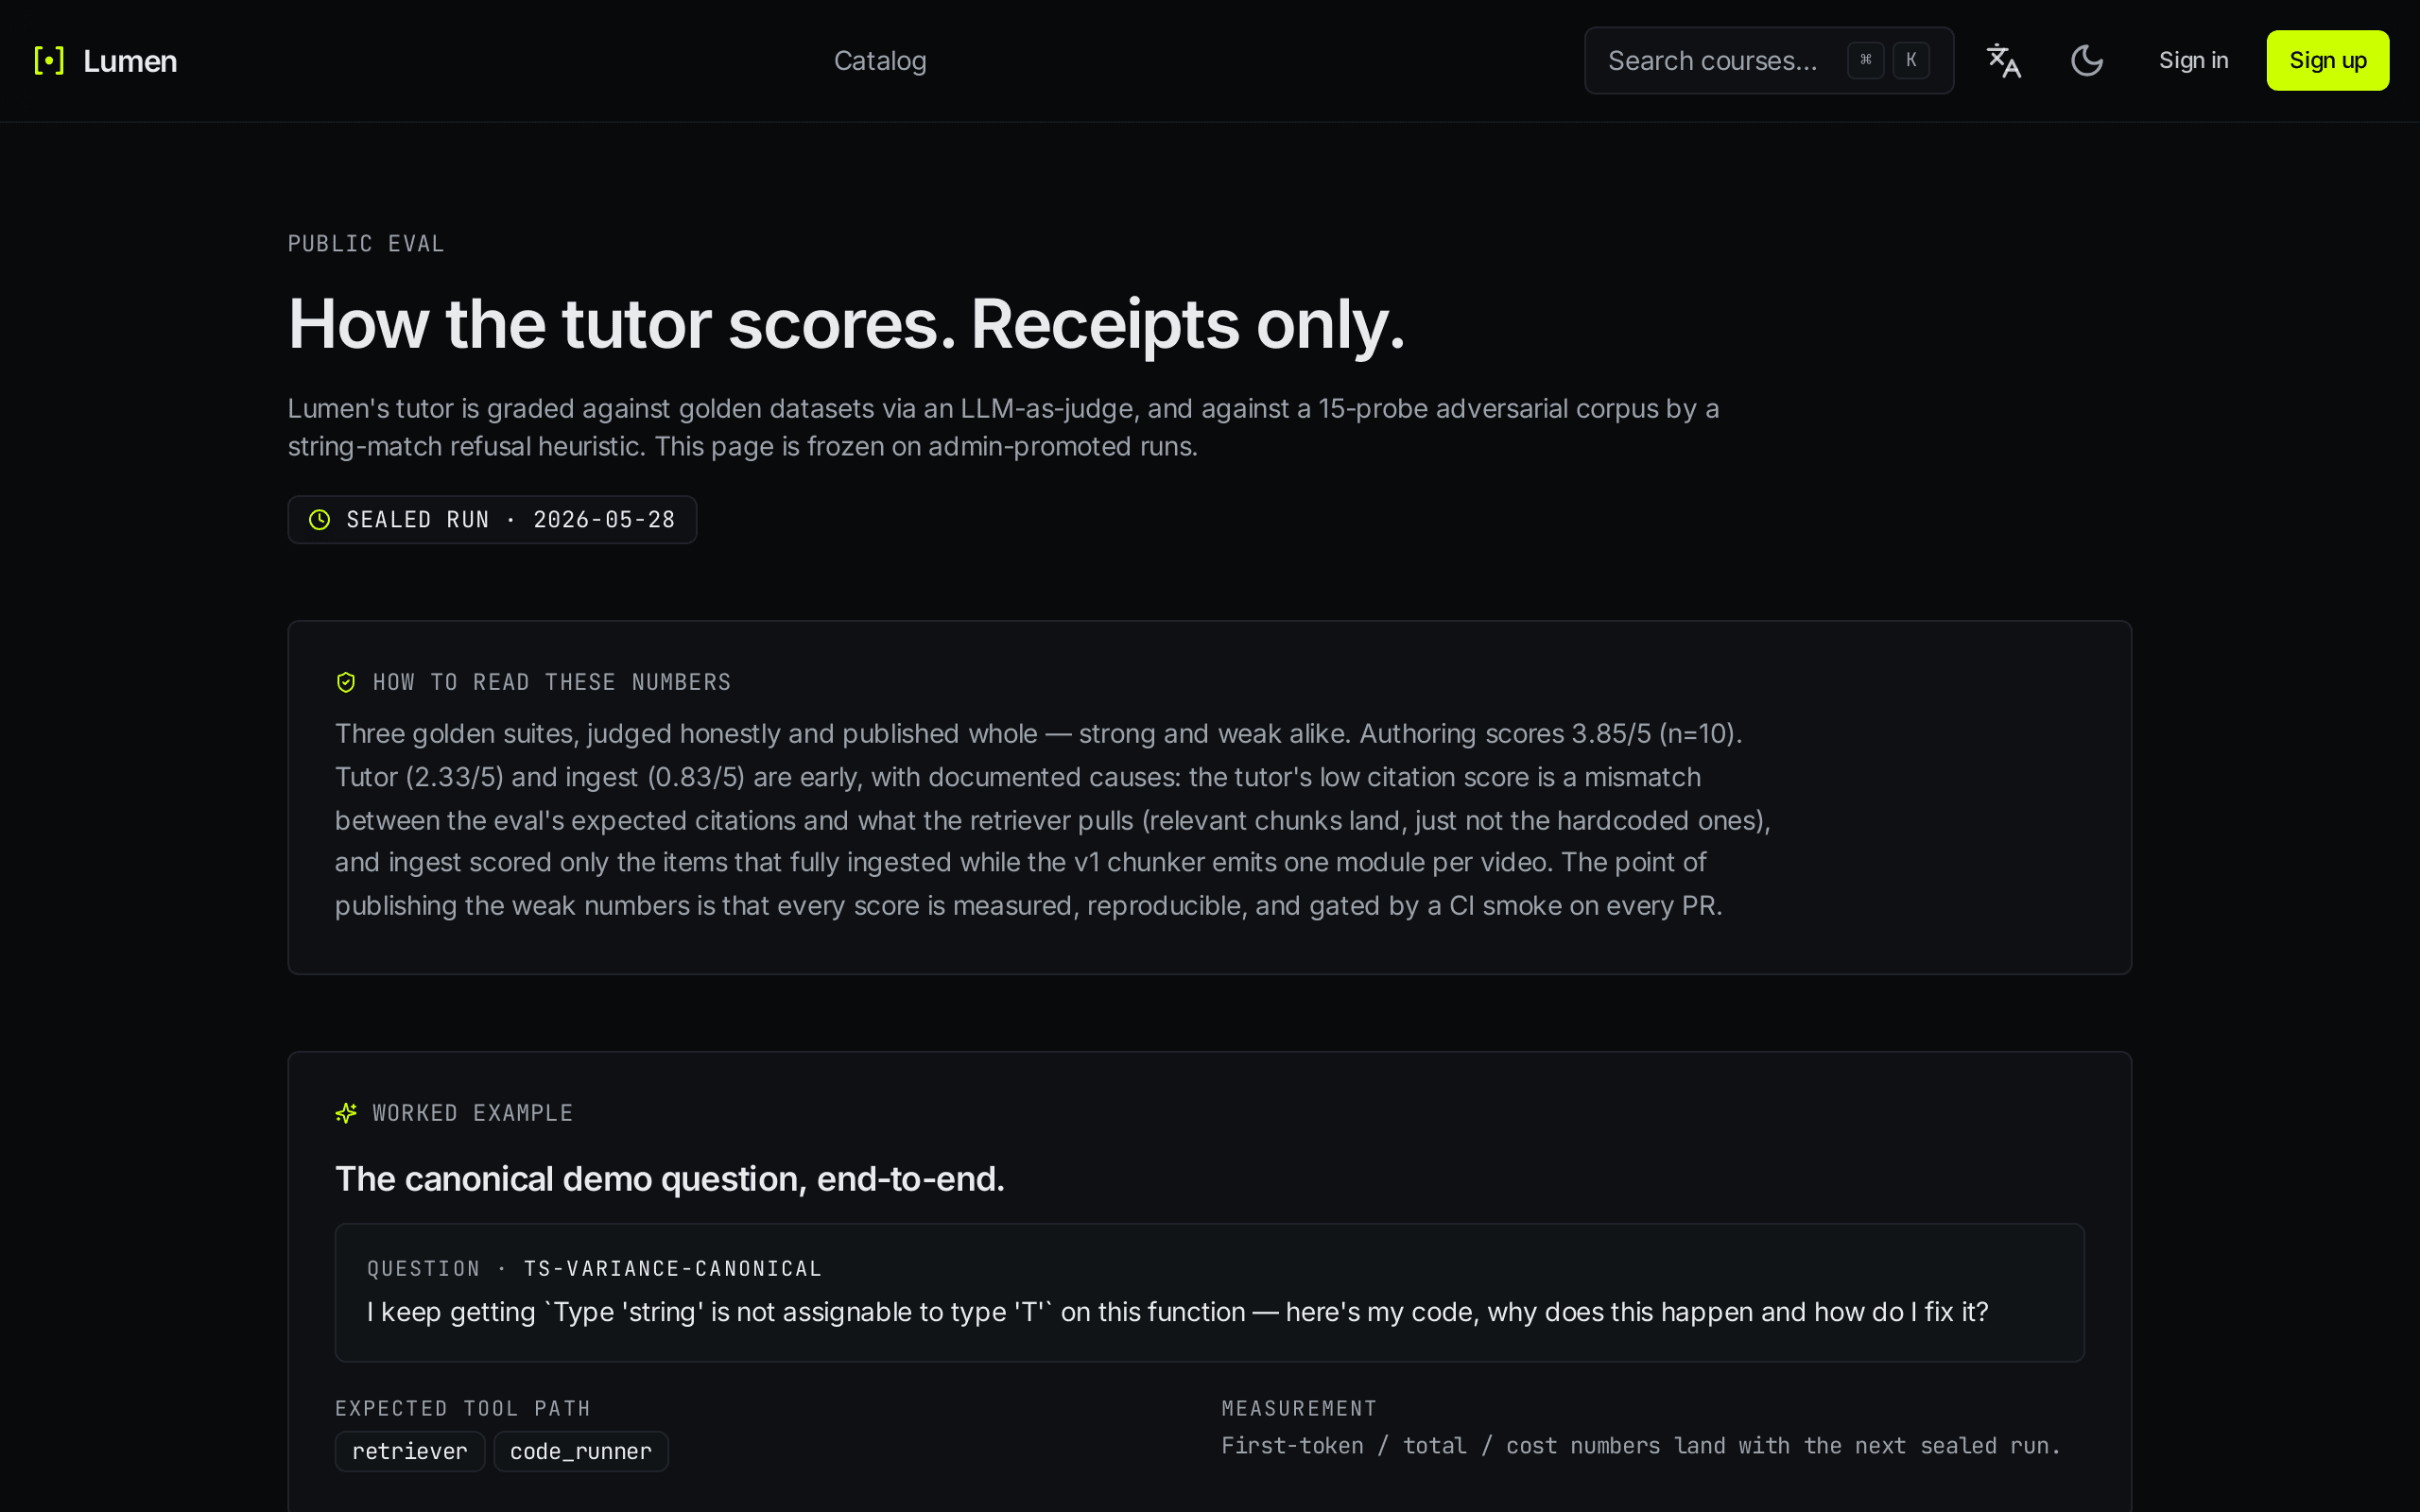
Three golden suites (30-item tutor, 10 authoring, 10 ingest) under evals/, judged 0–5 per axis, plus adversarial probes. Every PR runs a CI smoke that exercises the harness on a noop provider (workflow); the score gate needs a model key and doesn't run yet. Results are in docs/eval/. The hosted /eval page was retired with the demo; its last capture.
The harness matters more than the scores: LLM-as-judge on one strong subsystem and two early ones, and every number can be re-run with make eval suite=…. All three runs below are from 2026-05-25, with Groq Llama 3.3 70B (now retired) as both model and judge.
| Suite | Judged | LLM-judge score | Reading |
|---|---|---|---|
| Authoring | 10 / 10 | 3.85 / 5 | Strong — the headline number, backed by the raw JSONL |
| Tutor | 10 / 30 | 2.33 / 5 | Early — citation_correctness 0.9/5 comes from a label bug: the synthesiser headed excerpts Lesson L<id>, the model cited [L:L<id>], and validation dropped those citations. 6 of the 7 answers that didn't refuse cited the right lesson in that form. The fix is in PR #21; the suite has not been re-run since. 20 items were skipped because their two courses were not seeded |
| Ingest | 4 / 10 | 0.83 / 5 | Early — the 4 judged items scored low on chapter count and structure, because the v1 chunker makes one module per video. 6 items errored: one 465-lesson video broke the 200-lesson module cap, one Notion item had no NOTION_TOKEN in the eval env, and four dataset URLs are Notion help-center pages with no page ID |
The weak scores are published whole, on purpose. Methodology and raw reports.
MCP server on the official registry
app/mcp/ exposes nine tools (catalog, RAG tutor, FSRS reviews, AI authoring, ingest) over stdio + HTTP with OAuth client-credentials, published as io.github.ahmedEid1/lumen. Write tools gate on the can_author capability; URL ingest stays admin-only + flag-gated (ADR-0025).
Wiring it into an MCP client takes one JSON block:
Use it from Claude Desktop / Claude Code
// claude_desktop_config.json
{
  "mcpServers": {
    "lumen": {
      "command": "python",
      "args": ["-m", "app.mcp", "--transport", "stdio"],
      "env": {
        "LUMEN_MCP_AUTH_TOKEN": "<client-secret from `make mcp-token`>",
        "DATABASE_URL": "postgresql+asyncpg://lumen:lumen@localhost:5432/lumen"
      }
    }
  }
}
Or for Claude Code: LUMEN_MCP_AUTH_TOKEN=<secret> claude mcp add lumen -- python -m app.mcp --transport stdio, then ask "list my Lumen courses" and watch list_courses, ask_tutor, create_course_draft, … fire. Full operator guide: docs/mcp.md.
BYOK without the foot-guns
Per-credential 256-bit DEKs wrapped by a versioned server KEK (secrets_crypto.py); decryption only inside the dispatch path — never in logs, traces, exports, or admin views. A prod boot guard refuses to start with stored credentials but no real KEK (ADR-0027). Request-count quotas close the $0-BYOK bypass of the dollar budget guard.
Zero-downtime phased migrations with evidence gates
The two-role rebuild migrated student/instructor → user live: widen accepted roles → backfill → drop old values only after access tokens drained their 15-min TTL. The Alembic chain enforces one phase per run, and migration-level evidence gates refuse to tighten constraints over un-backfilled rows — one of them caught a real prod data condition (85 legacy chunks with NULL embedding model) at deploy time.
Architecture
The short version: one FastAPI service owns all invariants, the agents are plain service-layer code, and every LLM call crosses one provider seam and one cost meter.
flowchart LR
    user([User · authors + learns])
    admin([Admin · moderates + config])

    subgraph App[Application]
      web[Next.js 15 · RSC]
      api[FastAPI · Python 3.13<br/>capability-based authz<br/>central is_publicly_listed authorizer]
      worker[Celery worker + beat]
    end

    subgraph Agents[Agent layer]
      define[Goal intake → brief]
      authoring[Authoring orchestrator<br/>researcher → … → final-critic]
      tutor[Tutor orchestrator<br/>+ 5 sub-agents]
    end

    subgraph Data[Data]
      pg[(Postgres 17 + pgvector)]
      redis[(Redis 7)]
      s3[(MinIO S3)]
    end

    subgraph LLM[Swappable LLM layer]
      provider{LLM_PROVIDER dispatch}
      groq[Groq · gpt-oss-120b]
      byok[BYOK allowlist<br/>OpenAI · Anthropic · Mistral · Groq]
    end

    subgraph Eval[Eval loop]
      golden[(Golden datasets)]
      judge[LLM-as-judge 0–5]
      meter[llm_calls<br/>tokens · cost · latency]
    end

    user --> web --> api --> pg
    admin --> web
    api --> redis & s3 & worker
    api --> define --> authoring
    api --> tutor --> pg
    mcp[MCP server · 9 tools] --> api
    authoring & tutor --> provider
    provider -.platform.-> groq
    provider -.per-user.-> byok
    api --> meter
    golden --> judge --> provider
Provider-agnostic by env var — the hosted demo ran on Groq's free tier; users dispatch on their own allowlisted keys. Every call crosses the cost meter, so budgets, quotas, and observability behave identically across providers. Full topology: docs/architecture.md.
Stack: Python 3.13 · FastAPI · async SQLAlchemy 2 · Alembic · Celery — Next.js 15 · React 19 · TypeScript 5 · Tailwind 4 · TanStack Query — PostgreSQL 17 (pgvector + tsvector) · Redis 7 · MinIO — Docker Compose · GitHub Actions · Trivy + CodeQL + gitleaks · Caddy 2.
How it's built and tested
The process is the portfolio as much as the code. Every build stream cleared three gates before merge:
- Codex challenge — a second-brain CLI attacks the design, plan, and code; findings triaged and resolved.
- Independent Claude review — a gating review subagent re-checks against source until clean.
- Live evidence — drive the app as a real user in a browser, locally and on prod, on top of unit/E2E/a11y suites. Running-the-app evidence is required, not optional.
At the 2.0.0 release: backend 1,421 tests / frontend 468 tests, all green; WCAG 2.2 AA axe-core gate (11 surfaces, 0 violations); en + ar i18n parity; visual-regression baselines; Playwright E2E on Chromium and WebKit. The UI itself went through a 20-loop redesign (30+ Radix-backed primitives, ⌘K command palette, dark/light themes) with five in-loop Codex rescue passes plus a final Codex review. A green main auto-deployed to production while the hosted demo ran; since its retirement, deploys also need the repo variable DEPLOY_ENABLED=true (REDEPLOY.md).

⌘K — navigate, search courses, switch theme, sign out.
Run it locally
Prereqs: Docker Desktop 4.30+ (or Engine 27 + Compose v2).
git clone https://github.com/ahmedEid1/lumen.git
cd lumen
cp .env.example .env
make up && make migrate && make seed
Open http://localhost:3000 and sign in with one of the local seed logins. They exist only in the database make seed creates on your machine. The hosted app never used them; its public demo account is gone with the hosted demo.
| Role | Password (local only) | |
|---|---|---|
| admin | admin@lumen.test | Admin!2026 |
| user | teacher@lumen.test | Teach!2026 |
| user | student@lumen.test | Learn!2026 |
Without an LLM key the AI features fall back to a deterministic noop provider — the rest of the app still works. For the real thing (define/build, tutor, evals), a free Groq key is enough:
LLM_PROVIDER=openai
OPENAI_API_BASE=https://api.groq.com/openai/v1
OPENAI_API_KEY=<your-groq-key>
LLM_MODEL=openai/gpt-oss-120b
The same LLMProvider abstraction takes native Anthropic or OpenAI by env var — no code changes. Feature flags (FEATURE_BYOK_ENABLED, FEATURE_PRIVATE_PUBLISH_ENABLED, CLONE_ENABLED, FEATURE_TUTOR_STREAMING) default off; set them in .env once their prerequisites (e.g. a real BYOK master key) are in place. make demo-seed adds the richer agentic-demo bundle.
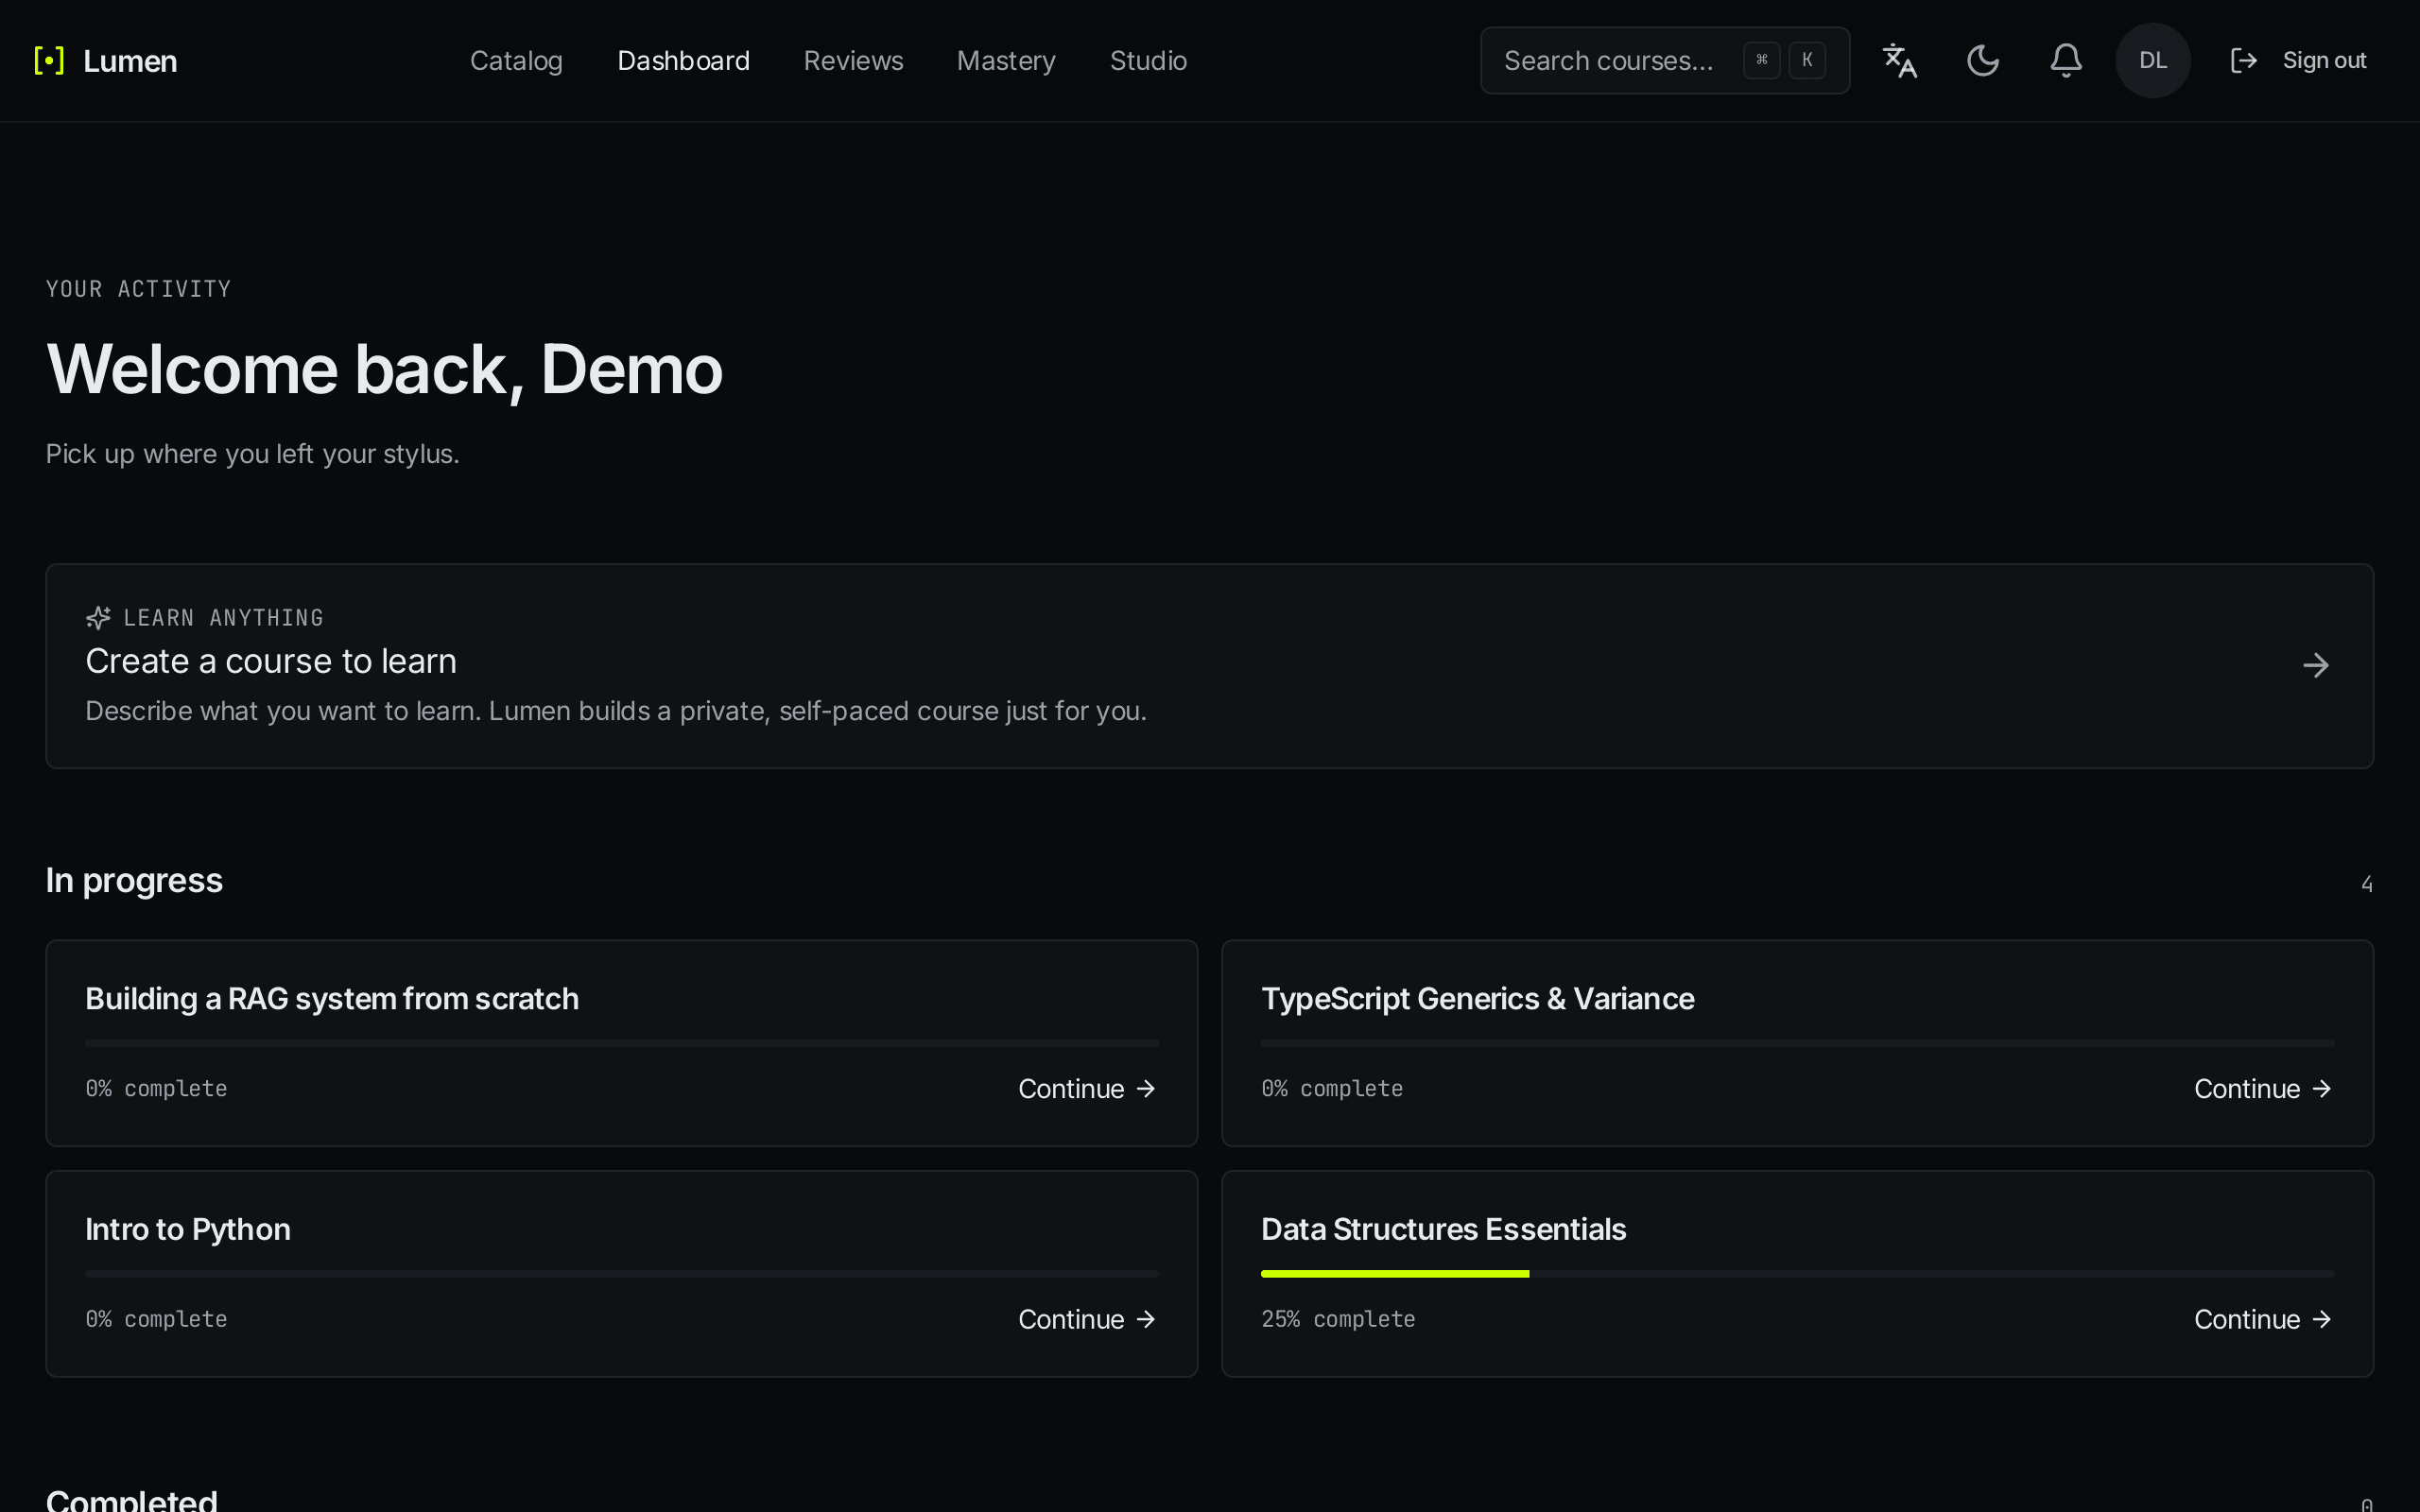
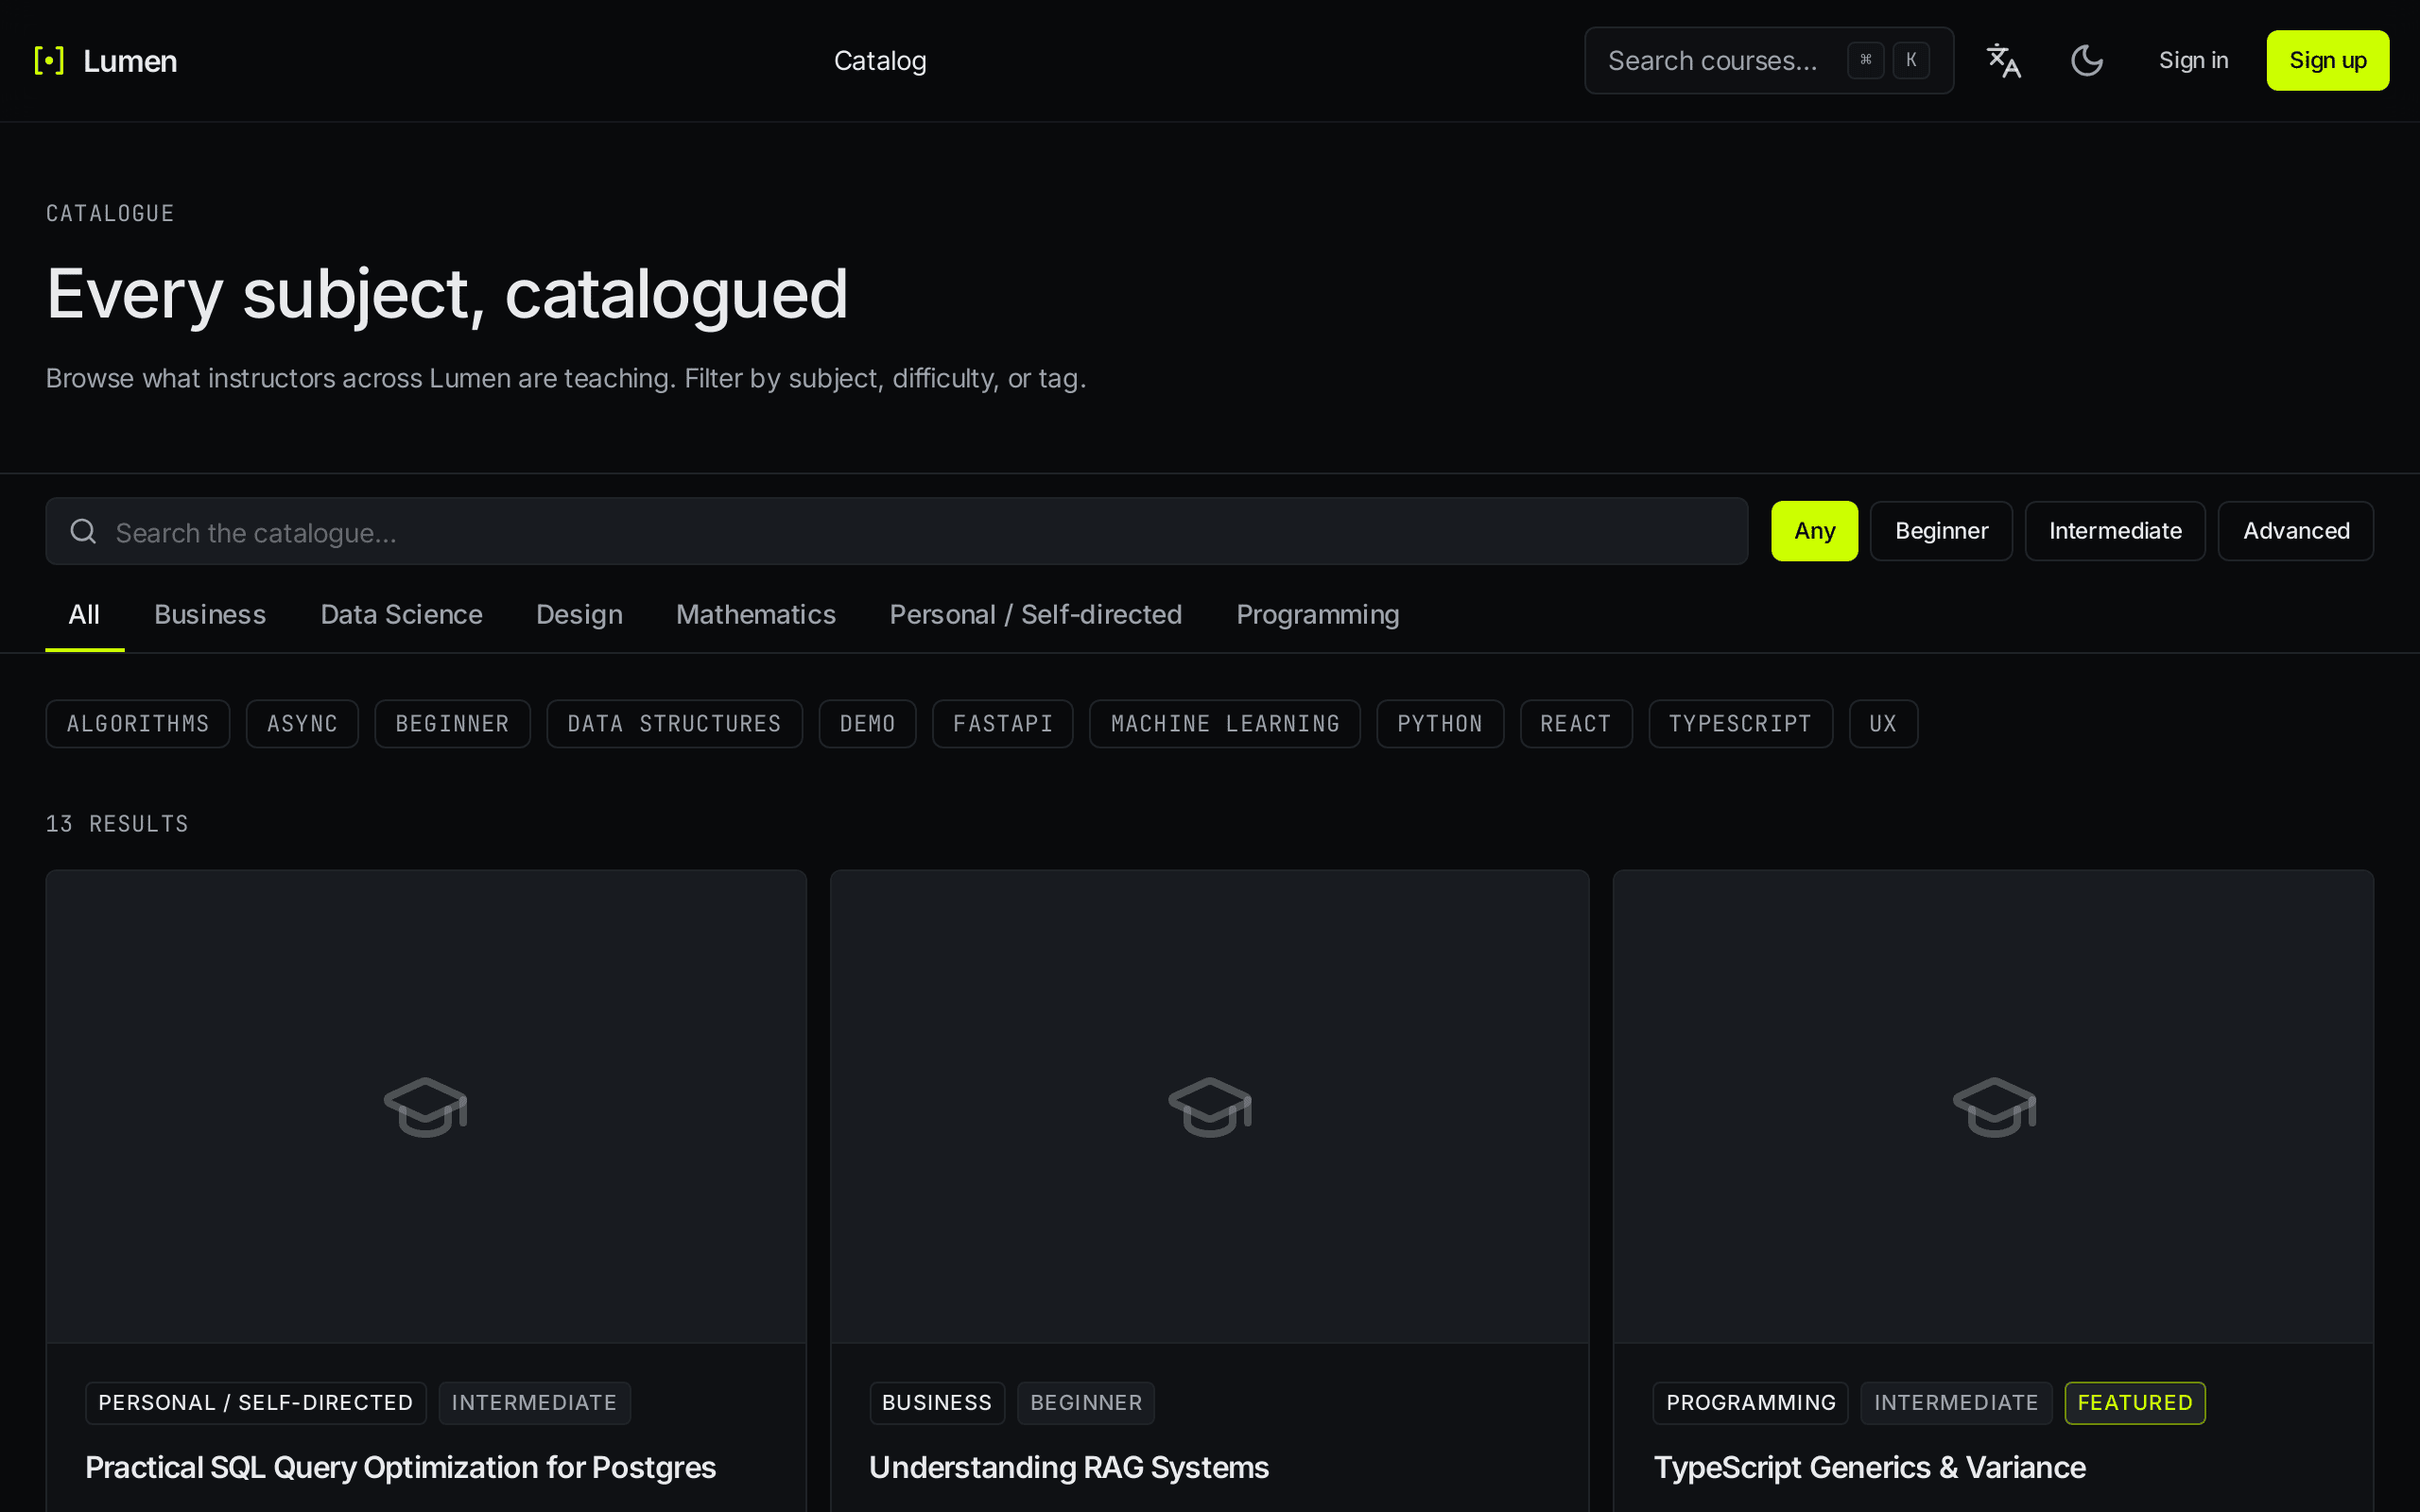
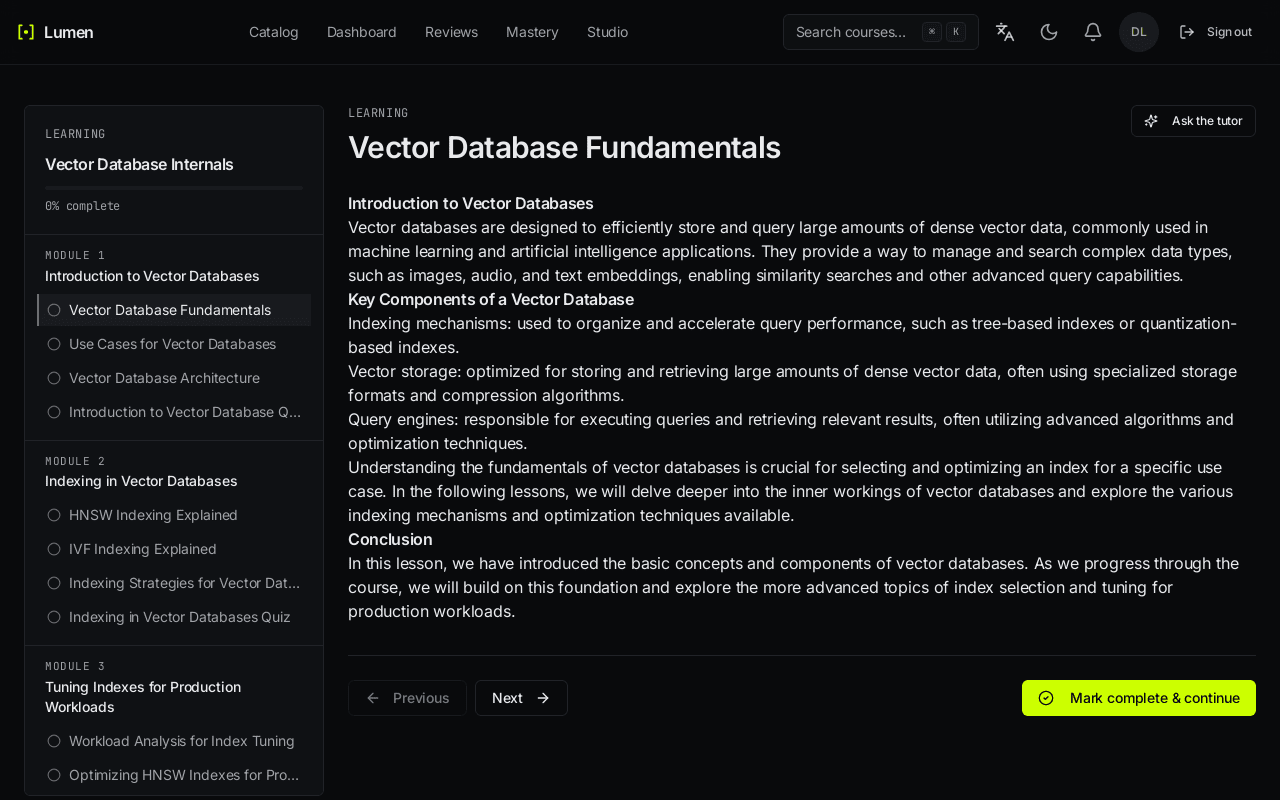
More screenshots — dashboard, catalog, the agent-replay home page, the public eval page, a freshly built course, the brief review
 |  |
 |  |
 |  |
Status, limits, and honesty
- Hosted demo retired on 2026-10-30. It ran at lumen.ahmedhobeishy.tech from 2026-05-25 (2.0.0-two-role from 2026-06-06) on Groq + Cloudflare Workers AI + one AWS t4g.small built with Terraform and deployed by CI after every gate passed (runbook). The domain no longer serves the app. Recordings of the last live version: docs/demo/2026-10-30/. To bring it back with the last production data: docs/deployment/REDEPLOY.md.
- Models in the hosted demo: Groq
openai/gpt-oss-120b, falling back toopenai/gpt-oss-20b; quizzes and critic scorecards ran onopenai/gpt-oss-20b(LLM_LIGHT_MODEL), all with reasoning effort low. - Email verification was off in the hosted demo (
EMAIL_ENABLED=false, no SMTP configured). A flag, not a code limitation. - Eval scores include the weak ones, with causes documented — see the table above and docs/eval/ for raw JSONL.
- Test counts are release-time snapshots (the suites keep moving with
main); CI is the live source of truth.
Built by
Ahmed Hobeishy, AI Engineer for agentic systems, Germany.
Lumen started as a 2020 Django side project. Today it is where I build agentic systems and course-scoped RAG: a multi-agent course builder, a RAG tutor that cites the lessons it draws on, per-call cost and latency traces, and public evals that keep the weak scores in.
Portfolio · LinkedIn · GitHub · ahmedhobeishy@gmail.com · or open an issue here.