
Pitroom
Hands bounded coding work to cheaper worker agents: verified answers, exact diffs, cost receipts.
Runs on your machine from its package; the steps are below.
What it does
- Reads
- Writes
- High impact
At most: moves money, runs code or commands, deletes data, or sends messages for you.
What it costs
FreeOdel charges nothing per call. The publisher may charge for its own service.
Runs locally over stdio
This server isn't hosted — your MCP client launches it from a package registry. Use one of the commands below, or drop the config into your client (e.g. Claude Desktop).
Run
npx -y pitroom
MCP client config
{
  "mcpServers": {
    "pitroom": {
      "command": "npx",
      "args": [
        "-y",
        "pitroom"
      ]
    }
  }
}Pitroom
A free pit crew for your expensive coding agent
Cheaper and faster: hand the reading, fixes, tests and reviews to workers that run in parallel. Keep the decisions.
Model-agnostic · Verified answers · Receipts, not vibes · OpenCode / Codex / Claude Code / Gemini CLI / Qwen Code / Kilo Code workers


Quick start · Dashboard · Benchmarks · Workflow · Skills · Commands · Workers · Responsibility · Write an adapter
Your agent decides · Cheap workers do the typing · A second model reviews
pitroom dash, with sample data
Why Pitroom?
Claude Code, Codex and friends spend premium tokens reading: grepping, opening files, scanning code they'll never quote.
Pitroom goes one step further:
Your agent stays in the driver's seat. A pit crew of cheap workers does the legwork in parallel, while your agent keeps going, and hands back only the answer, the exact diff and a receipt.
Your model, not oursNo model is hardcoded. Pitroom uses your worker CLI's default model: a free tier, a local MLX/Ollama model or a cheap paid one. Switch there and Pitroom follows. |
Any worker CLIOpenCode, Codex CLI, Claude Code, Gemini CLI, Qwen Code and Kilo Code. One group can mix them, and a fallback chain can cross them (how adapters work). |
Verified answersEvery Your agent trusts what checks out and skips re-reading it. |
Safe by constructionNo commit, push, reset or bulk delete. A git guard stops the tricks. In isolate mode nothing reaches your tree until you apply it. |
And more
12 more features
- Receipts, not vibes. Tokens the worker burned, tokens returned to your agent, compression ratio, and an estimate of what your primary model would have charged.
pitroom savings --card card.svgmakes a shareable card. - Self-healing worker chain. Free models get rate-limited or retired. List fallback workers once (
fallback) and a run that hits "model not found", 429 or quota errors moves to the next model automatically. Still no model hardcoded: the chain is yours. - A crew, not just one worker.
pitroom crewstarts several workers at once,pitroom watch --jsonstreams one line per change so your agent follows them live,pitroom wait -gcollects every answer,pitroom apply -glands isolated patches in order. Up to 20 workers run at once by default (maxParallel, 30 at most), the rest queue, and the fallback chain absorbs free-tier rate limits; parallel writers are refused. - Faster, not only cheaper. Workers run in the background and side by side (up to 20 at once) while your agent keeps working, so slow reading and review stop blocking it. In the benchmark, 470 s of worker time finished in 156 s of wall clock, about 3× faster than one question after another, and your agent's own context stayed small.
- Free first, dearer only when needed. Runs and plan tasks start on the
cheaptier, OpenCode's free model;standard(Codex) andcapable(Claude Code) are for tasks that need them, and an optionalreviewtier names who reviews. Gemini CLI with a free Google AI Studio key is one more cheap worker (small daily quota per model).pitroom modelsshows what each worker offers, the effort levels (low…xhigh) each model accepts, what you say it costs (costs) and what it used;--effortsets the level per run. Details: Models, costs and effort. - Exact changes, even in a dirty tree. Pitroom snapshots the working tree with a throwaway git index (your index, branches and stash are never touched), so it reports only the worker's edits and can undo exactly those:
pitroom revert <id>. - Your agent sets the permissions. It creates each worker with the permissions the task and your session allow (read-only, isolated copy, in-place edits, web), and a worker never widens its own. A fixed floor stays for every run: no git history changes, no
sudo, no publishing, no secrets. A worker cannot land a deletion either:pitroom applyrefuses a patch that deletes files unless your agent passes--allow-delete. - Real isolation.
--isolateruns the worker in a private copy of your current state (its own repository, sharing your objects read-only), uncommitted and untracked files included, then hands you a patch:pitroom apply <id>(checked, refuses on conflict) orpitroom discard <id>. - Zero repo pollution. No
.pitroom/folder, no.gitignoreedits, no branches. Records live in~/.local/state/pitroom. - Works with any agent. Fourteen Agent Skills: the superpowers development workflow run by workers, plus delegation (
using-pitroom,pitroom-research,-crew,-implement), a CLI, and a Claude Code / Codex plugin whose session-start hook loads the workflow. Claude Code, Codex, Gemini CLI, Cursor, or anything that can run a shell command. - A live dashboard and a searchable history.
pitroom dashopens a local page of every run (the task, what the worker did step by step, its result and diff) with history and statistics, for the agent apps that show neither hooks nor a status line;pitroom historysearches everything Pitroom ever ran. See Dashboard. - Small. About 6,500 lines of TypeScript in the CLI, a ~210 KB CLI bundle (plus the ~1.9 MB of dashboard files it serves, with syntax highlighting for ten languages), zero runtime dependencies.
How it stays safe
Each run gets the worker's own safety mechanism set to the mode (for OpenCode, a permission profile injected through OPENCODE_CONFIG_CONTENT): no commit/push/reset/checkout/stash/clean/rebase, no bulk deletes, no sudo, a file-reading tool that refuses .env and key files (OpenCode and Claude Code workers), no web tools unless you pass --web, no subagents, no recursive delegation. Only allow/deny rules, so a headless run never stalls on a prompt. A git guard on the worker's PATH also stops sh -c "git push", env git reset, aliases and scripts from committing, pushing, resetting, stashing or touching your index. Your opencode.json is never touched. These safeguards reduce risk; they are not a security boundary (see Responsibility and SECURITY.md).
See it work
A real run on a free OpenCode Zen model: your agent reads ~554 tokens instead of 163,000.
$ pitroom run "Which function builds the read-only permission profile, and which bash commands does it allow?"
pitroom ✔ done · read · 30s · run 20260930-003902-3270
session ses_… · model opencode/muse-spark-1.3-contributor-free

SUMMARY: The read-only permission profile is built by `readProfile()` in src/profiles.ts:89.
Its bash allow-list is `READ_ONLY_BASH` in src/profiles.ts:29-46.
DETAILS:
- Allowed (src/profiles.ts:31-41): `git status*`:31, `git diff*`:32, … `rg *`:40, `wc *`:41.
- Explicit sub-denies: `rg *--pre*`:43, `git *--output*`:44, `git *--ext-diff*`:45.
FILES CHANGED: none

── receipt: worker processed 163k tokens in 6 steps (7 tool calls) · worker cost $0.000
   · returned ~554 tokens, 294× compression · est. saved $0.152 vs Claude Sonnet
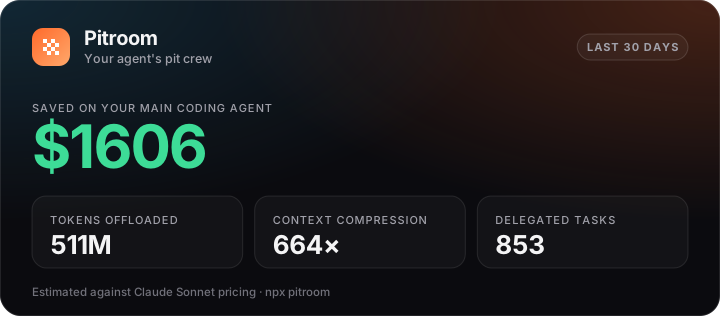
Every run prints a receipt, and pitroom savings adds them up (--card writes this shareable card; the numbers here are sample data, and a real measurement follows in Benchmarks):
Dashboard
pitroom dash --detach prints the address of a live page on 127.0.0.1 (this machine only; it reads your runs and changes nothing but the two actions below). It is for the places where hook messages and status lines do not reach, such as the Claude Code and Codex apps: open it in a browser or in the app's own browser pane. The skills tell your agent to start it and give you the address when it runs workers in the background.
The screenshots below show sample data (an imaginary shop-api project), not a real one.
Live. What is running now, and the latest runs. Running cards show a timer, the worker's last words and its animated pixel mascot (a finished card shows the worker's logo); finished ones show the result and, for reviews, the findings.
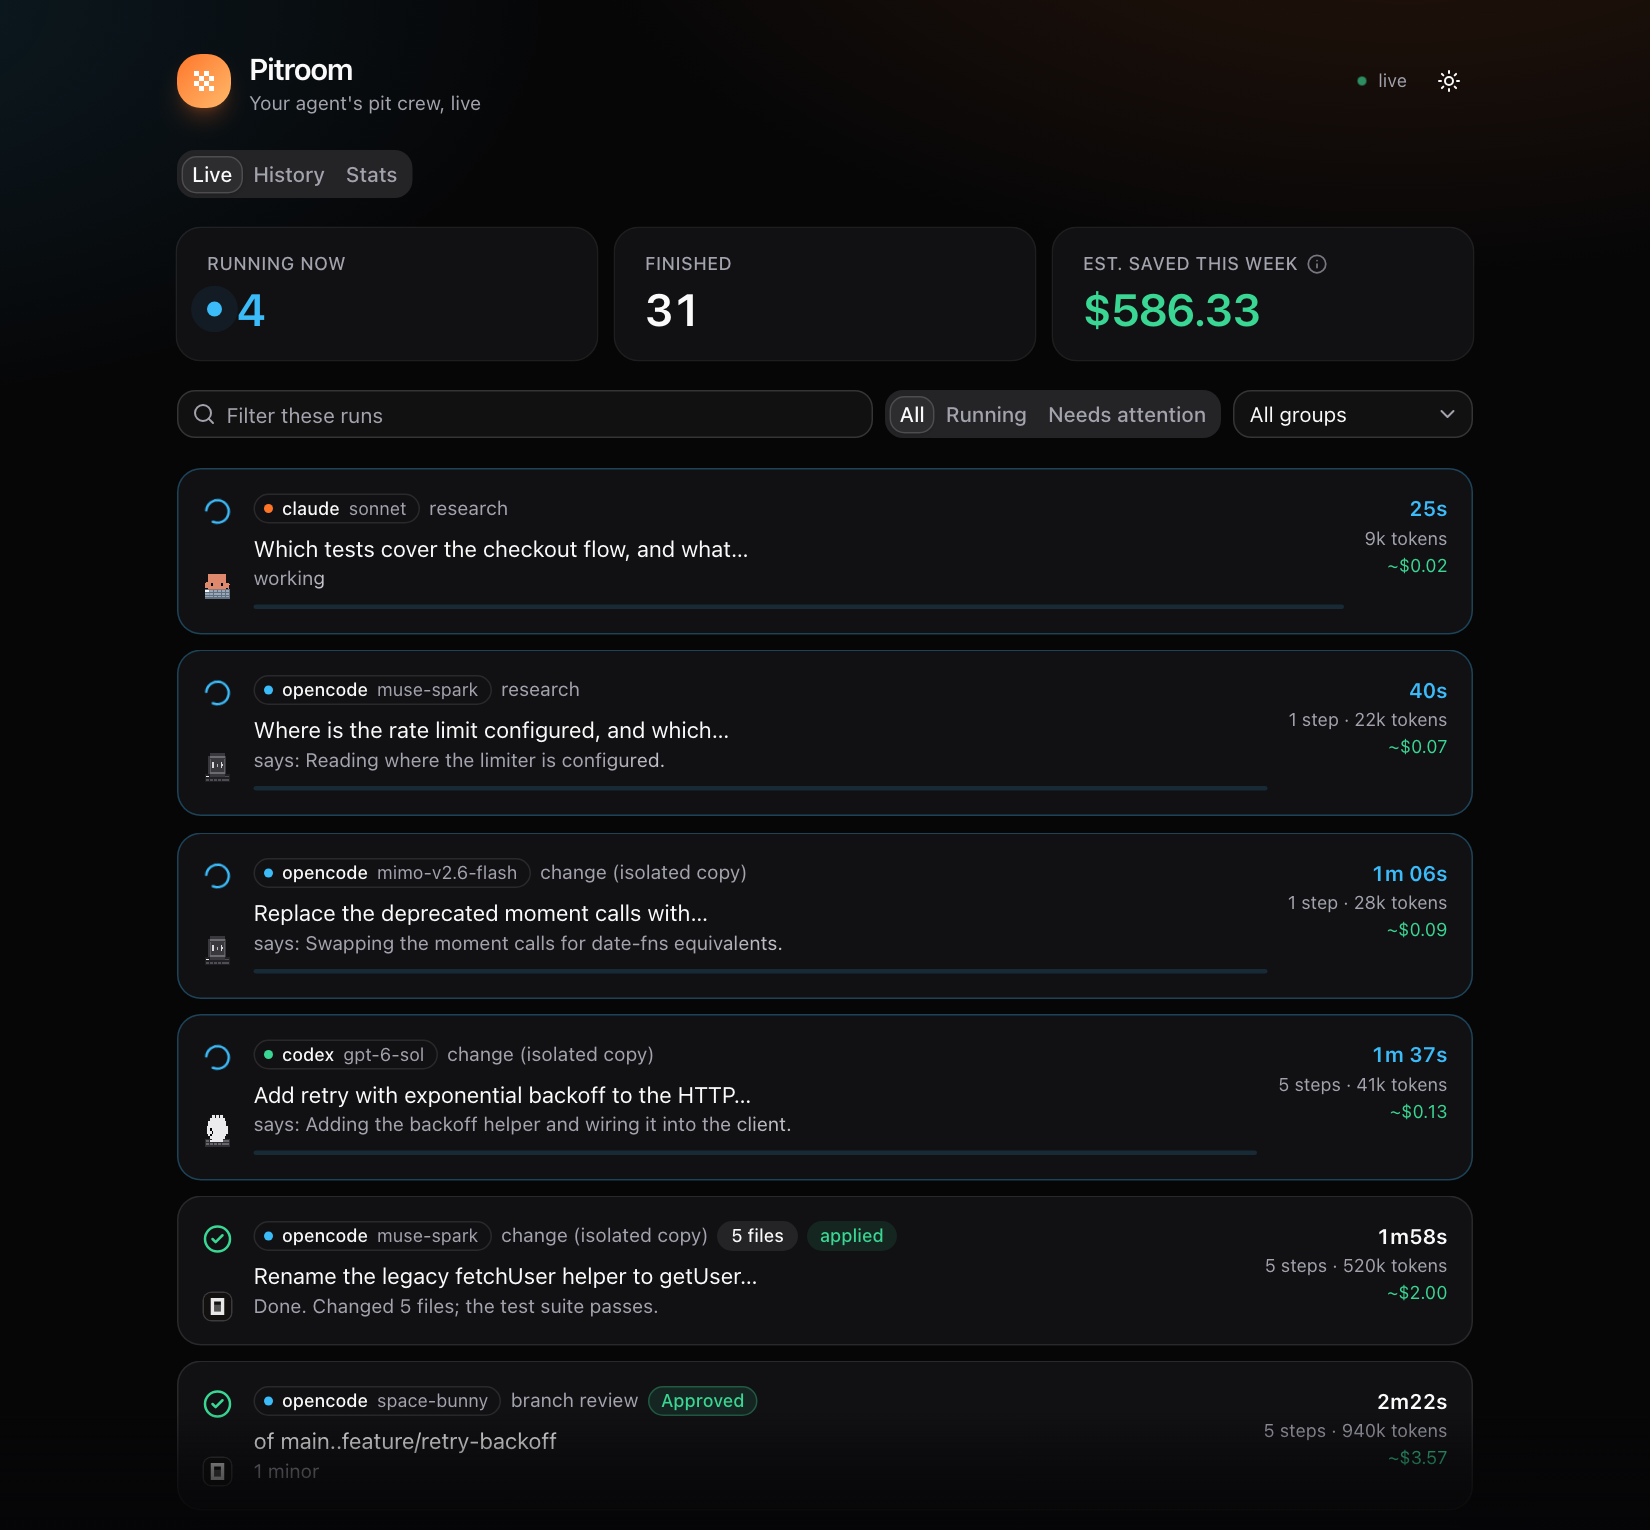
Cards, audits, history, Stats, and Stop/Discard
Click a card and it grows into a panel with the task, what the worker did step by step (files read, searches, commands, edits, with times, failed ones marked), its result, the files and diff it changed, and the details (model, tokens, cost, fallbacks, reference check).
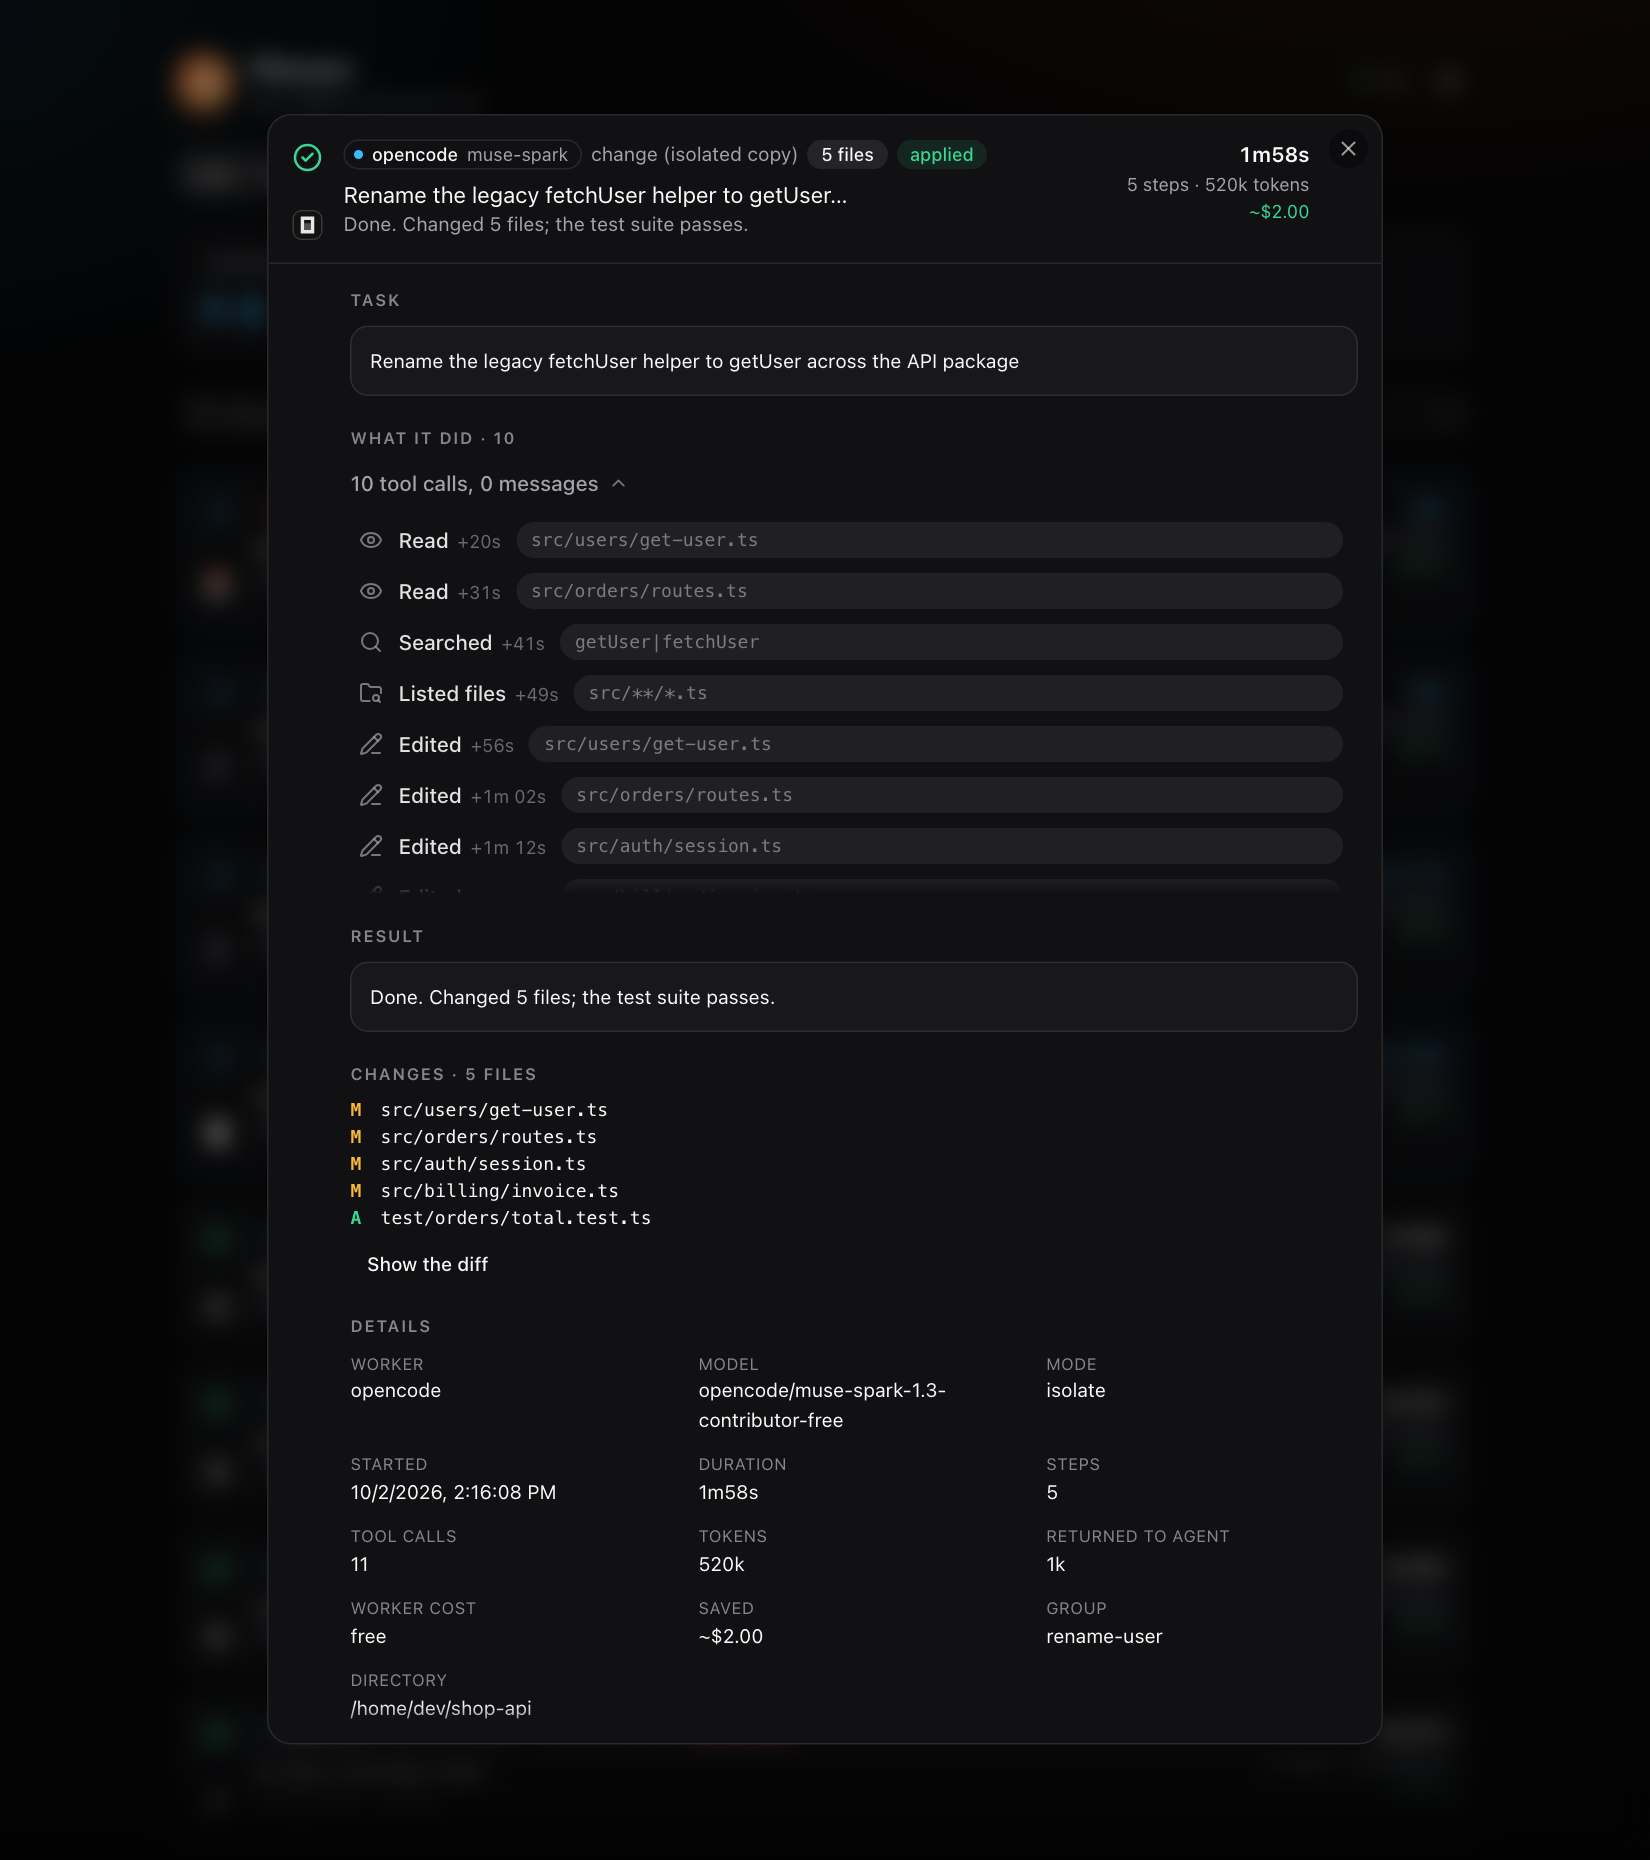
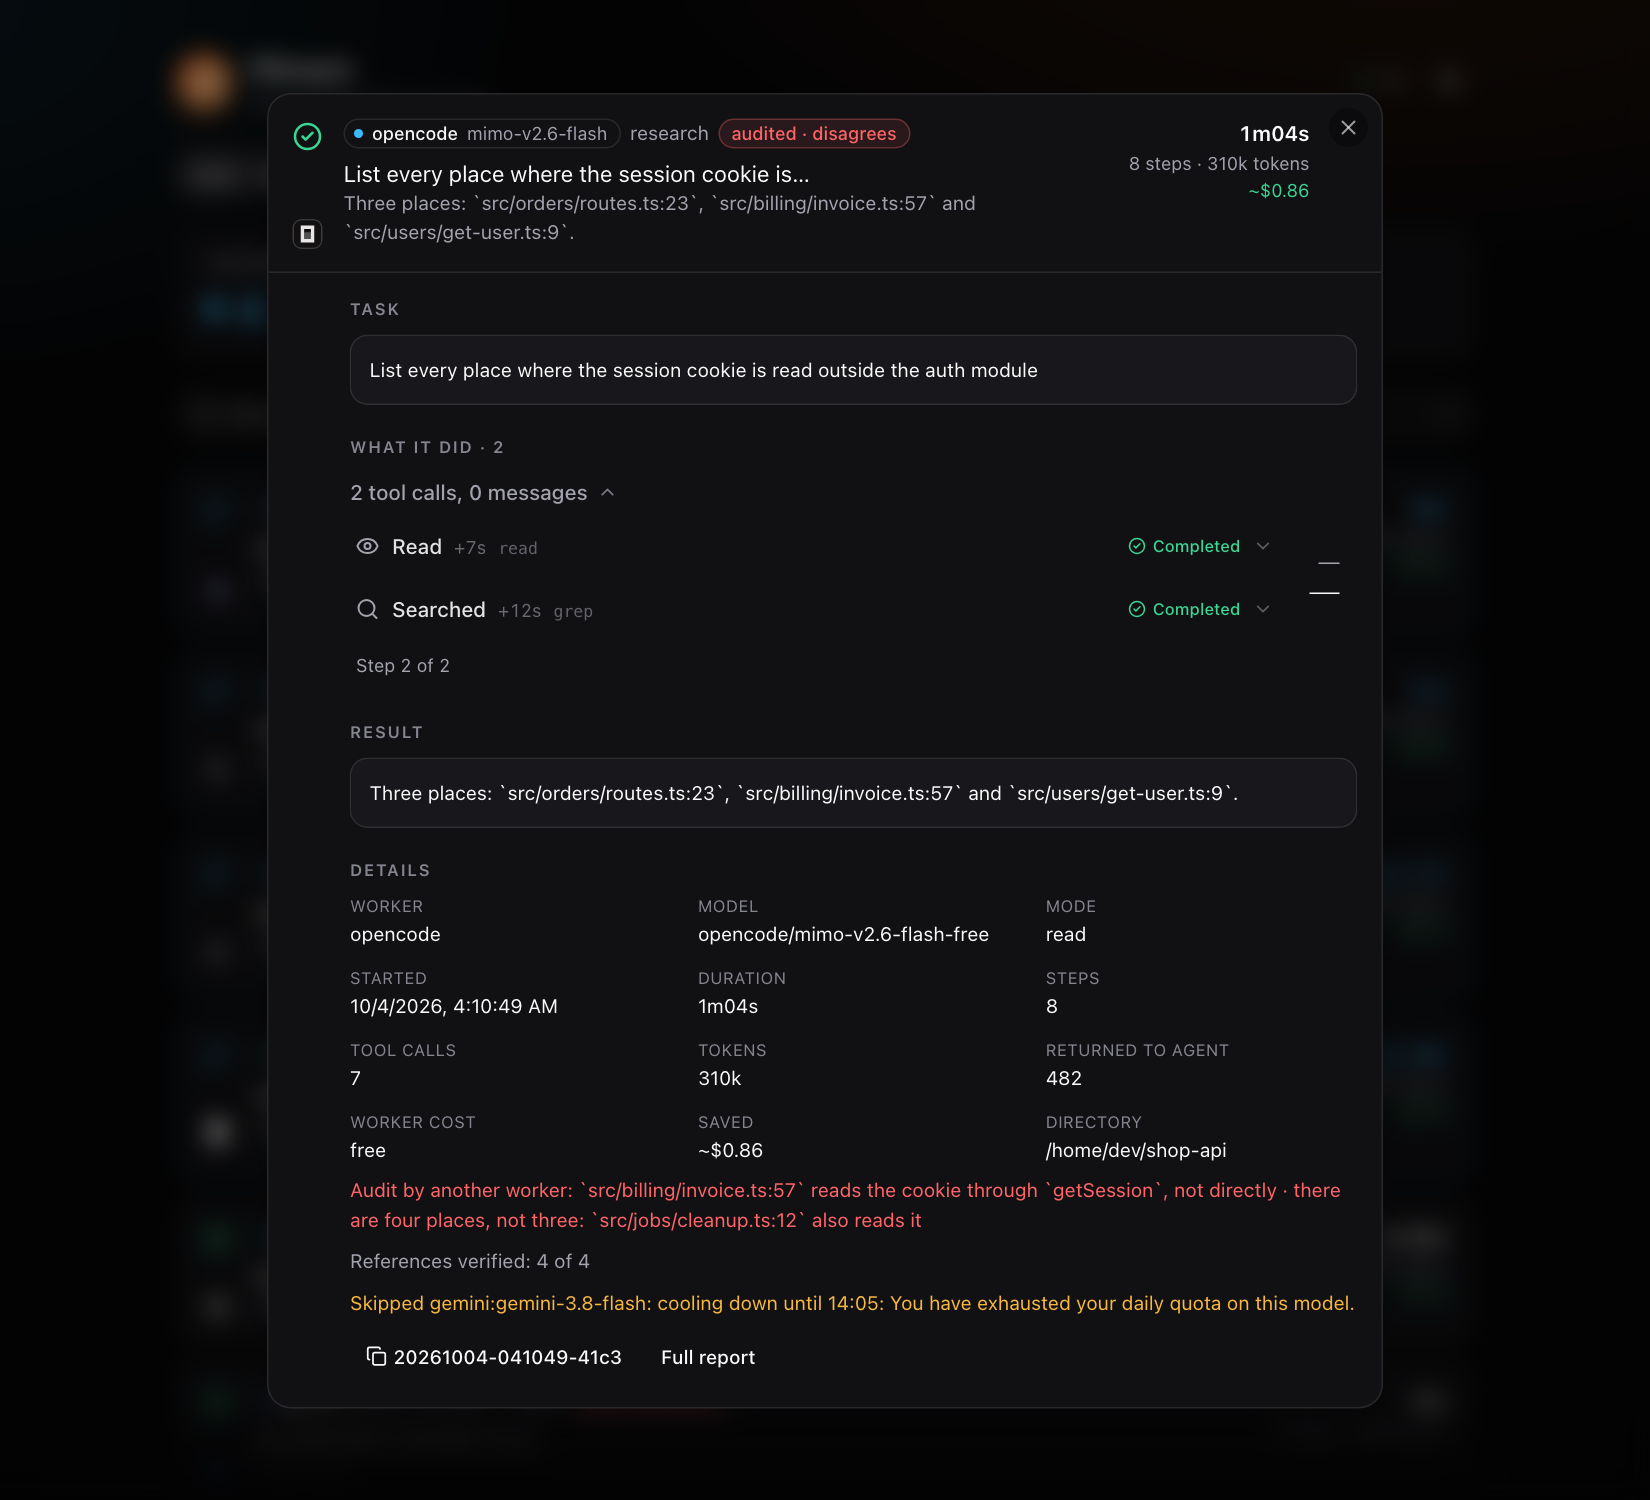
Audits and skipped workers show on the card. A research answer that another worker re-checked (Audits) carries an audited · agrees / partly agrees / disagrees badge and, when it disagrees, the claims it disputes; a worker left out because its quota ran out is listed under the details ("Skipped … cooling down until 14:05", see pitroom cooldown).
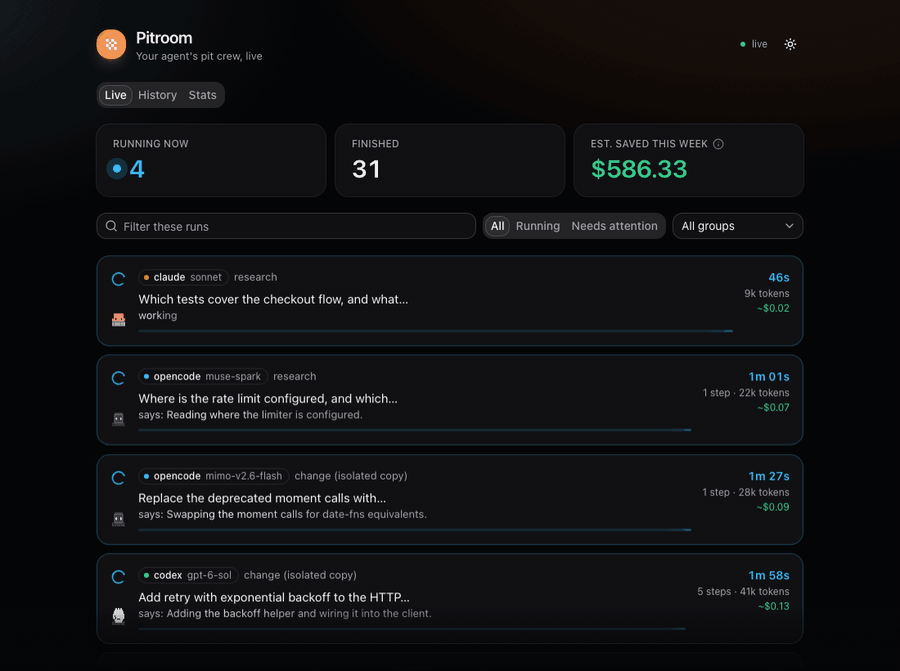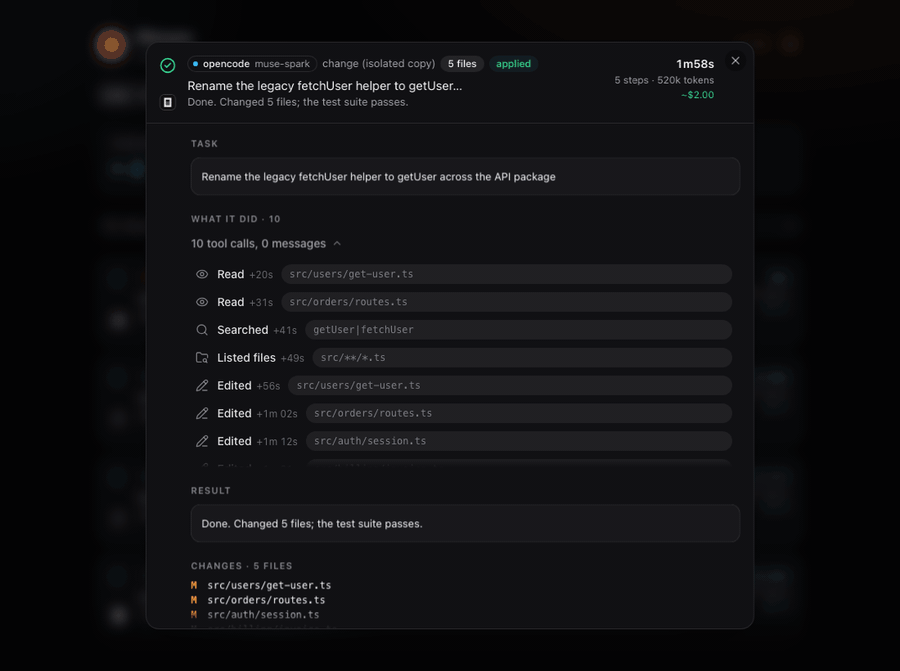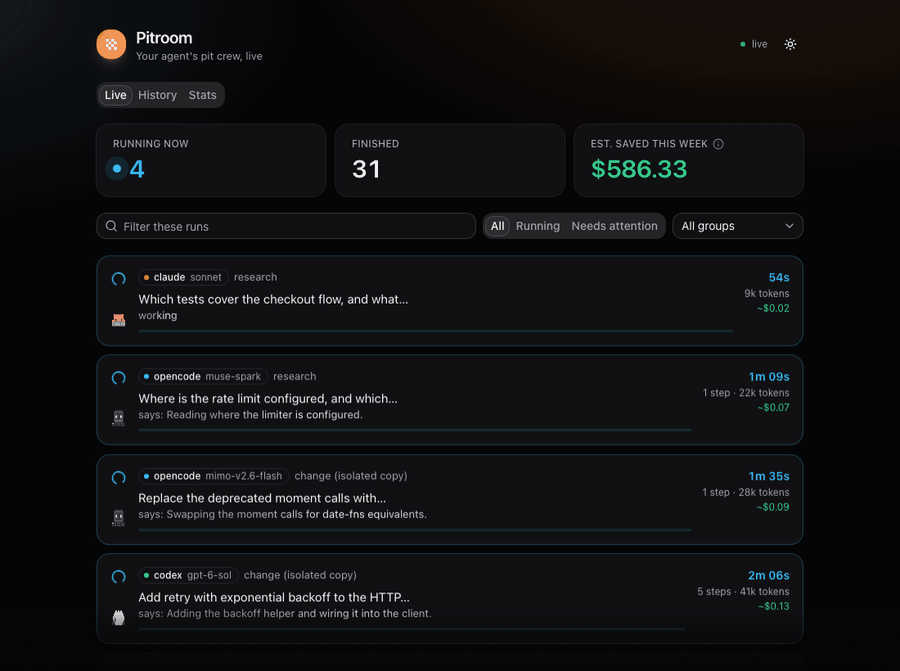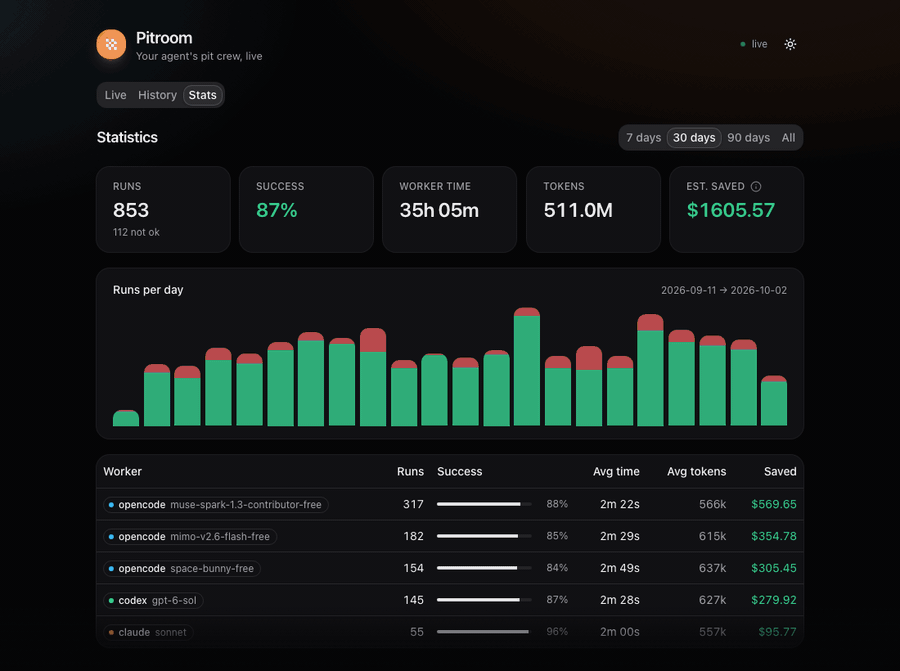
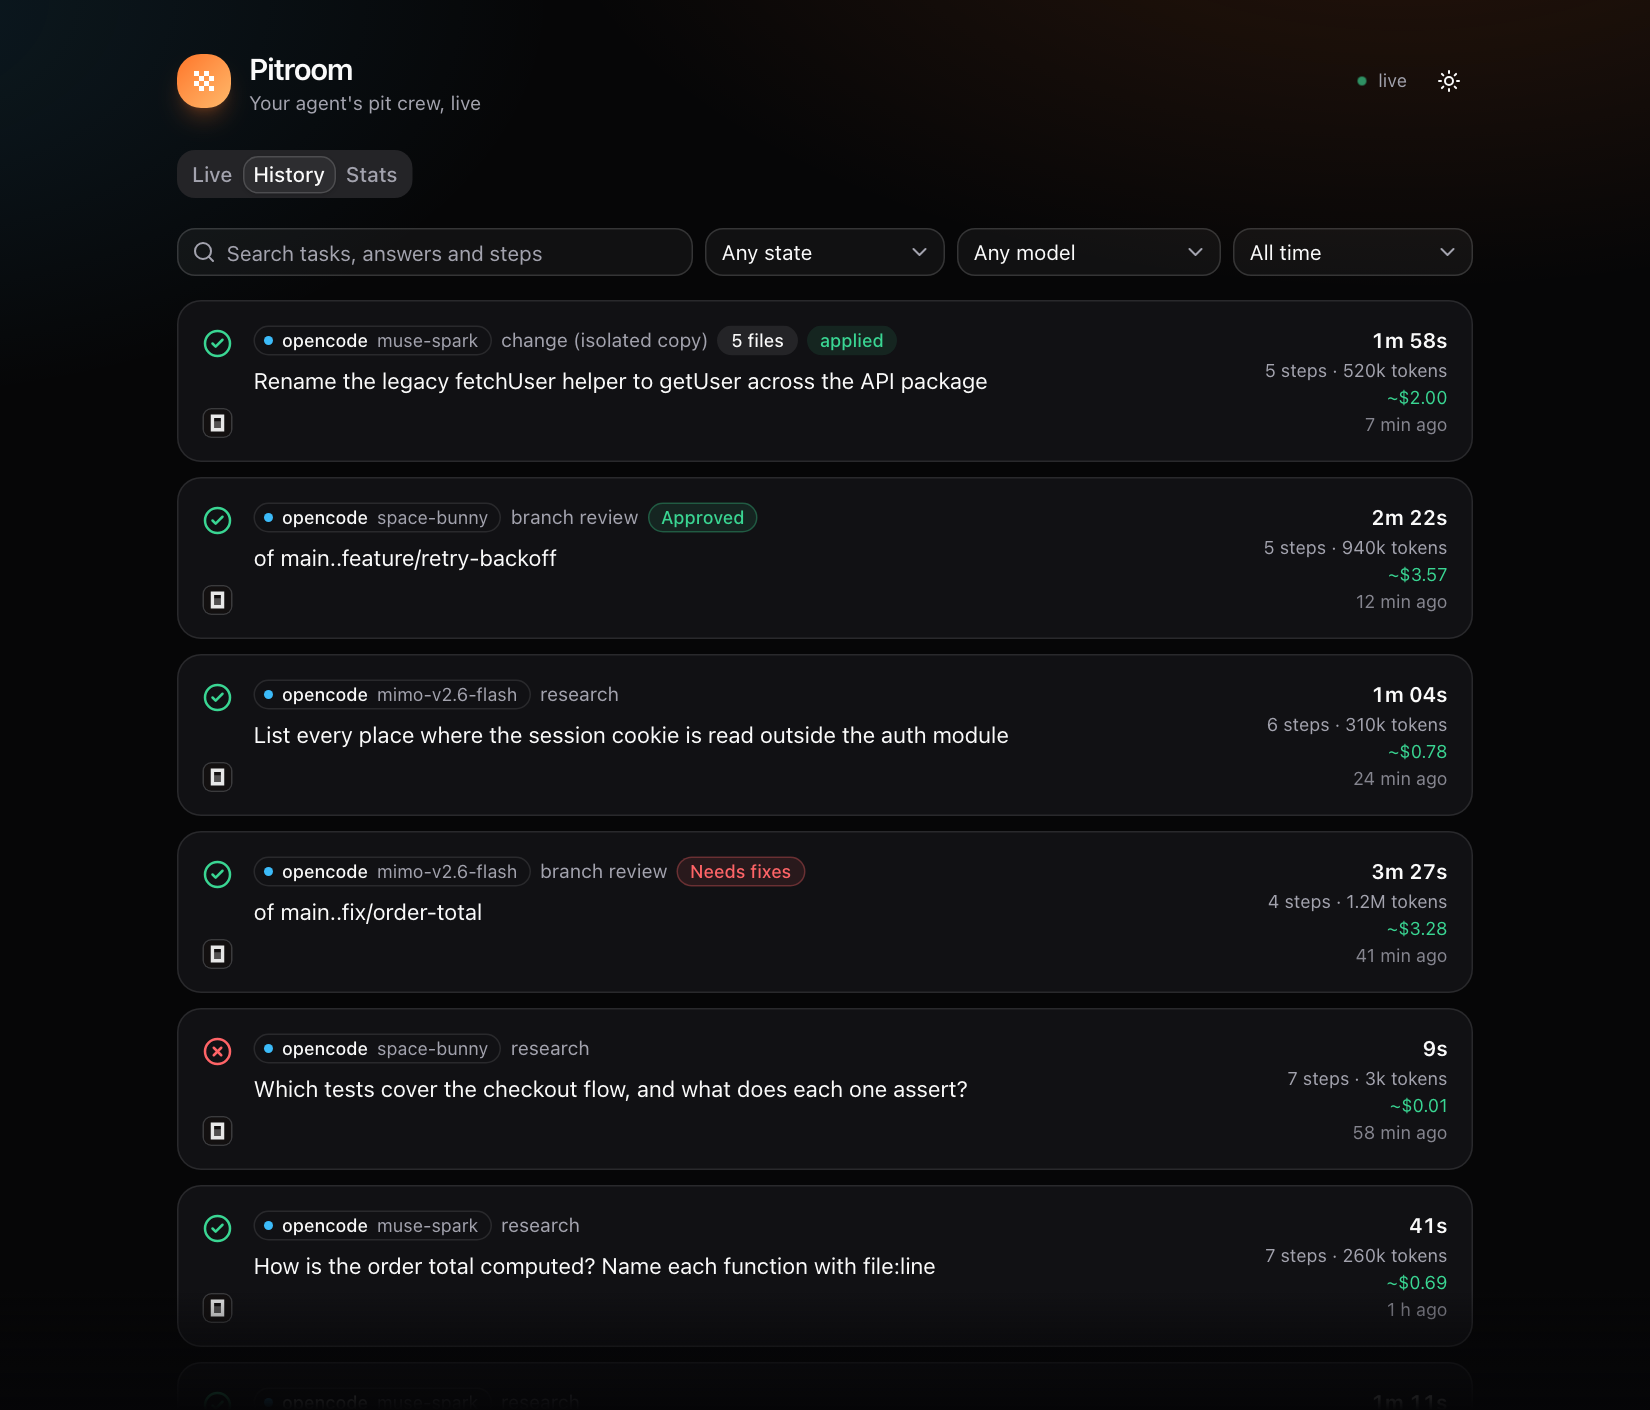
History searches everything Pitroom ever ran (the full text of tasks, answers and steps), with filters by state, model and period; each run opens as the same card as on Live. Stats shows runs, success rate, time, tokens and savings, per worker and model and per day.
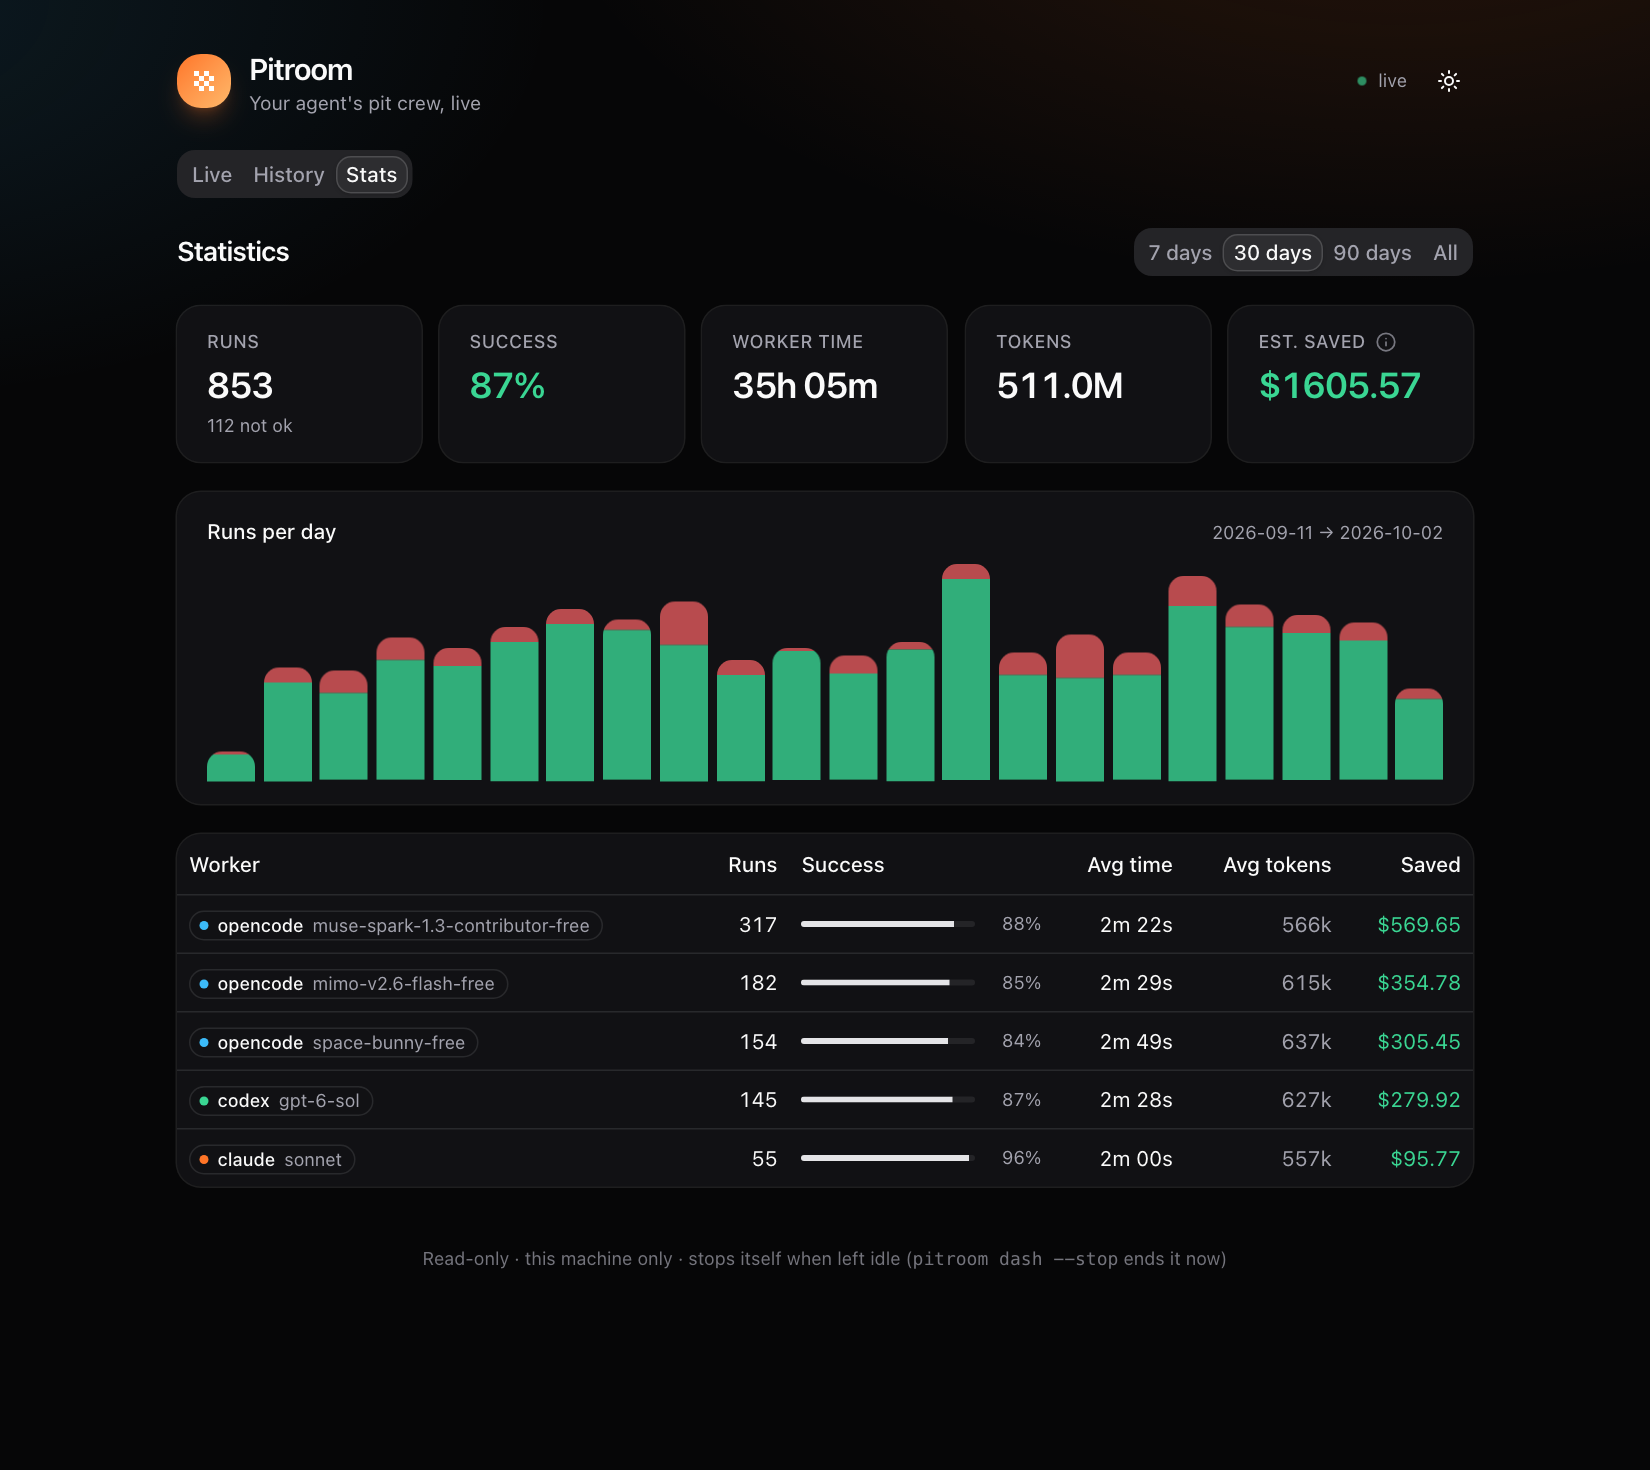
Stop and Discard. A running card has a Stop button, and a finished --isolate card that is not applied yet has Discard (the same as pitroom stop and pitroom discard; the patch file stays). A crew's card has the same for all its runs at once (Stop all, Discard all), and when some of its runs failed, timed out or were stopped, Retry command shows the pitroom run … --bg commands that start them again in the same crew, to copy into a terminal or hand to your agent (quoted for PowerShell on Windows, for a POSIX shell elsewhere). Each action asks once more. Nothing else can be done from the page: it never starts a run and never applies a patch. A POST needs the secret the page was served with (it changes every time the dashboard starts) and the page's own origin, so a web page on another site cannot press them.
The dashboard is a React app built once into dist/ui and served as two static files, so the CLI still has no runtime dependencies. It follows your system's light or dark theme (a button switches it).
Benchmarks
Measured on a real, public repository: PI-Desktop at commit c2bfe35, 2,349 tracked files and about 419,000 lines of TypeScript and Rust. Eight questions of the kind an agent asks before it changes code, run as one read-only crew (pitroom crew, at most four workers at a time) on OpenCode's free muse-spark-1.3-contributor-free model.
In short: on that repository eight questions took 156 s of wall clock, and the workers read 5.5 million tokens and handed the agent 7,684 (715× less); a later audit found some of the answers incomplete. On React, Django and Kubernetes, four free models matched gpt-6-sol on nine bounded questions, and in a planted-bug review test almost every model found almost every bug. The tables, and what they do not show, are below.
PI-Desktop: eight questions, token savings, answer quality and an isolated change
| Question | Worker time | Tokens processed | Returned to the agent | Compression | Refs verified |
|---|---|---|---|---|---|
| Where is the plugin runtime, and which functions activate and deactivate a plugin? | 37 s | 405,380 | 767 | 529× | 10/11 |
| When does the agent runtime compact a conversation? (function and exact condition) | 90 s | 1,250,719 | 763 | 1,639× | 17/17 |
| Where is session state persisted to disk in the Rust host? | 71 s | 854,969 | 1,426 | 600× | 29/45 ¹ |
| Which IPC channels expose window management to the renderer? | 32 s | 165,180 | 716 | 231× | 3/28 ¹ |
| How does a tool call travel from the agent runtime to the Rust host? | 119 s | 1,818,524 | 866 | 2,100× | 14/15 |
| Which packages and apps depend on the i18n package? | 33 s | 271,297 | 656 | 414× | 15/16 |
| Where is auto-update implemented, and what does the Windows portable target change? | 29 s | 215,693 | 743 | 290× | 20/21 |
| Which tests cover the RPC layer? | 59 s | 511,209 | 1,747 | 293× | 6/7 |
| All eight | 156 s wall clock | 5,492,971 | 7,684 | 715× | 114/160 |
Workers read 5.5 million tokens of code and docs (96 steps, 179 tool calls) and handed the agent 7,684 tokens, about 960 per answer. The eight runs add up to 470 s of worker time but finished in 156 s of wall clock, because four ran at a time (the limit then; the default is now 20): about 3× faster than one after another. That compares the same workers with themselves, not with your agent doing the reading alone, which I did not measure. pitroom savings estimates $3.86 saved for these eight at Claude Sonnet list prices.
Were the answers right? Checked by hand against the repository: 46 key claims across all eight answers (the cited line and what it says) were all correct, and two completeness checks held (exactly 6 invoke and 3 event window channels; no tests in config_sync_rpc.rs). The i18n answer lists the 12 source files that import the package and leaves out 11 test and fixture files that do too, which the question did not ask about. Pitroom's own checker marks fewer references as verified than that: ¹ those two answers cite bare file names (transcripts.rs:651) that it cannot resolve to a path, and it counts them as unverified although the lines are right.
An audit found more than the hand check did. Each of the eight answers was later re-checked by a second free worker (pitroom audit, on space-bunny): 3 agreed and 5 were marked partly right. The disputes are about answers that are incomplete or slightly off, not about the lines they cite: lists that leave things out (session state: more places that write it; i18n: a second, deep-import style of consumer; RPC tests: 14 tests missing), counts that are off, and a few cited lines some lines away from the declaration. One was checked by hand and the auditor was right: the RPC mod tests block holds 59 tests, the answer said about 40. The others were not checked by hand, and an auditor is itself a free model that can be wrong. So treat a worker's list or count as a good first answer that your agent confirms when it matters, which is what --audit is for.
A change in an isolated copy: "add a one-line comment above resolveUpdateMode" finished in 16 s and 4 steps (142,491 tokens). The patch was one file and one line, the comment matched the code, and your working tree is untouched until you apply.
Free models against gpt-6-sol on React, Django and Kubernetes
Free models against gpt-6-sol, on three large repositories. The same kind of work on React (7,252 files), Django (7,091) and Kubernetes (31,353 files), at pinned commits. Nine bounded questions, three per repository: the file and line that define a function, how many files contain a word, and which files contain it. Every answer is checked against git grep, not by opinion: an exact path:line (half a point for the right file on the wrong line), an exact count, and for the lists an F1 score that punishes both missed and invented files. Each worker ran the nine questions once, read-only, with no fallback, so a model that cannot do it fails instead of being swapped for another.
| Worker and model | Score | Median time | Median tokens |
|---|---|---|---|
Codex gpt-6-sol (effort medium) | 100% | 16 s | 50k |
Codex gpt-6-sol (effort low) | 100% | 20 s | 50k |
OpenCode muse-spark-1.3-contributor-free | 100% | 23 s | 44k |
OpenCode space-bunny-free | 100% | 35 s | 63k |
OpenCode mimo-v2.6-flash-free | 100% | 37 s | 42k |
OpenCode big-pickle | 100% | 42 s | 91k |
OpenRouter nemotron-3-ultra-550b-a55b:free | 89% | 27 s | 42k |
OpenCode longcat-2.5-preview-free | 89% | 29 s | 20k |
OpenCode nemotron-3-ultra-free | 89% | 35 s | 21k |
OpenRouter inkling:free | 83% | 14 s | 41k |
OpenCode nemotron-3.5-lightning-free | 72% | 377 s | 69k |
NVIDIA gpt-oss-20b (7 questions) | 57% | 24 s | 42k |
Four free models matched gpt-6-sol on these questions. Every model found every definition; the misses are count questions (a wrong number) and, for two models, list questions, one of them by adding docs/ files that are not under django/. gpt-6-sol was as fast as the quickest free models, and lowering its effort did not cost accuracy here. nemotron-3.5-lightning-free wrote an unrelated text for one list question and ran into the 10-minute limit on another. The scoring harness and every raw answer are in benchmarks/multi-repo.
Only workers that ran are in the table. Models that could not answer at all (a provider error, or the shared daily quota of OpenRouter's free tier) are left out, and so are the two gpt-oss-20b runs that ended in a provider error; a timeout is kept.
Does a review find a planted bug?
Does a review find a planted bug? A bug was changed into real code (an inverted check, a swapped &&/||, a flipped return) in React, Django, Kubernetes and Pitroom itself, committed as a bare "tidy", and pitroom review was asked to review the commit. 29 packages (14 with the bug alone, 15 with the bug and three comment-only edits around it). A review counts as a find when a Critical or Important finding names the changed file and either cites a line within 5 or names the changed identifier or its function; "exact line" is the strict version (within 3).
| Worker and model | Bug found | Exact line | Reviews | Mean time | Slowest |
|---|---|---|---|---|---|
OpenCode space-bunny-free | 100% | 100% | 29 of 29 | 2 min 19 s | 5 min 46 s |
OpenCode nemotron-3-ultra-free | 97% | 79% | 29 of 29 | 1 min 45 s | 3 min 29 s |
OpenCode longcat-2.5-preview-free | 83% | 83% | 29 of 29 | 2 min 53 s | 8 min (1 timed out) |
Codex gpt-6-sol | 100% | 100% | 9 of 29 | 38 s | 52 s |
OpenCode muse-spark-1.3-contributor-free | 100% | 57% | 14 of 29 | 48 s | 2 min 0 s |
OpenCode big-pickle | 100% | 92% | 13 of 29 | 2 min 28 s | 5 min 27 s |
OpenCode mimo-v2.6-flash-free | 100% | 100% | 10 of 29 | 4 min 6 s | 7 min 40 s |
Almost every model found almost every bug, so this test separates them on speed and precision, not on whether they can review: muse-spark described the right bug but often quoted a wrong line number (57% exact), and gpt-6-sol and muse-spark were the fastest by a wide margin. Only three models finished all 29: the other four are scored on the reviews that ran before a provider limit (the free tier's usage limit, and the Codex plan's, which gpt-6-sol reached), and the rest are left out, not counted as misses, so their rows rest on 9 to 14 reviews. Every change is only 2 to 5 lines, which is easy; there is no false-alarm rate (the comment-only "clean" packages turned out to contain comments that were really wrong, so they cannot show one); and React, Django and Kubernetes may be in a model's training data. The harness and every raw review are in benchmarks/review-bugs.
What this does not show
- One run per question and model: there is no variance here. The questions are bounded lookups that
grepcan answer, so they do not show how a model handles design questions or large edits, and four free models andgpt-6-solall scoring 100% says the test is easy at the top, not that they are equal. - An open-ended task ("find up to five spelling mistakes in
docs/") did not finish: it was stopped after 19 minutes and 57 tool calls. Give workers bounded tasks. - "Tokens processed" is what the workers read and wrote. What your agent would have spent doing the same reading itself is an estimate, not a measurement: the savings figure assumes it would process about the same tokens. The $0 worker cost is because the model is free.
- The hand check covered key claims, not every citation.
To repeat it on your own repository: pitroom crew -d <repo> -g bench "<question 1>" "<question 2>" …, then pitroom wait -g bench, pitroom show <run> and pitroom savings --models.
Platforms
macOS and Linux are the main platforms. Windows runs the same test suite in CI (Windows Server, Node 22 and 24, with the fake workers; the worker CLIs themselves are not run there), with these differences:
- The git guard is the same two layers as elsewhere, built on the
sh.exethat Git for Windows ships: git's own config (areference-transactionhook that refuses every ref update, and push URLs that go nowhere) is always on; thegitshim (git.cmdfor cmd.exe and PowerShell,gitfor Git Bash) adds friendly refusals and also blocksadd,restore,cleanand the rest. A worker that starts git without a shell (a plainCreateProcess) skips the shim, and is left with the config layer.pitroom doctorsays which is in effect. It is verified in CI with Git for Windows, not yet with the worker CLIs on a real Windows machine. - The launcher is
pitroom.cmd(%USERPROFILE%\.local\bin), started with the Node that ranpitroom installor the one inPITROOM_NODE; it does not search for another Node. - Line endings. Pitroom compares and applies patches byte for byte. Keep
core.autocrlfoff (or aneol=lfin.gitattributes, as this repository has); a checkout converted to CRLF has not been tested withapply. - A read snapshot's files are not made read-only (Windows has no POSIX modes), and a
--verifycommand runs incmd.exe, which reports a missing command asis not recognized.
Quick start
You need Node.js 22.13+ and at least one worker CLI: OpenCode v2+ (the default worker, with free models), Codex CLI, Claude Code Gemini CLI (beta; it needs an API key from Google AI Studio, a Google account sign-in no longer works for it) Qwen Code (beta; any OpenAI-compatible provider, a DashScope key, or a local model) or Kilo Code's CLI (beta; npm i -g @kilocode/cli, its 500+ models and providers).
1. Install: pick your agent
Claude Code
claude plugin marketplace add ATASTECH/pitroom
claude plugin install pitroom@pitroom
Inside a session: /plugin marketplace add ATASTECH/pitroom, then /plugin install pitroom@pitroom.
Codex
codex plugin marketplace add ATASTECH/pitroom
codex plugin add pitroom@pitroom
npm i -g pitroom
Gemini CLI
gemini extensions install https://github.com/ATASTECH/pitroom
npm i -g pitroom
Cursor
npm i -g pitroom
pitroom install --mcp --client cursor
This adds pitroom mcp to ~/.cursor/mcp.json and leaves the other servers in that file alone; restart Cursor if it does not show up. Cursor gets the ten MCP tools described below. The skills are linked into ~/.agents/skills and ~/.claude/skills (--no-skills skips that), and Cursor's documentation lists both as places it loads skills from; we have not run that in a Cursor session, and a Cursor forum report says its CLI (cursor-agent) does not load ~/.agents/skills. pitroom install --mcp --dry-run shows what it would change first.
Any agent that speaks MCP (Claude Desktop, and the ones above too)
Pitroom is also an MCP server on stdio: ten tools instead of shell commands and skills (pitroom_run, pitroom_wait, pitroom_show, pitroom_info, pitroom_review, pitroom_audit, pitroom_apply, pitroom_discard, pitroom_revert, pitroom_stop), the runs as resources, and four prompts. The tool definitions sit in the client's context for the whole session, so they are kept small: about 1.9k tokens. It is listed in the MCP Registry as io.github.ATASTECH/pitroom, so clients that browse the registry can find it. After npm i -g pitroom, let Pitroom register itself in the clients it finds (Claude Code, Codex, Gemini CLI, Cursor, Claude Desktop):
pitroom install --mcp               # also links the skills; add --no-skills to skip that
pitroom install --mcp --dry-run     # only say what it would do
pitroom install --mcp --client cursor,claude-desktop
It registers the launcher by its full path (apps like Claude Desktop start without your PATH), changes Claude Code, Codex and Gemini CLI with their own mcp add command (user scope where it has one), merges the JSON of Cursor and Claude Desktop without touching their other servers (keeping a .bak-pitroom backup, and leaving a file that is not valid JSON alone), skips what is already registered, and pitroom uninstall removes it again. pitroom doctor shows where it is registered. Restart the client afterwards. Or do it by hand:
claude mcp add pitroom -- pitroom mcp
codex mcp add pitroom -- pitroom mcp
gemini mcp add pitroom pitroom mcp
or, for Cursor (~/.cursor/mcp.json), Claude Desktop (claude_desktop_config.json) and others:
{ "mcpServers": { "pitroom": { "command": "pitroom", "args": ["mcp"] } } }
Each tool runs the matching pitroom command, so every rule of the CLI applies unchanged (permission profiles, git guard, isolation, read snapshots). A run is waited for up to waitSeconds (default 50), then comes back as "still running" with its id for pitroom_wait; keep it below your client's tool timeout. The server works in the directory it is started in: the client's for stdio, or the one -d DIR names (Claude Desktop starts it elsewhere, so give it "args": ["mcp", "-d", "/path/to/project"]); the tools' dir argument picks another per call.
More about the MCP server: progress, cancellation, resources, prompts, HTTP
- A live view. A run that is still going after a few seconds starts the dashboard (if it is not already up) and the result carries its address: "Live view of every run: http://127.0.0.1:7878/". The server's instructions tell the agent to open it in its app's own browser pane (the Claude Code and Codex apps have one) or else give it to the user; the system browser is not opened. A run that finishes quickly starts nothing.
"mcpDash": falsein the config (orPITROOM_MCP_DASH=0) turns it off. - Progress. While a call waits for a run, a client that sent a progress token gets a
notifications/progressevery few seconds ("running · read · 12s · 3 steps, 2 tool calls · last: …"), and a client that resets its timeout when progress comes in (the protocol allows it; not every client does) does not give up on a long run. Cancelling apitroom_run,pitroom_revieworpitroom_auditcall stops the run it started (a cancelledpitroom_waitonly stops waiting). - Resources. The latest runs are listed as
pitroom://run/<id>(the report) and, for runs that changed files,pitroom://run/<id>/patch(the exact diff), so a client can attach one to a conversation. A client can subscribe to a run (resources/subscribe) and is told when it changes state (notifications/resources/updated), and every client is told when the newest run changes (notifications/resources/list_changed), so it need not poll; over HTTP these arrive on the session's event stream (a GET). - Prompts.
research,implement,reviewandcrewsay how to use Pitroom for that job (in Claude Code they appear as/mcp__pitroom__research, …), and every skill is a prompt of the same name (using-pitroom,pitroom-research, …), so a client without skills gets the same guidance. The server's instructions tell the agent to use the skills alongside the tools. - More than runs:
pitroom_runtakestasks(independent tasks in parallel, one worker each) andcontinue(a follow-up in the same worker session);pitroom_inforeports without changing anything, bytopic:runs,history(find an earlier answer before asking again),statsandmodels(pick a worker),savings,cooldown,config,doctor;pitroom_stopwithcooldownstries rate-limited models again. - Over HTTP.
pitroom mcp --http [--port N](default 7117) serves the same tools athttp://127.0.0.1:7117/mcpfor clients that connect to a URL, for exampleclaude mcp add --transport http pitroom http://127.0.0.1:7117/mcp --header "Authorization: Bearer $(cat ~/.local/state/pitroom/mcp-token)"(the command is printed when it starts). It is a local service: it listens on 127.0.0.1 only, needs the bearer token (made on first start, kept at<state dir>/mcp-tokenwith owner-only permissions, or set withPITROOM_MCP_TOKEN), and refuses a Host or Origin that is not local, so a web page cannot use it. Anyone who has the token can run workers as you, so keep it private. It works in the directory it was started in (printed when it starts;-d DIRfor another). Each client has its own session; a call that asks for progress is answered as an event stream. Ending a session or stopping the server ends the waiting, not the runs: collect them withpitroom_waitor the CLI.pitroom install --mcpregisters the stdio command, which needs no token and no running process.
Any other agent (a plain shell) or just the CLI
npm i -g pitroom
pitroom install
| Path | You get |
|---|---|
| Claude Code plugin | The 14 skills, the session-start hook that introduces Pitroom, and a card after each pitroom command. |
| Gemini CLI extension | The 14 skills and a short context file that introduces Pitroom (Gemini asks you to confirm the extension). Gemini CLI also works as a worker, which is separate: see Workers. |
| MCP server | The nine tools above, for any agent that can use MCP servers. No skills: the tools describe themselves, and the server tells the agent how to start. |
| Codex plugin | The 14 skills, a session-start hook that introduces Pitroom (so it is known even when Codex drops skill descriptions because many are installed), and a card after each pitroom command. Codex asks you to trust the plugin's hooks once. The hooks call pitroom, which comes from npm (npm i -g pitroom). |
npm + pitroom install | The CLI, and the skills linked into ~/.agents/skills and ~/.claude/skills. |
Pick one path, not several: doctor warns if the skills load twice. The plugins alone do not put pitroom on your PATH, so install it from npm too if you want to run it yourself (watch, models, savings, the status line).
2. Check the setup
pitroom doctor --probe
It checks the worker CLIs, models, permissions and skills, and runs one live round trip.
3. Use it
Pitroom is a toolbox, not a procedure: your agent uses it when it helps, or you ask explicitly:
Use pitroom to map how sessions are created and invalidated, then propose a fix. Split this into a pitroom crew: audit auth, billing and uploads for missing input validation.
Or start a worker yourself and read its receipt:
pitroom "Which files read the session cookie? Cite file:line."
pitroom -W gemini:gemini-3.8-flash "…"   # the same on another worker (see Workers below)
pitroom savings          # what all your runs saved so far
pitroom models           # what each worker offers, what it costs you, what it used
Update and uninstall
# update
claude plugin update pitroom@pitroom
codex plugin marketplace upgrade pitroom
npm i -g pitroom@latest

# uninstall
claude plugin uninstall pitroom@pitroom
codex plugin remove pitroom@pitroom
pitroom uninstall && npm rm -g pitroom
Modes
| Flag | For | Your working tree | |
|---|---|---|---|
| read | (default) | research, locating code, reviews | untouched; edit tools are denied |
| isolate | -i | code changes you want to review first | untouched until pitroom apply |
| write | -w | quick in-place edits | edited now; pitroom revert undoes exactly |
Read snapshots. With secret-looking files in the directory, a read run reads a snapshot of your project's current state (uncommitted and untracked files included) without them and without git-ignored files, made from git objects, kept once per state and shared by every read run on it (twenty workers, one snapshot), and cleaned up after three days or by pitroom clean. Nothing is copied back: a read run has nothing to land. Its files are read-only, and the paths a worker cites are turned back into your project's. With no secret-looking files nothing changes: the worker runs in place. --in-place (or "readIn": "project" in the config) reads the directory itself, e.g. for a task that needs build output; "readIn": "snapshot" always uses one.
Answer cache. Ask the same read question on the same code and you get the earlier answer back at once, with no worker run: pitroom ⟲ cached answer · the same question on the same code as run … · no worker ran. "The same code" is exact: the commit and every working file, uncommitted and untracked ones included (git-ignored files are not code), so any edit makes it a new question. Only answers that held up are reused (the run finished, every file:line reference checked out, no audit disputed it) and only for 7 days ("cacheDays" in the config, 0 turns it off, or PITROOM_CACHE_DAYS). Follow-ups, web runs, plan tasks, reviews, audits, --verify runs, parallel work (crews) and changes are never answered from the cache, and --fresh asks a worker anyway (its answer is the one reused from then on). Not part of "the same code": git-ignored files (build output, installed dependencies) and the worker or model that answered; when a question depends on them, use --fresh.
pitroom run "Find every place we build SQL strings by hand; file:line and risk"
pitroom run -i --link node_modules --verify "npm test" "Fix the off-by-one in paginate() and add a test"
pitroom run -w "Rename getUserById to findUserById in src/ and fix imports"
pitroom run --continue last "Now handle the empty-page case too"
Long jobs: --bg returns immediately; pitroom wait <id> blocks for up to 9 minutes (made for agents with 10-minute tool limits; exit code 75 means "call wait again").
Workflow
Pitroom ships a full development methodology as skills, adapted from superpowers so that its subagents are cheap workers: your agent brainstorms and plans with you, then executes the plan task by task while workers do the typing and a second model does the reviewing.
The workflow, step by step
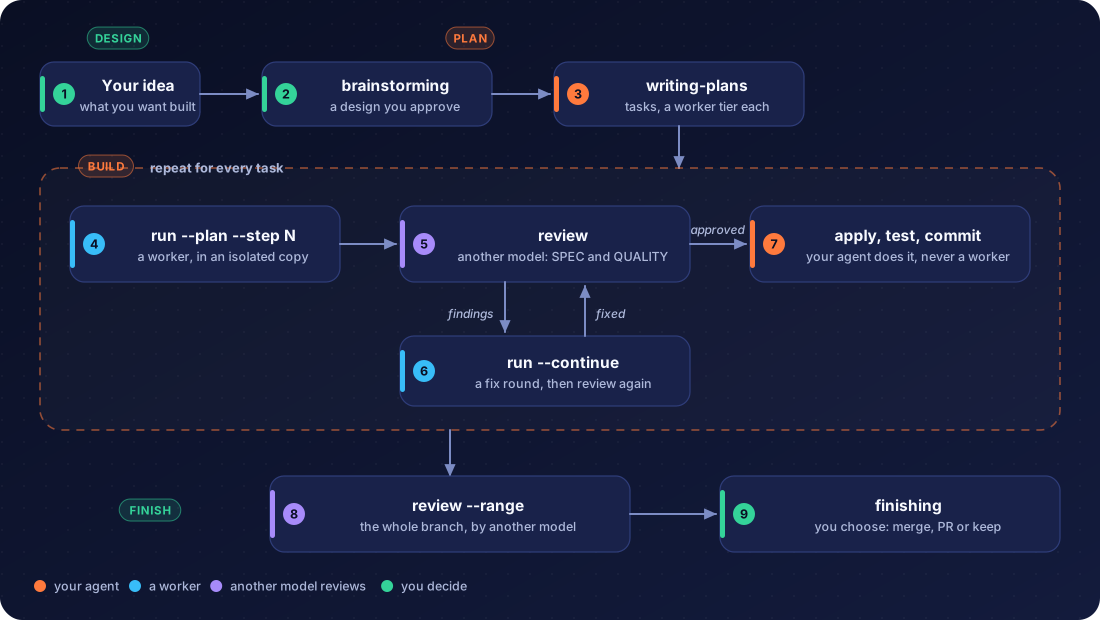
| Step | Skill | Command |
|---|---|---|
| Design | pitroom-brainstorming | writes the spec to docs/pitroom/specs/ |
| Plan | pitroom-writing-plans | writes the plan to docs/pitroom/plans/, a worker tier on every task |
| Implement | pitroom-driven-development | pitroom run -i --plan PLAN --step N |
| Review | pitroom-review | pitroom review <run> (a read-only reviewer on another model) |
| Fix | pitroom-receiving-review | pitroom run --continue <run> "…" (the re-review sees only the fix) |
| Land | pitroom-driven-development | pitroom apply <run>, your tests, your commit |
| Branch review | pitroom-review | pitroom review --range main..HEAD --plan PLAN |
| Finish | pitroom-finishing | merge, pull request or keep: asked, never automatic |
A review package holds the diff under review with 10 lines of context, and the reviewer's CLI sends it to that worker's model provider. Pitroom does not filter it: secrets committed in a reviewed range go along as they are.
Tiers map plan tasks to workers: "tiers": {"cheap": "opencode", "standard": "codex", "capable": "claude"}. pitroom plan status PLAN rebuilds where a plan stands from the run records (it survives context compaction), and pitroom plan note keeps completions and rulings outside the repo.
Audits
Pitroom checks every path:line a worker cites, which proves a line exists, not that the claim about it is true. An audit asks a second worker to verify an answer's key claims against your project and to say AGREE, PARTIAL or DISAGREE, with the claims it disputes.
pitroom audit <run>            # now: re-check one read run (-W picks the auditor)
pitroom run --audit "…"        # re-check this run's answer when it finishes (--no-audit skips it)
or set "audit": 0.1 in the config (or PITROOM_AUDIT=0.1) to have about one read run in ten audited, in the background, without your agent asking. The same run is always in or out of the sample.
Cost, limits and where the verdict shows
- Cost: off by default. An audit is a read run of the auditor, so about the rate times the worker's own tokens, on the
audittier (elsecheap, i.e. a free model if that is your cheap tier). It never delays the run or fails it. - Never itself: the auditor is never the worker and model that gave the answer; with no other worker configured nothing is audited (
pitroom doctorsays so). Only read runs are audited: a change haspitroom review. - Where it shows: the answer's card and
pitroom showcarry the verdict and the disputed claims; the Stats tab counts, per worker, how many audited answers were confirmed. Audits are not counted as runs and save nothing. - A sample, not a guarantee. The auditor is a model too: it can share a blind spot, and a few audits say little about a worker. Treat
DISAGREEas a reason to look, andAGREEas one more signal.
Corrections ("auditFix": true, or PITROOM_AUDIT_FIX=1; off by default). When an audit says PARTIAL or DISAGREE and names the claims it disputes, the answer goes back to the worker that gave it: a follow-up in its own session (which still holds what it read) with the disputed claims, to check against the files (the auditor can be wrong too) and to answer again in full, saying under OPEN ISSUES which claims it accepted. One round only: a correction is never sent back again. The audited run's card and pitroom show name the correction run (── fix: …). Every built-in worker can continue its session, which this needs.
A focused sample ("auditFocus": true, or PITROOM_AUDIT_FOCUS=1; off by default). With an audit rate set, the sample leans to where audits find the most: the rate is doubled for a question that asks for all of something, a list or a count, doubled again for a worker whose audited answers were confirmed less than half the time (3 audits or more in 30 days), and halved for one whose last 5 or more were all confirmed. --audit and --no-audit are never changed; the run records the chance it got and why.
Evals
Your own benchmark, on your own code: questions with known answers, put to the workers you want to compare, and scored.
pitroom eval questions.json -W opencode -W codex:gpt-6.1-sol    # every question to every worker, as one group
pitroom eval questions.json --json                               # the same as JSON: truths, rows, a summary per worker
{
  "questions": [
    { "id": "def", "kind": "definition", "task": "Which file and line define `export function loadConfig(`? The SUMMARY line must be only path:line.", "truth": { "grep": "^export function loadConfig\\(", "regex": true, "dir": "src" } },
    { "id": "count", "kind": "count", "task": "How many files under src/ contain the word effective? The SUMMARY line must be only the number.", "truth": { "grep": "effective", "word": true, "dir": "src" } },
    { "id": "list", "kind": "set", "task": "List every file under src/ that mentions node:sqlite. The SUMMARY line must be only the paths, separated by commas.", "truth": ["src/cli/commands.ts", "src/core/history.ts"] }
  ]
}
A truth is written down ("path:line", a number, a list of paths) or looked up when the eval starts with git grep (grep, and optionally dir, word, regex, exclude), so it stays right as the code changes. Scoring is that of the multi-repo benchmark: a definition gets 1 for the exact path:line and 0.5 for the right file, a count only for the exact number, a list the F1 of the paths it names (from the SUMMARY, else the DETAILS). Each worker answers for itself: no fallback, no audit, no cached answer. The runs are an ordinary group, so pitroom watch -g, the dashboard and the history show them.
Crews
A real crew over this repository, four questions at once on a free OpenCode Zen model:
pitroom crew -g v04-demo \
  "Where does Pitroom enforce the maxParallel queue, and how does a waiting run react to pitroom stop? Cite file:line." \
  "How does the git guard shim resolve git aliases? Cite file:line." \
  "Which fields of OpenCode v2 events does the parser read for token usage, refused tool calls and errors? Cite file:line." \
  "How does pitroom apply -g decide which patches to apply and in what order? Cite file:line."
pitroom watch -g v04-demo --json   # what the primary agent follows, one line per change:
What the crew prints: the stream your agent follows and the status table
{"event":"started","run":"20260930-102812-a65d","mode":"read","task":"Where does Pitroom enforce the maxParallel queue, and how d…"}
{"event":"progress","run":"20260930-102812-a65d","steps":3,"tools":4,"last":"grep SIGINT|SIGTERM|stop.*queued|stopped.*queued"}
{"event":"done","run":"20260930-102812-a563","time":"21s","worker":"opencode (default model)","summary":"The shim resolves `alias.<sub>` via `real git config --get` in a loop …","refs":"5/5"}
{"event":"all-done","runs":4,"ok":4,"failed":0}
$ pitroom status -g v04-demo
RUN                   STATE  MODE  TIME  STEPS  WORKER                    NOW / RESULT
20260930-102812-0c0d  done   read  30s   5      opencode (default model)  Parser `src/backends/opencode/events.ts` reads …
20260930-102812-7642  done   read  27s   5      opencode (default model)  `pitroom apply -g NAME` applies finished isolat…
20260930-102812-a563  done   read  21s   2      opencode (default model)  The shim resolves `alias.<sub>` via `real git c…
20260930-102812-a65d  done   read  39s   7      opencode (default model)  maxParallel is enforced by file-based slots (`s…
Humans get the same table live with pitroom watch -g NAME; pitroom wait -g NAME --brief prints one line per worker, pitroom show <run> the full answer.
For changes, pitroom crew -i … gives every worker its own isolated copy of your current state and pitroom apply -g NAME lands the patches in order, stopping at the first conflict. Up to maxParallel workers (default 20, at most 30) run at once, the rest queue; only one --write run per repository is allowed. pitroom stop -g NAME stops running and queued workers.
Skills
The 14 skills
| Skill | Your agent uses it to |
|---|---|
using-pitroom | see what Pitroom offers and when it pays off (injected at session start by the plugin; optional) |
pitroom-brainstorming | turn an idea into an approved design before any code |
pitroom-writing-plans | write a task-by-task plan with a worker tier per task |
pitroom-driven-development | execute a plan: worker per task, review on another model, fix loop, apply, commit |
pitroom-worktrees | isolate its own branch for the work |
pitroom-tdd | test first, for itself and the workers it briefs |
pitroom-debugging | find root causes, with workers gathering the evidence |
pitroom-verification | run the checks before claiming anything is done |
pitroom-review | get a change, a fix round, a branch or a PR reviewed by another model |
pitroom-receiving-review | weigh review findings with technical rigor |
pitroom-finishing | merge, open a PR or keep the branch, as the user chooses |
pitroom-research | find, map or explain code through a read-only worker |
pitroom-implement | get a one-off change made in an isolated copy |
pitroom-crew | split independent work across parallel workers and merge the results |
Commands
All commands and exit codes
pitroom run [-r|-w|-i] [-W WORKER] [-m MODEL] [-d DIR] [-f FILE]… [-t 30m] [--verify CMD] [--link a,b] [--bg] "task"
pitroom run --continue <run|last> "follow-up"
pitroom crew [-i] [-g NAME] "task 1" "task 2" …   (or --task-file with --- separators)
pitroom run -i --plan PLAN --step N [--tier T] ["notes"]
pitroom review [run | --range A..B [--plan PLAN]] [--tier T | -W T] [--bg]
pitroom audit RUN [-W worker]
pitroom eval QUESTIONS.json [-W worker]… [--json]   your questions with known answers, scored per worker
pitroom mcp [-d DIR] [--http [--port N]]   # serve Pitroom as MCP tools on stdio, or over HTTP on 127.0.0.1 (bearer token)
pitroom cooldown [--clear]
pitroom plan status PLAN [--json] · pitroom plan note PLAN "Task N: …"
pitroom status|wait|watch [run… | -g NAME]        wait: --any --brief --timeout · watch: --json|--brief --interval
pitroom dash [--detach] [--port N] [--open] [--stop]   a live page of the runs on 127.0.0.1
pitroom history [TEXT] [--model M] [--state S] [--since 30d] [--limit N] [--json]   finished runs, searchable
pitroom history stats [--since 30d] · pitroom history import   per worker and model · take in older runs
pitroom show [run]                                --patch --events --full --json
pitroom apply [run | -g NAME] · pitroom discard|revert [run] · pitroom stop [run | -g NAME]
pitroom ls [--running] [-g NAME] · pitroom clean [--days 14] [--yes]
pitroom savings [--since 7d|30d|all] [--models] [--card file.svg] [--badge]
pitroom models [worker] [--all] [--json]      models, effort levels, your costs, your usage
pitroom statusline [--then CMD] · pitroom hook-card
pitroom doctor [--probe] · pitroom config · pitroom init [--model ID] [--fallback A,B] [--yes] [--force] · pitroom install [--copy] [--force] [--mcp [--client A,B] [--no-skills] [--dry-run]] · pitroom uninstall
Exit codes: 0 ok · 1 worker failed · 2 usage · 3 refused/setup · 4 timeout · 5 read-only violation · 6 verify failed · 75 still running.
History
Searching the history
Every finished run is also written to a SQLite database (history.db in Pitroom's state directory; Node's built-in node:sqlite, nothing to install). It keeps the task, worker and model, time, tokens, savings, the steps the worker took, its answer and the diff, and it is searchable:
pitroom history "login bug"            # full-text search over the task, the answer and the steps
pitroom history --state problem --since 7d
pitroom history stats --since 30d      # runs, success rate, average time and tokens per worker and model
While a run runs, its raw event stream is a plain file (the simplest thing that survives a crash). When it ends, the stream is compressed, and the stderr log is kept only for runs that did not succeed. pitroom clean removes old run directories but the history keeps them: pitroom show <run> still prints their report, steps, and patch. Runs from before the history existed are taken in by pitroom history import (it also runs on the first pitroom history and pitroom dash). The files remain the source: the database can be deleted and rebuilt with history import for the runs still on disk.
Seeing Pitroom at work
The status line and hook cards (and what the apps show instead)
Two settings make every delegation visible, whether or not the agent mentions it. A status line shows running workers and this week's savings (--then keeps your own status line first); a card appears after each pitroom command the agent runs, once per phase (started, finished with its result, applied). The plugin registers the card hook itself; with pitroom install, add both to ~/.claude/settings.json:
{
  "statusLine": { "type": "command", "command": "pitroom statusline --then 'your-own-statusline'" },
  "hooks": {
    "PostToolUse": [{ "matcher": "Bash", "hooks": [{ "type": "command", "command": "pitroom hook-card", "timeout": 10 }] }]
  }
}
The Claude Code and Codex apps show neither hook messages nor a status line. For them there are two things that need no setup:
pitroom dash --detachprints the address of a live dashboard with three tabs: Live (every running and recent run as an animated card; click one for the task, what the worker did step by step, its result, the diff and the details), History (search and filter everything Pitroom ever ran; every run opens as the same card) and Stats (success rate, time, tokens and savings per worker and model). It is read-only, listens on127.0.0.1only and stops itself after an hour without a request (pitroom dash --stopends it sooner). Open it in a browser or in the app's own browser pane. The skills tell the agent to start it and give you the address when it runs workers in the background.pitroom watch -g NAME --briefprints one card line when a worker starts and one when it ends. In Claude Code, the agent runs it through the Monitor tool and the lines appear in the app; in Codex the command's output block fills as it goes.
How it works
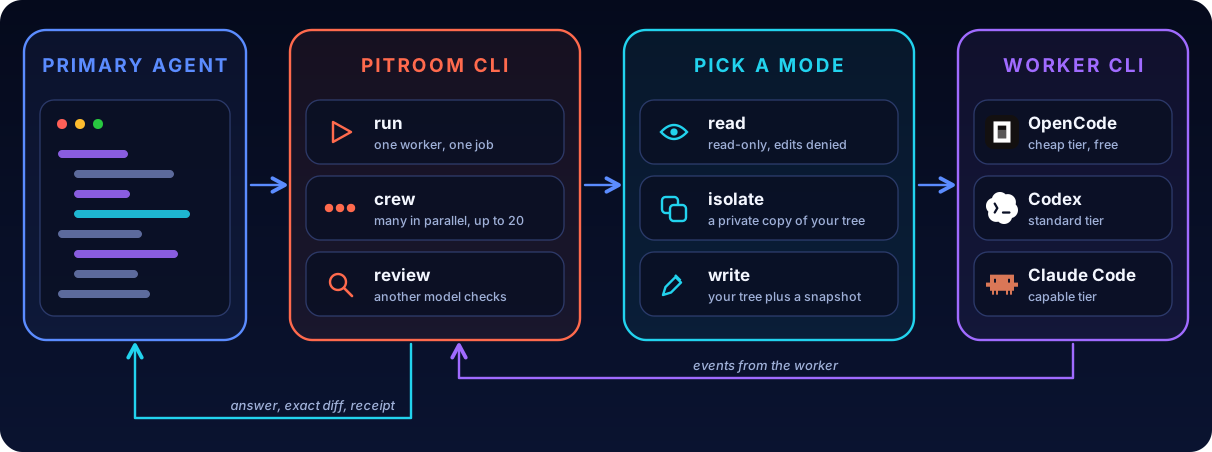
Headless problems Pitroom handles for every worker
Handled for every worker: opencode run blocks forever on an open stdin pipe; ask permissions stall headless runs; default output carries ANSI and banners; and in OpenCode v2 a plain run attaches to the shared background service, where per-run permissions and the git guard would not apply. Pitroom closes stdin, uses allow/deny-only profiles, parses --format json and always runs a private --standalone server.
Workers
A worker is named by a target: backend[:model].
pitroom run "…"                                          # preferred worker (config "worker", default opencode)
pitroom run -W opencode:opencode/space-bunny-free "…"    # a specific backend and model
pitroom run -W 'codex:#low' "…"                          # the model from config "models" (not Codex's default), low reasoning effort
pitroom run --effort high "…"                           # model#level (Codex, Claude Code, OpenCode; Gemini CLI has no effort option)
pitroom run -W claude:haiku "…"                          # Claude Code on a cheap model
pitroom run -W gemini:gemini-3.8-flash "…"               # Gemini CLI (beta; needs a Google AI Studio API key)
pitroom run -W qwen:qwen3-coder-plus "…"                 # Qwen Code (beta; your provider from ~/.qwen/settings.json)
pitroom run -W kilo:kilo/<model> "…"                      # Kilo Code's CLI (beta; any model from `kilo models`)
pitroom run -m nvidia/z-ai/glm-5.3 "…"                   # another model on the preferred worker
| Worker | Status | Read-only enforced by | Cost in receipts | Notes |
|---|---|---|---|---|
| OpenCode (v2+) | ✅ | per-run permission rules | reported | private --standalone server per run |
| Codex CLI | ✅ | OS sandbox (read-only / workspace-write) | tokens only | codex login; your ~/.codex/config.toml is ignored for workers (its MCP servers run outside the sandbox); models take #effort |
| Claude Code | ✅ | tool allowlist (--restricted --safe-mode, dontAsk) | reported | claude auth login; its default is often Opus, so prefer -W claude:haiku |
| Gemini CLI | beta | --approval-mode plan plus Pitroom's policy rules | tokens only | an API key from Google AI Studio (sign in with gemini or set GEMINI_API_KEY; Google account sign-in is refused by Google); workers run in a private Gemini home without your hooks, MCP servers and skills; secret-file rules are not enforced by Gemini 0.62, but a read run with secret-looking files reads a clean snapshot without them; pin a model, e.g. -W gemini:gemini-3.8-flash; --continue works (by session id; see the notes) |
| Qwen Code | beta | --approval-mode plan; edits only inside the working directory, the rest declined | tokens only | checked against Qwen Code 0.25 with a scripted model, not yet with a real provider; uses your sign-in and model from ~/.qwen/settings.json (any OpenAI-compatible provider, DashScope, a local model); --safe-mode keeps your QWEN.md, hooks, skills and MCP servers out and stops the CLI writing memories of the run; reads .env if asked, so a read run with secret-looking files reads a clean snapshot; see the notes |
| Kilo Code | beta | per-run permission rules (OpenCode's profiles) | reported | the CLI of @kilocode/cli (an OpenCode fork): the same pitroom-read/pitroom-write profiles through KILO_CONFIG_CONTENT, your sign-in and providers as they are; workers use a private state folder so a running kilo daemon (which would ignore the profiles) is never attached to; checked against Kilo 7.8.8 with a scripted model, not yet with a real provider; see the notes |
Models, costs and effort
Models, costs and effort levels
pitroom models lists what each worker offers (Codex from its own model cache, Claude Code's aliases, OpenCode's opencode models, Gemini CLI's built-in names), the reasoning-effort levels each model accepts, what you say it costs and what your own runs used:
worker  model        effort (* default)                 cost  runs  avg tokens  $/run   in use
codex   gpt-6.1-sol  low*/medium/high/xhigh/max/ultra   2     20    174k        -       tier standard
codex   gpt-6-sol    low/medium*/high/xhigh/max/ultra   1     1     24k         -       -
claude  haiku        low/medium/high/xhigh/max          ?     -     -           -       -
Pitroom knows no vendor prices of its own and, unless you turn on priceFeed (see the config notes), fetches none, so a cost is what you enter: "costs": {"codex:gpt-6-sol": 1, "codex:gpt-6.1-sol": 2} in the config, in any unit (they are only compared; dollar prices for the receipts of Codex and Gemini go in workerPrices, see the config notes). pitroom doctor then prints the cost of the models in use and says when you priced a cheaper one of the same worker. A target that names only an effort (codex:#low) uses the model from models; a Codex or Claude Code worker with no pinned model gets a warning, because it would run the vendor's own default, which can change and cost more. --effort LEVEL sets the level for one run; your agent picks model and level from pitroom models (cheapest that fits: low for lookups, medium for ordinary changes, high for reviews).
Fallbacks cross backends (e.g. "fallback": ["codex:#low", "opencode"]): a worker that is rate-limited, logged out or missing its model hands the task to the next. Follow-ups (--continue) always stay on the worker that owns the session. Writing an adapter: docs/backends.md. A model that says "rate limited" (a daily quota used up, an overloaded provider) is remembered for the time its message gives, or a guess: the next runs skip it while a fallback is left, so they do not each wait for it to fail. pitroom cooldown lists what is skipped and until when, --clear tries it again, and doctor shows it too.
Configuration
Environment variables
| Env | Default | |
|---|---|---|
PITROOM_WORKER | opencode | Preferred worker target: backend[:model] |
PITROOM_MODEL | the worker's default | Model for the preferred worker |
PITROOM_FALLBACK | none | Comma-separated targets to fail over to on model/provider errors |
PITROOM_TIMEOUT | 30m | Per-run timeout |
PITROOM_MAX_PARALLEL | 20 | Workers running at once (at most 30); more queue |
PITROOM_PRIMARY | sonnet | Pricing preset for the savings estimate: sonnet, opus, haiku, gpt-5 |
PITROOM_PRICE | Custom primary price, USD per 1M tokens: "in,out[,cachedIn]" | |
PITROOM_HOME | ~/.local/state/pitroom | Where run records and the ledger live |
PITROOM_NO_SECRET_WARNING | Set to 1 to stop the warning about .env files and private keys in the worker's directory | |
PITROOM_<WORKER>_BIN | on PATH | Path to a worker CLI, e.g. PITROOM_OPENCODE_BIN |
Or put defaults in ~/.config/pitroom/config.json (flags and env still win); pitroom config shows every effective value and where it came from. pitroom init proposes a starter config from the worker CLIs and OpenCode models you have (a fallback chain of your free models, tiers when more than one CLI is installed) and writes it only with --yes; it never picks your model for you. models gives each worker a default model for targets that name none (-W codex, a "codex" fallback); a model in the target or -m still wins. tiers names workers for --tier and for plan tasks' **Worker:** lines:
config.json: an example and what each setting does
{
  "worker": "opencode",
  "fallback": ["opencode:opencode/space-bunny-free", "codex"],
  "models": { "codex": "gpt-6.1-sol", "claude": "claude-sonnet-5-5" },
  "costs": { "codex:gpt-6-sol": 1, "codex:gpt-6.1-sol": 2 },
  "tiers": { "cheap": "opencode", "standard": "codex", "capable": "claude", "review": "opencode:opencode/space-bunny-free" },
  "timeout": "20m",
  "primary": "opus",
  "link": ["node_modules"],
  "maxParallel": 20,
  "audit": 0.1
}
workerandfallback: who runs a task when you name no one, and who takes over when it fails;models: the model each worker uses when a target names none.tiers:cheap,standardandcapablename the workers for plan tasks and--tier; an optionalreviewtier names who reviews a run (by default another worker than the implementer's,standardfirst).audit: the chance (0 to 1, default 0 = off) that a finished read run is re-checked in the background, see Audits. Theaudittier (elsecheap) names who does it.costs: your relative cost perworker:model, only compared with each other;maxParallel: workers at once (default 20, at most 30).workerPrices: USD per 1M tokens of a worker model, for the CLIs that report no cost (Codex, Gemini):"workerPrices": {"codex:gpt-6.1-sol": "1.25,10,0.125"}is "in,out[,cachedIn]", keyedbackend:model(the model that ran, else the one you asked for) orbackendalone. Without one the receipt saysworker cost n/aand the run counts as free in the savings, which overstates them (pitroom doctorwarns); with one the cost is estimated from the tokens, shown as~$0.016 (estimated from your workerPrices), kept in the ledger, history and dashboard, and taken off the savings. Pitroom knows no vendor prices and does not fetch them, so this is your number.priceFeed: keep a price catalog up to date (defaultfalse;PITROOM_PRICE_FEED=1). The catalog is the public models.dev list OpenCode also reads (USD per 1M tokens of about 8,000 models): at most once a day (priceFeedHours, default 24), in a background process after a run, never while a run waits, Pitroom sends a plainGETfor that one file (priceFeedUrl/PITROOM_PRICE_FEED_URLto use a mirror,priceFeedHours/PITROOM_PRICE_FEED_HOURSfor the interval) and keeps a trimmed copy (about 400 KB) in its state directory; a failed refresh keeps the old copy and is not retried for an hour. It is only a fallback: yourworkerPricescome first, and the receipt says which was used (estimated from models.dev prices). With it,"primary": "<model id>"can name any model of the catalog for the savings comparison ("primary": "claude-opus-5-5"), where without it only the four presets exist.pitroom pricesshows the feed, the catalog and the price each worker in use gets;pitroom prices --refreshfetches now. What it sends: PRIVACY.md. The listed prices are API list prices: a worker on a subscription (Codex with a ChatGPT account) does not pay them, so for such a worker the estimate is what the same tokens would cost on the API.notify: a desktop notification when a run that went to the background (--bg, a crew, an MCP call) has ended, so a long job does not have to be watched (defaultfalse;PITROOM_NOTIFY=1). Runs that went well but took less thannotifyAfterseconds (default 15;PITROOM_NOTIFY_AFTER) and audits are not announced (a failure always is), and a crew says so once, when its last run ends, judged as a whole. A worker process that is killed outright never gets to say so. The built-in notifier usesosascripton macOS andnotify-sendon Linux (none for Windows yet);notifyCommandruns a command of your own instead, in a shell, with the text inPITROOM_NOTIFY_TITLEandPITROOM_NOTIFY_BODY(andPITROOM_NOTIFY_RUN,PITROOM_NOTIFY_STATE): for example"notifyCommand": "curl -s -d \"$PITROOM_NOTIFY_BODY\" ntfy.sh/my-topic".mcpDash: whether a run that an MCP client starts, and that is still going after a few seconds, also starts the dashboard and returns its address (defaulttrue;PITROOM_MCP_DASH=0or"mcpDash": falseturns it off), see the MCP server.auditFixandauditFocus: send a disputed answer back to its worker for one correction, and lean the audit sample to list and count questions and to disputed workers (both defaultfalse;PITROOM_AUDIT_FIX,PITROOM_AUDIT_FOCUS), see






