
Kibi
MCP server for Kibi's requirements, traceability, and proof workflows in coding agents.
Runs on your machine from its package; the steps are below.
What it does
- Reads
- Writes
- High impact
At most: creates or changes data: records, files, settings.
What it costs
FreeOdel charges nothing per call. The publisher may charge for its own service.
Runs locally over stdio
This server isn't hosted — your MCP client launches it from a package registry. Use one of the commands below, or drop the config into your client (e.g. Claude Desktop).
Run
npx -y kibi-mcp
MCP client config
{
  "mcpServers": {
    "kibi": {
      "command": "npx",
      "args": [
        "-y",
        "kibi-mcp"
      ]
    }
  }
}



Prompt the intent. Kibi makes the agent remember it—and prove the implementation.
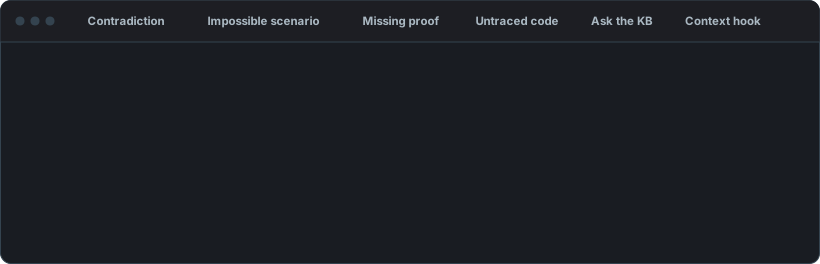
Simplified from what Kibi reports in each case.
Kibi is an agent-native requirements compiler and enforcement layer. You describe product intent in natural language; the agent creates and maintains the structured requirements, scenarios, tests, semantic facts, and code links. Kibi then checks that the implementation remains coherent with that intent.
Unlike passive memory or retrieval systems, Kibi is designed to place itself in the agent's workflow. The agent does not have to remember to consult a ticket, board, or requirements folder: Kibi's hooks, tools, and validation gates continuously bring the relevant product context back into the work.
Documentation · Quick start · Kibi's own health report
Why Kibi
Most project knowledge is scattered across prompts, tickets, code, and conversations—and most AI agents eventually forget part of it. Kibi turns that knowledge into an enforceable, branch-local model:
- Humans maintain intent, not artifacts — The prompt is the primary authoring interface. Agents own the routine work of creating and evolving requirements, scenarios, tests, facts, and symbol links; humans resolve genuine ambiguity and product decisions.
- Memory is enforceable — Symbols need requirement ownership, requirements need complete semantics and scenarios, scenarios need tests, and proof-bearing tests need fresh execution evidence.
- Prolog guards against drift — Typed properties, predicates, and safe rules let deterministic checks expose contradictions, unsupported invention, and incomplete semantics before they become accepted project knowledge.
- E2E behavior is traceable — Kibi records what an end-to-end test proves, not merely which lines it happened to execute. You can navigate from a symbol to its requirement or from a test to the scenario and intent it verifies.
- Intent survives branch changes — Each Git branch has its own KB snapshot, keeping feature context isolated and available when you return. A detached checkout of a commit no single branch points at (a CI checkout of a SHA, a bisect) still answers reads from a read-only snapshot of that checkout and says so; writes wait until a branch is checked out. A branch created without Kibi's Git hooks starts uncompiled;
kibi status,kibi check, andkibi doctor(andkb_statusandkb_checkover MCP) report that once and point atkibi syncinstead of listing every relationship as missing. - Works across languages — TypeScript and JavaScript symbols are built in. The optional
kibi-plugin-treesitteradds offline symbol extraction for Python, Go, Rust, Java, C#, PHP, C, C++, Bash, Ruby, and Terraform/HCL using pinned WASM grammars. - Optional UI design guard (experimental) —
kibi-plugin-ui, offered by/kibi-bootstrapwhen it finds React or Angular components, makeskb_checkrequire each component to implement a design requirement and flags a component that loses the markers of its agreed pattern (a timeline rewritten as cards). Pixels, colours and spacing stay with your linter. - Keep knowledge local — KB state lives in your repository's
.kb/directory; the Kibi packages send no external telemetry or analytics. Only the documentation website counts visits, with cookieless Umami analytics.
Quick start
Kibi is meant to be set up and driven by your coding agent, so the recommended install is a prompt rather than a list of commands. Kibi requires Node.js 22+. SWI-Prolog is bundled: on Linux (x64 or arm64, glibc 2.28+) and macOS (Apple silicon or Intel) there is nothing else to install. On other platforms, such as Alpine/musl or native Windows (use WSL), install SWI-Prolog 9.0+ and put swipl on your PATH (details).
Recommended: let your agent set it up. Paste this into Claude Code, Cursor, Codex, OpenCode, or any coding agent that can run commands in your repository:
Set up Kibi (https://github.com/Looted/kibi) in this repository, then bootstrap its knowledge base.

1. Install: confirm Node.js 22+ is available. With the package manager this repository already uses, add kibi-core, kibi-cli and kibi-mcp as dev dependencies. Do not skip optional dependencies; the bundled SWI-Prolog runtime is one.
2. Initialize: run every `kibi` command through the package manager's local runner (npm: `npm exec -- kibi <command>`). Run `kibi init`; if it reports a problem, run `kibi doctor` and fix what it names. If this platform has no bundled SWI-Prolog, tell me what to install and stop.
3. Connect: register the project-local `kibi-mcp` server for the agent host you are running in, following https://looted.github.io/kibi/guide/connect-an-agent.html. Prefer project-scoped configuration, and ask me before installing a plugin or changing global settings. Until the kb_* tools are visible to you, use Kibi's CLI JSON routes instead.
4. Bootstrap: run `kibi skills load kibi-bootstrap --format markdown` and follow that skill exactly. It starts by asking me where product intent lives outside the code (issue trackers, wikis, specs) and which sources to trust; read them through the connectors you have and cite them. Show me the complete plan and its hash, and write nothing until I approve it.
5. Verify: run `kibi check` and `kibi status`, fix anything they report, and summarize what was added. Do not commit; I will review the changes.
What happens next:
- Setup. The agent installs the packages, runs
kibi init, and connects itself to Kibi. - Interview. It asks where your product intent already lives (issue trackers such as Jira or YouTrack, wikis, specs) and which of those sources to trust.
- Plan. It reads those sources through the connectors it has and drafts a bootstrap plan. Every requirement in the plan cites the ticket or page it came from. Open questions and conflicts it finds between sources are flagged for you rather than turned into requirements.
- Your approval. It shows you the plan and its hash. Nothing is written until you approve.
- Apply and check. It applies the plan, validates the result, then fills in what the plan could not write, such as scenarios from acceptance criteria and machine-checkable facts for the new requirements. It tells you what it added.
After that, work normally: prompt for features, fixes, and refactors, and the agent keeps requirements, scenarios, tests, and code links in step with the code. How the planner chooses candidates and how a plan is applied and recovered are covered in the MCP reference (kb_plan_bootstrap, kb_apply_plan).
Manual installation
In your repository:
npm install --save-dev kibi-core kibi-cli kibi-mcp
npm exec -- kibi init
kibi init creates the .kb/ layout and installs the Git hooks that keep it in sync. Re-running it completes missing directories and schema files while preserving existing knowledge and schema files. It does not infer product knowledge. Connect your coding agent, then ask it:
Bootstrap Kibi for this repository.
pnpm, Yarn, and Bun work the same way through their local runners; the installation guide has the equivalents, and npm exec -- kibi doctor reports which SWI-Prolog Kibi is using and the package versions of the running engine daemon (a daemon left by another install is replaced by the next Kibi command); it also fails on a branch whose authored knowledge was never compiled into its store and warns when Kibi's Git hooks are not installed. A system SWI-Prolog is only a fallback: Kibi uses KIBI_SWIPL if set, then the bundled runtime, then swipl on PATH. Set KIBI_SWIPL=system to prefer your own install. Do not install with --omit=optional (or pnpm supportedArchitectures that exclude your platform): the bundled runtime is an optional dependency.
Upgrading. After updating the Kibi packages, run kibi migrate (or ask your agent to). It previews a plan and its hash and changes nothing; kibi migrate --apply-safe --approved-plan-hash <hash> applies its automatic steps, and anything Kibi cannot decide for you is listed for review. What each schema version changes is in the CLI reference.
Connect your coding agent
The setup prompt above does this step for you. To do it by hand: every client starts the same project-local kibi-mcp server (npx --no-install kibi-mcp, stdio, working directory = your repository). Optional plugins add bundled skills and hooks on top.
Claude Code
Install the optional kibi-claude plugin from this repository's marketplace. It brings the MCP server, the bundled skills, and advisory hooks that show the agent the linked requirements and tests before it reads or edits code, and before an edit, what the lead requirement must keep true and the decision behind it:
claude plugin marketplace add Looted/kibi
claude plugin install kibi-claude@kibi
Without the plugin, register the server for the project:
claude mcp add --scope project kibi -- npx --no-install kibi-mcp
Cursor
Add Kibi to .cursor/mcp.json:
{
  "mcpServers": {
    "kibi": {
      "command": "npx",
      "args": ["--no-install", "kibi-mcp"]
    }
  }
}
The optional kibi-cursor plugin adds rules, bundled skills, commands, and advisory hooks that show the same requirement context as the Claude Code plugin before reads and edits of linked code. See the Cursor plugin guide.
Codex
codex mcp add kibi -- npx --no-install kibi-mcp
The optional kibi-codex plugin bundles Kibi skills, MCP configuration, and warning-only lifecycle hooks; before apply_patch changes linked code, the hook adds the requirement, what it must keep true, and its decision to the agent's context. Add the Kibi repository marketplace, open Codex, then run /plugins, choose Kibi Plugins, and install kibi-codex:
codex plugin marketplace add Looted/kibi
The repository marketplace is not the official OpenAI Plugin Directory; self-serve plugin publishing is not available there yet. Manual MCP configuration remains fully supported.
OpenCode
Add Kibi to opencode.json. The optional kibi-opencode plugin adds prompt guidance (including what a requirement linked to the file being edited must keep true) and background maintenance:
{
  "mcp": {
    "kibi": {
      "type": "local",
      "enabled": true,
      "command": ["npx", "--no-install", "kibi-mcp"]
    }
  },
  "plugin": ["kibi-opencode"]
}
VS Code
Add Kibi to .vscode/mcp.json:
{
  "servers": {
    "kibi": {
      "type": "stdio",
      "command": "npx",
      "args": ["--no-install", "kibi-mcp"]
    }
  }
}
ZCode and other MCP clients
Any stdio MCP client works with command: npx, args: --no-install kibi-mcp. ZCode also has an optional plugin, installed from a local checkout, whose edit hook shows the same requirement context as the Claude Code plugin; see the ZCode plugin guide. Agents without MCP can use the same operations through the CLI's JSON routes.
Kibi's skill subsystem is the agent-guidance mechanism: four bundled skills cover operation safety, bootstrap, freshness, and traceability. Agents load them with the kb_skills MCP tool (action: "list", then "load") or the equivalent read-only CLI routes, so you do not paste a long system prompt. See agent onboarding for the copy-paste discovery snippet for generic agents.
The MCP server keeps its tool list to 16 tools. kb_search answers plain questions such as "what governs checkout rounding?": besides ranked matches it returns the current requirements that govern the topic, with their linked facts, scenarios, tests, and ADRs (with an excerpt of each decision), and lists superseded requirements separately. For each governing requirement it adds a verdict from the existing contradiction and scenario-feasibility checks, the approved exceptions that exempt it, and what the checks could not decide, and it names the branch and KB snapshot it answered from. Every search result names the branch it searched, and a search on a branch whose store was never compiled says so and points at kibi sync instead of reporting a bare "no results". That answer is discovery, not proof: a requirement no check names is not thereby proven. Precise questions go to kb_query, which besides exact lookups asks the modeled facts directly: {predicate: "permission_rule", where: {actor: "admin"}} returns each rule with its allow or deny effect, {subjectKey: "user.role_assignment", propertyKey: "max_roles"} returns the limit, and {factKind: "predicate_schema"} lists the predicates and argument names an agent can ask about, each answer naming the next call to make. Prose modeling goes through kb_model, and kb_upsert with dryRun: true runs the same validation as the real write, including the commit-time contradiction check for a requirement, without making it. A plan compiled from intent (kb_compile_intent, then kb_apply_plan after you approve its hash) lands in full or not at all: a failing step leaves the knowledge base and the workspace unchanged, and if the agent is interrupted mid-write, its next write completes or rolls back the plan from a journal. Each entity the plan applies is written to its own document, so rebuilding the knowledge base from the checkout keeps it. The MCP reference lists every tool and maps older operation names to them.
See what is proven
npm exec -- kibi report --open
kibi report writes a self-contained kibi-report/index.html and kibi-report/badge.svg from one coverage snapshot. % proven is the share of current requirements with fresh end-to-end proof on the current code; the report lists what is proven, what is missing proof, what contradicts, and what has gone stale. See reading the report.
To publish the report and a clickable badge on GitHub Pages, run npm exec -- kibi init --github, then enable Settings → Pages → Source → GitHub Actions. The GitHub integration guide covers the workflow (docs/examples/github/kibi-report.yml), badge-only publishing, and other package managers. The same guide has a CI step that keeps pull requests mergeable when only .kb/symbols.yaml or a relationship shard conflicts (docs/examples/github/kibi-kb-merge.yml).
For day-to-day inspection, kibi status, kibi search, kibi gaps, kibi coverage, and kibi check are in the CLI reference. When many agents share one repository's engine, KIBI_ENGINE_READ_TIME_LIMIT_MS and KIBI_ENGINE_READ_INFERENCE_LIMIT bound each read; a read that hits its limit fails with QUERY_LIMIT_EXCEEDED instead of returning a partial answer (engine read limits).
How it works
Kibi combines probabilistic interpretation with deterministic verification:
Human prompt
    |
    v
Agent updates code and product knowledge
    |
    v
Requirements + semantic facts/rules + scenarios + tests + symbol links
    |
    v
Prolog coherence checks + traceability gates + fresh E2E evidence
    |
    v
Proven result or explicit, repairable gaps
The agent never writes arbitrary Prolog as trusted truth. It works through typed facts, predicate schemas, and safe logic representations; Kibi validates those encodings before the Prolog layer uses them for inference.
What Kibi enforces
Kibi maintains a canonical traceability and proof chain:
Requirement -> Scenario -> Test
     ^                       ^
     |                       |
 Production symbol     Executable test symbol
For a requirement to be proven rather than merely documented:
- Every production symbol must trace to the requirement it implements.
- Every normative requirement clause must have one complete semantic grounding or remain explicitly unresolved. A requirement that leaves clauses unmodeled while it links (
relates_to) to a requirement modeled with strict facts is blocked: contradictions are only found between grounded facts, so those clauses have to be modeled against the same subject or the older requirement superseded. - Requirements must be specified by scenarios, and tests must verify those scenarios. A scenario that expects success while assuming values a current requirement forbids, alone or only in combination, is reported and blocks proof. That holds for conditional requirements too: "checkout may happen only when the cart total is positive" compiles to a typed rule, so a checkout scenario that assumes a zero cart total is infeasible. A requirement only governs scenarios inside its scope and the validity window of its facts. An intended exception is recorded as an exception requirement (
exempts) that a human approved (approved_by), not by editing the rule, andexempts_claimscan limit it to one clause. An exception withoutapproved_byexempts nothing, and an advisory check says so. A success scenario whose feasibility cannot be decided (for example it assumes a "basket amount" where the rule reads the "cart total") is flagged as unknown, never counted as feasible. - Executable test symbols must identify the code that actually performs the verification.
- Proof-bearing production symbols must be covered by qualifying tests.
- End-to-end evidence must be fresh and bound to the current code snapshot. The one exception is a requirement that only names a UI pattern (
ui_pattern,same_pattern,pattern_marker): a fresh isolated component test proves it, so pattern rules do not need browser tests. Freshness uses repository-relative paths and file contents, so CI and a local checkout of the same commit agree. When the proof command reports results per test, a failing step fails only the tests that own it. Receipt history keeps only the receipts that can still decide proof;kibi proof compacttrims stores written before that. The agent never hand-writes how proof runs:kibi proof inspect --jsonproposes a command integration for the detected test runner (or the command you pass with--command) and returns a hash-bound plan, and applying it withkb_apply_planwrites.kb/proof/integrations.jsonforkibi prove. A plan that can no longer apply (the file already exists, or the runner config changed since planning) is refused as an error (MIGRATION_PLAN_REFUSED) and changes nothing. A command integration is judged as one run, so a suite with an unrelated failing test proves nothing; narrow the command, or have it report results per test.
That makes questions answerable in both directions: which requirement owns this symbol, what this E2E test actually verifies, which requirements lack a scenario or current evidence, and whether two current requirements contradict each other. Code coverage alone cannot answer them: it shows that a test touched a line, not which product behavior was exercised.
Prolog as the safety layer
Suppose the product defines exactly three user roles. Once that constraint is encoded as a strict property or predicate, an agent cannot quietly invent a fourth role and treat it as established intent: Kibi can surface the contradiction or missing authorization deterministically.
Kibi does not report "no conflict" when it could not tell. Numeric constraints are compared exactly ("greater than 0" conflicts with "equals 0"), and a requirement with clauses that are not yet modeled is reported as an incomplete analysis rather than a clean pass. An allow and a deny for the same actor, action and resource contradict: "coaches can read unassigned requests" and "coaches cannot read unassigned requests" ground opposite permission_rule decisions, and kb_check and the write-time check report the pair. Two opposing rules that Kibi cannot decide stay unresolved; when the only missing piece is a key_arguments declaration on a predicate, an advisory check names that predicate. A predicate the agent models for a requirement takes the subject key the requirement already constrains, in the argument its schema names subject or, for a schema without one such as a permission rule, as the predicate fact's own subject key, so the predicate and the requirement's other facts are checked as one subject; a predicate about another subject is not offered as the requirement's grounding.
Prolog does not decide whether the original human intent was correct. It verifies the knowledge that was encoded, while Kibi keeps ambiguity, missing ontology, incomplete grounding, and stale evidence explicit instead of calling them proof.
Why this is possible now
Traditional knowledge bases required specialists to design ontologies, write formal logic, and maintain every mapping by hand. LLMs change the economics of that authoring step, and Kibi and Prolog supply the discipline:
| Participant | Strength and responsibility |
|---|---|
| Human | States product intent and resolves real ambiguity or policy choices |
| AI agent | Maps intent to the codebase and maintains requirements, scenarios, tests, facts, and symbol links |
| Kibi + Prolog | Validates schemas, checks coherence and contradictions, enforces traceability, and evaluates proof evidence |
The result uses LLM strengths to address LLM weaknesses: limited memory, hallucination, context drift, and the loss of the product-to-code mapping traditionally spread across product owners, ticket systems, and planning boards.
What Kibi models
Eight entity types: req, scenario, test, fact, adr, flag, event, and symbol. The entity schema has the complete model.
Use flag only for real runtime or configuration gates. Bug and workaround notes are fact records with fact_kind: observation or meta; such a note may quote the claim it is about in claim_text without a claim_key, because it grounds nothing. Adding a relationship (for example a scenario's specified_by) to an existing requirement with kb_upsert keeps the requirement's stored semantic inventory, so the agent does not resend it.
Every entity can record who authored it: origin: {kind: human | agent | migration | import, ref, approved_by, recorded_at}. An agent's kb_upsert records new entities as kind: agent and never rewrites an existing origin by omission. Advisory checks list agent-authored requirements that no person has approved, exception approvals that only an agent recorded, and human- or agent-authored requirements that do not say why they exist (an optional rationale field, a Rationale section, or a linked ADR answers that). Kibi cannot verify a person's approval; it makes the missing ones visible. Other advisory checks flag code whose only owning requirements were superseded, ADRs nothing links to or that were never accepted, and one subject or claim minted as several facts.
Packages
Install kibi-core, kibi-cli, and kibi-mcp in the project. Everything else is optional.
| Package | Role |
|---|---|
kibi-core | Prolog-backed knowledge graph, inference, and validation |
kibi-cli | Human, agent, automation, and Git-hook interface |
kibi-mcp | MCP surface exposing the public Kibi operation contracts |
kibi-claude | Claude Code skills, MCP, requirement context before reads/edits, and advisory hooks (plugin marketplace) |
kibi-cursor | Cursor rules, skills, MCP, requirement context before reads/edits, and advisory hooks |
kibi-codex | Codex skills, MCP, requirement context before edits, and lifecycle hooks |
kibi-opencode | OpenCode guidance (including requirement context for edits) and background maintenance |
kibi-zcode | ZCode skills, command, MCP, requirement context before edits, and advisory hooks (local checkout) |
kibi-vscode | VS Code knowledge explorer and traceability view |
kibi-plugin-sdk | Protocol types and validators for capability plugins |
kibi-plugin-builtin | Default semantic, ontology, and TypeScript symbol capabilities |
kibi-plugin-jev | Optional TypeSafe Jev semantic classifier |
kibi-plugin-treesitter | Optional offline multi-language symbol extraction (tree-sitter WASM grammars) |
kibi-plugin-ui | Experimental check policy keeping UI components on their agreed design patterns |
kibi-swipl | Bundled SWI-Prolog runtime; the matching platform build installs automatically |
Documentation
The guide and reference are published at https://looted.github.io/kibi/. Language models can start from the documentation index.
- Installation — the bundled SWI-Prolog runtime, package managers, plugins, and verification
- How Kibi works and the proof ladder
- Proving requirements — proof contracts,
kibi prove, and receipts - CLI reference and MCP reference
- Entity schema and inference rules
- Architecture — storage, branch isolation, and data flow
- Troubleshooting
Beta status
Kibi is in beta and ready for use in real projects. Public interfaces may still evolve before 1.0, so pin exact package versions when reproducibility matters.
Kibi is licensed under AGPL-3.0-or-later.







